

File Allocation Methods in OS
Overview
File allocation is how an operating system decides which disk blocks hold a file's data, and how it keeps a record of that mapping so the file can be read back later. Three methods do this job: contiguous, linked and indexed allocation, and each solves the problem in a genuinely different way.
This page walks through all three, plus two real-world schemes built on top of them: the File Allocation Table and the inode. If you've already read the theory somewhere else and just want the arithmetic, actual block numbers, actual disk access counts, jump straight to the worked example below. For the wider picture of how an OS handles files beyond block placement, there's also our guide to file management in an operating system
What is File Allocation in OS?
Every time a disk gets formatted, it's carved into small, fixed-size chunks called blocks or sectors. File allocation methods are just the rules for which blocks a file gets and how the OS remembers that assignment afterward, so it can find the file again next Tuesday. Quick disambiguation, since the phrase gets reused: this page is about disk blocks, not RAM. If you meant how a running process gets memory pages, that's a different topic (and a different kind of headache).
Types of File Allocation Methods in Operating System.
- Contiguous File allocation
- Linked File Allocation
- Indexed File Allocation
- File Allocation Table (FAT)
- Inode
Let's have an in-detail explanation about each of them,
Contiguous vs Linked vs Indexed Allocation: Comparison Table
Before getting into each method on its own, here's the short version side by side. Operating System Concepts by Silberschatz, Galvin and Gagne covers this comparison in textbook depth, but the table below is closer to what you'd actually want open during revision.
| Method | How blocks are tracked | Access type | External fragmentation | Internal overhead | Random-access cost | Best suited for |
|---|---|---|---|---|---|---|
| Contiguous | Directory stores start block + length; blocks sit at consecutive addresses | Sequential and direct | Severe — free space fragments into unusable holes, needs compaction | None per block; only last-block internal fragmentation | 1 disk access — address = start + logical block number | Write-once / read-only media (CD-ROM, DVD, ISO 9660), swap areas, fixed-size files |
| Linked | Each block stores a pointer to the next; directory stores first and last block | Sequential only | None — any free block is usable | 4 bytes per block for the pointer (~0.4% of a 1 KB block); one lost pointer orphans the rest | L + 1 disk accesses for logical block L — must walk the chain | Files read start to finish (logs), files that grow unpredictably, FAT-based removable media |
| Indexed | A dedicated index block holds an array of block pointers; directory stores the index-block number | Sequential and direct | None | One full block per file — wasteful for small files; caps max file size | 2 disk accesses (index, then data); 1 if the index block is cached | General-purpose random-access filesystems; UNIX/Linux inodes, NTFS |
Build an AI-First Career, Master the Complete Skillset
Choose from our industry-leading programs designed for career success
Modern Software and AI Engineering Program
Master full-stack development with AI integration


 +1000 more
Modern Data Science and ML with specialisation in AI
Advanced data science techniques with AI specialization
+1000 moreAdvanced AIML with Specialisation in Agentic AI
Deep dive into AIML with focus on Agentic systems
+1000 moreDevOps, Cloud & AI Platform Engineering
Build and manage AI-powered cloud infrastructure
+1000 moreAI Engineering Advanced Certification by IIT-Roorkee
Premier AI engineering certification from IIT-Roorkee

AI Forward Deployed Engineer Program
Full-stack engineering, production AI and client-facing consulting
+1000 moreWorked Example: Finding a Block's Disk Address Under Each Method
Theory is fine until an exam hands you real numbers and asks how many disk accesses it takes to read block 4. So here are real numbers.
Setup: a 64-block disk, 1 KB (1,024-byte) blocks, and a 6-block file called report.txt. Block pointers cost 4 bytes each. Keep these numbers handy, they resurface in the FAQ.
Case 1: Contiguous allocation
● Directory entry: (report.txt, start = 19, length = 6)
● Blocks occupied: 19, 20, 21, 22, 23, 24 — one right after another
● Address formula: physical block = start + logical block number = 19 + L
● Random access to logical block 4: 19 + 4 = physical block 23. One disk access. Done.
● Byte offset 4,500: block = ⌊4500 / 1024⌋ = 4; offset = 4500 − (4 × 1024) = 4500 − 4096 = 404
● So byte 4,500 sits at physical block 23, offset 404, reached in a single seek
● Usable capacity: 6 × 1,024 = 6,144 bytes. No pointer overhead, because there are no pointers.
Case 2: Linked allocation
● Same file, scattered this time: 19 → 27 → 8 → 41 → 33 → 12
● Directory entry: (report.txt, start = 19, end = 12)
● Each 1,024-byte block gives up 4 bytes to its next-pointer, leaving 1,020 usable bytes
● Random access to logical block 4 (physical block 33): read 19, then 27, then 8, then 41, then 33. Five disk accesses. No shortcut formula, you either walk the chain or you don't get there.
● Byte offset 4,500: block = ⌊4500 / 1020⌋ = 4, offset = 4500 − (4 × 10²⁰) = 420 — not 404. Same byte offset as Case 1, different in-block position, because linked allocation eats into every block for its pointer.
● Usable capacity: 6 × 1,020 = 6,120 bytes — 24 bytes gone to pointers (4 bytes × 6 blocks)
Case 3: Indexed allocation
● Index block: block 25, holding index[0]=19, index[1]=27, index[2]=8, index[3]=41, index[4]=33, index[5]=12
● Directory entry: (report.txt, index block = 25)
● Random access to logical block 4: read block 25 first (access 1), find index[4] = 33, read block 33 (access 2). Two disk accesses — or one, if the index block is already sitting in memory.
● Space overhead: one full 1,024-byte block spent indexing a 6,144-byte file, roughly 17% overhead. Steep for a small file, basically free for a large one.
● Maximum file size, single-level index: 1,024-byte index block ÷ 4-byte pointers = 256 pointers → 256 × 1,024 bytes = 262,144 bytes = 256 KB
● Go two levels deep and it jumps to 256 × 256 blocks = 65,536 blocks × 1 KB = 64 MB (more on this under Multilevel Index further down)
Bottom line for reaching logical block 4: Contiguous = 1 seek, Linked = 5 seeks, Indexed = 2 seeks. Write that down, it's basically the whole chapter in one sentence.
Contiguous File Allocation.
First, let's understand the meaning of contiguous, here contiguous means adjacent or touching. Now let's understand what is contiguous file allocation.
What is Contiguous File allocation?
In contiguous file allocation, the block is allocated in such a manner that all the allocated blocks in the hard disk are adjacent.
Assuming a file needs 'n' number of blocks in the disk and the file begins with a block at position'x', the next blocks to be assigned to it will be x+1,x+2,x+3,...,x+n-1 so that they are in a contiguous manner.
Let's understand this diagrammatically.
Example
We have three different types of files that are stored in a contiguous manner on the hard disk.
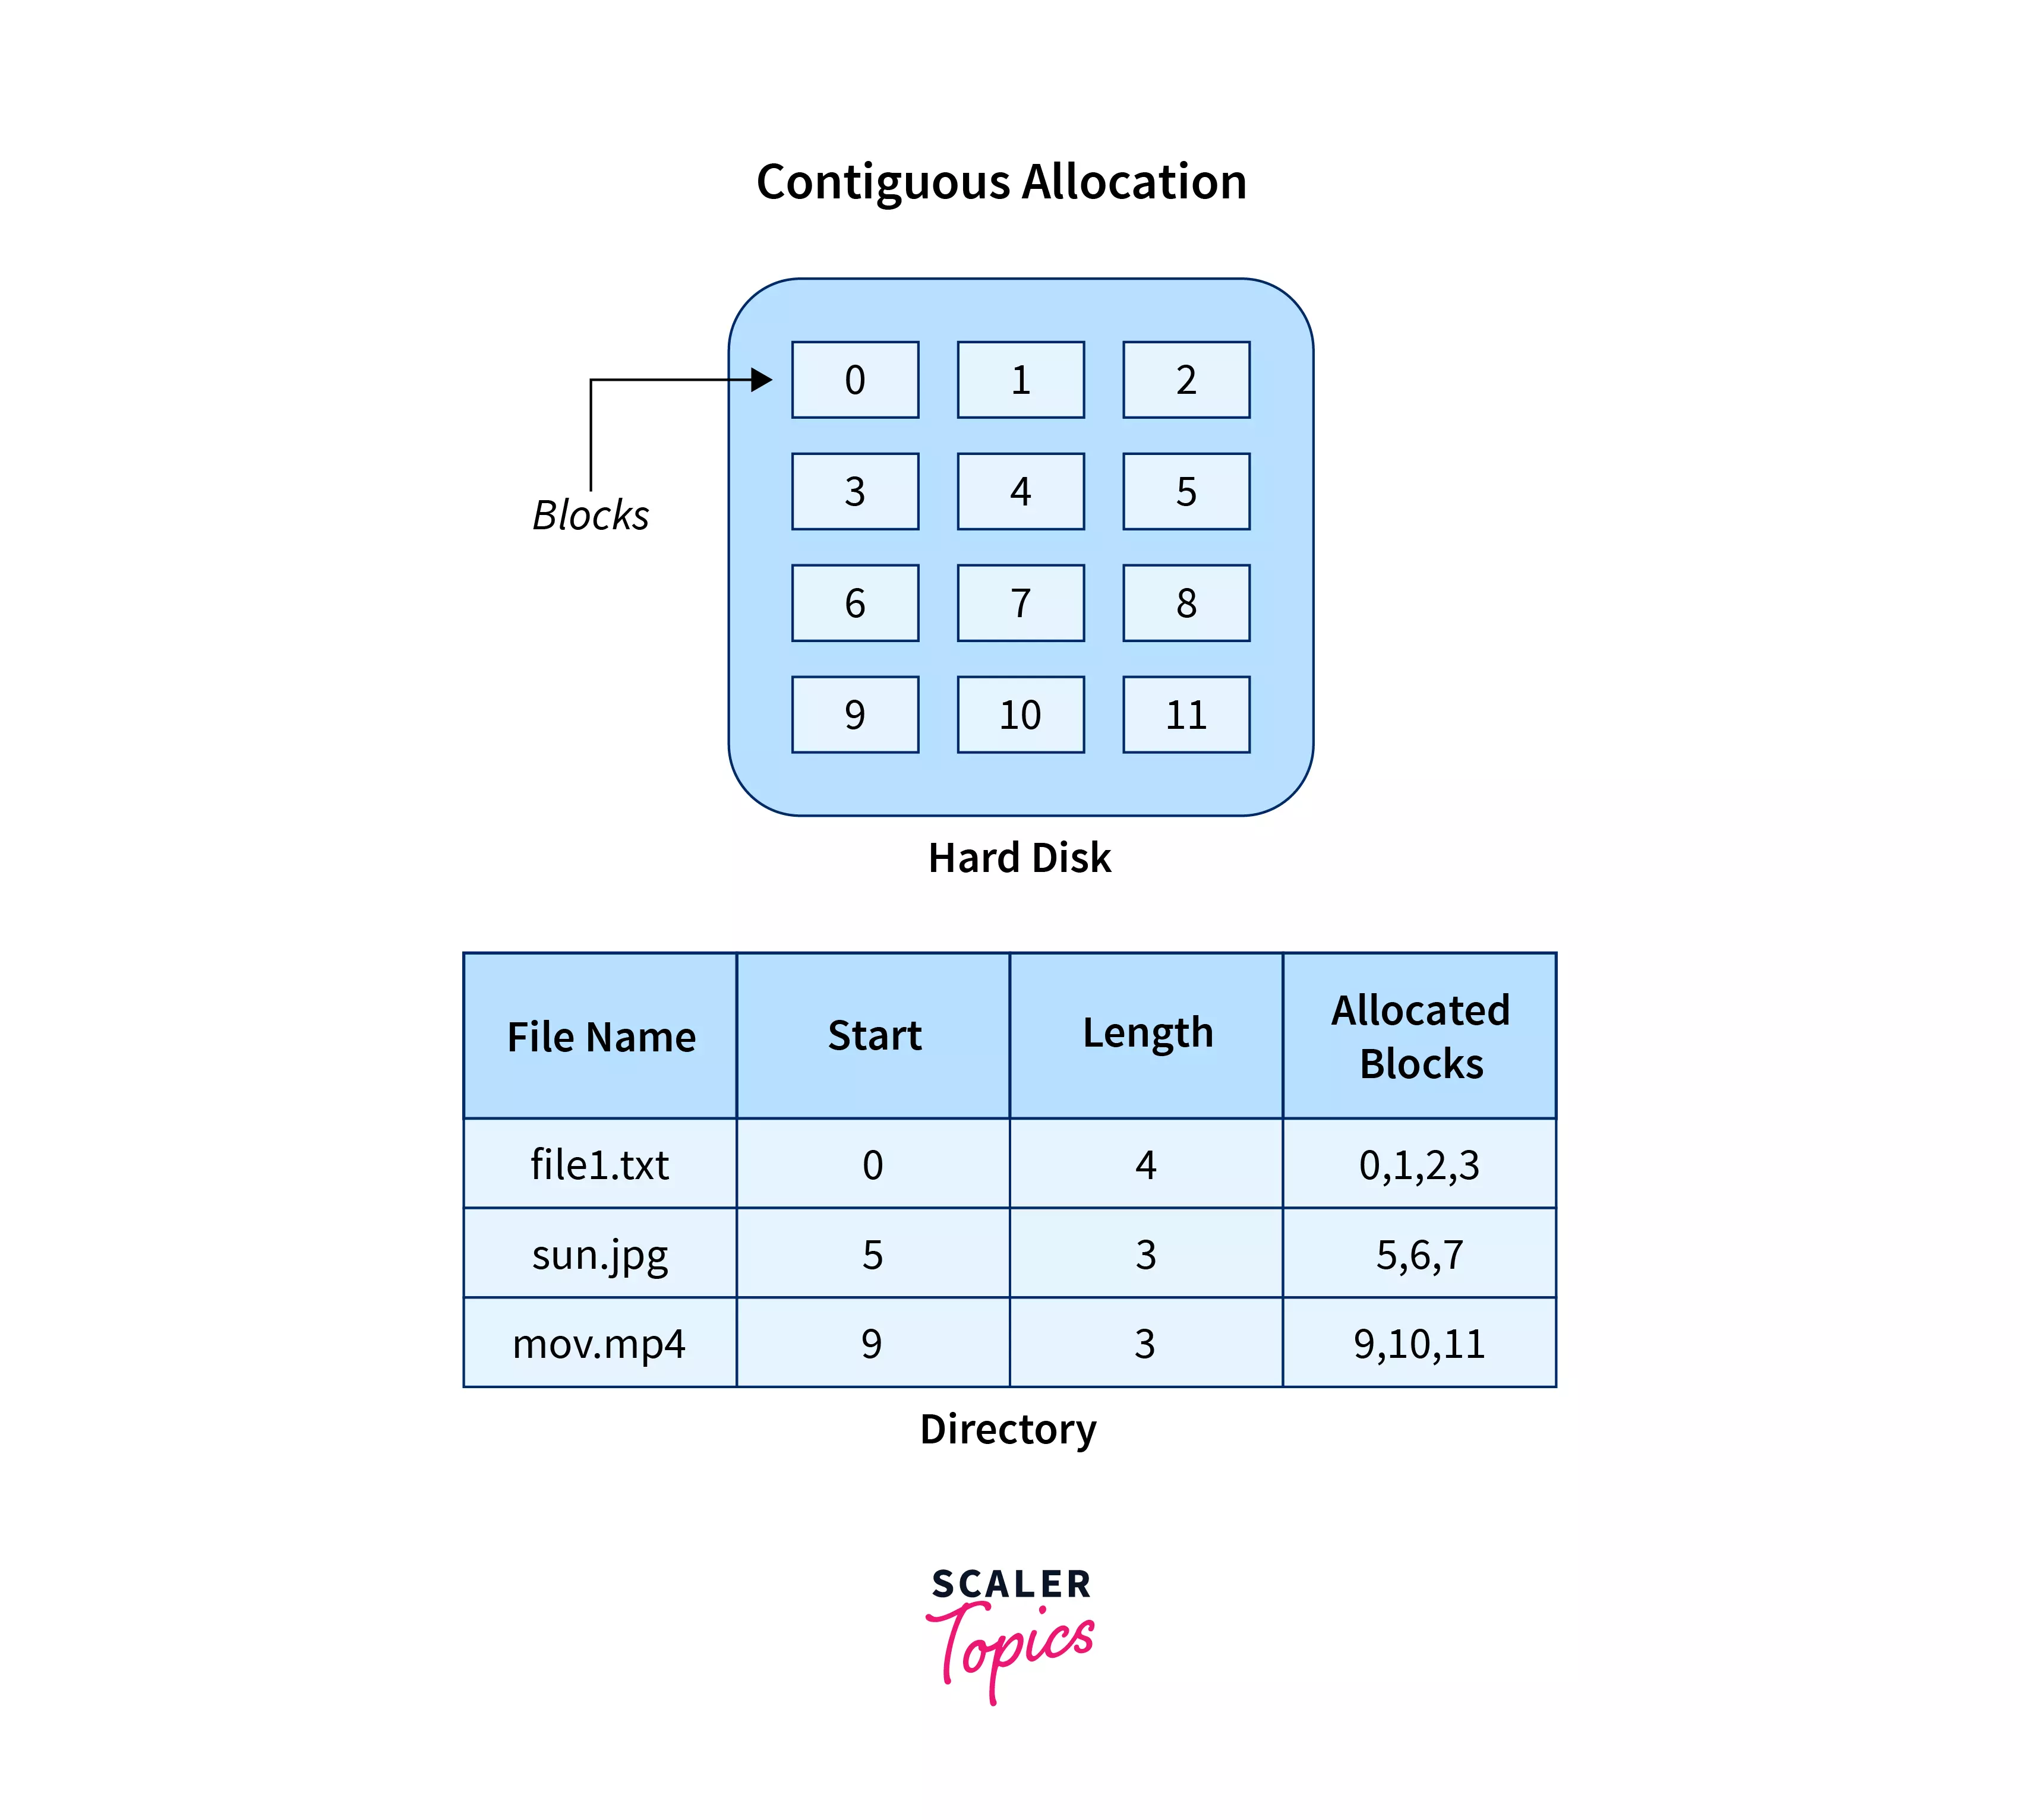
In the above image on the left side, we have a memory diagram where we can see the blocks of memory. At first, we have a text file named file1.txt which is allocated using contiguous memory allocation, it starts with the memory block 0 and has a length of 4 so it takes the 4 contiguous blocks 0,1,2,3. Similarly, we have an image file and video file named sun.jpg and mov.mp4 respectively, which you can see in the directory that they are stored in the contiguous blocks. 5,6,7 and 9,10,11 respectively.
Here the directory has the entry of each file where it stores the address of the starting block and the required space in terms of the block of memory.
Advantages and Disadvantages
Advantages
- It is very easy to implement.
- There is a minimum amount of seek time.
- The disk head movement is minimum.
- Memory access is faster.
- It supports sequential as well as direct access.
Disadvantages
- At the time of creation, the file size must be initialized.
- As it is pre-initialized, the size cannot increase. As
- Due to its constrained allocation, it is possible that the disk would fragment internally or externally.
Linked File Allocation.
What is Linked File Allocation?
The Linked file allocation overcomes the drawback of contiguous file allocation. Here the file which we store on the hard disk is stored in a scattered manner according to the space available on the hard disk. Now, you must be thinking about how the OS remembers that all the scattered blocks belong to the same file. So as the name linked File Allocation suggests, the pointers are used to point to the next block of the same file, therefore along with the entry of each file each block also stores the pointer to the next block.
Let's understand this better diagrammatically by taking an example.
Example
Here we have one file which is stored using Linked File Allocation.
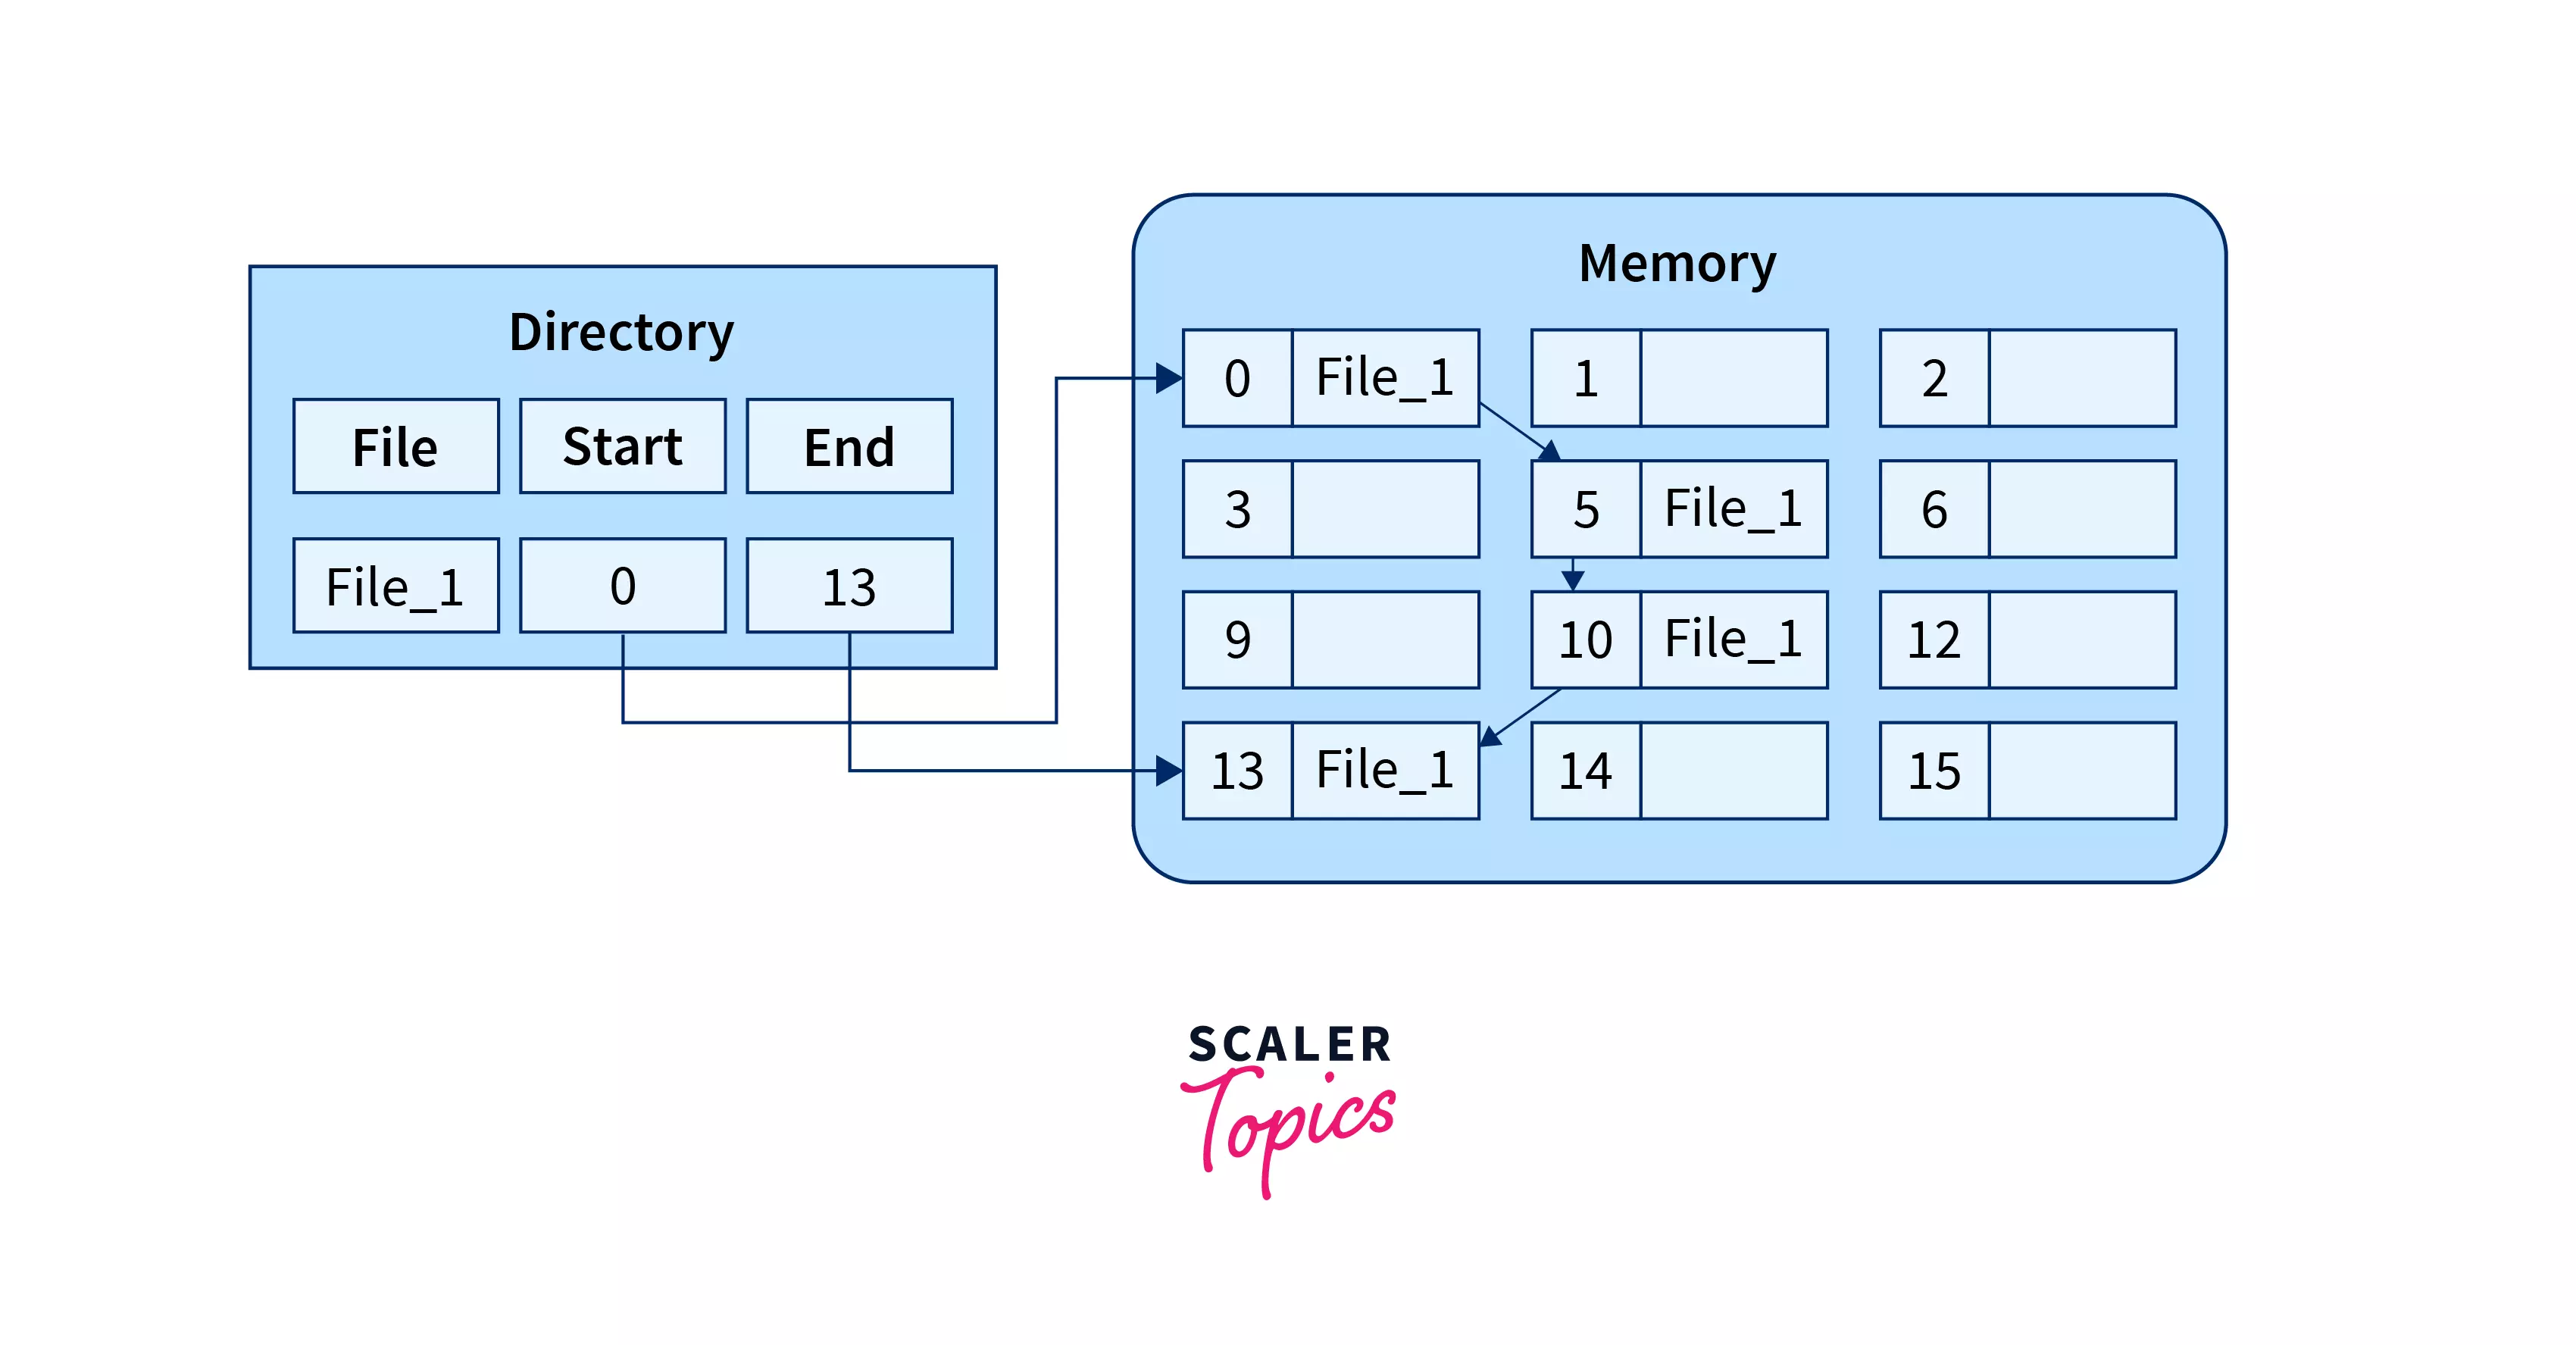
In the above image on the right, we have a memory diagram where we can see memory blocks. On the left side, we have a directory where we have the information like the address of the first memory block and the last memory block.
In this allocation, the starting block given is 0 and the ending block is 15, therefore the OS searches the empty blocks between 0 and 15 and stores the files in available blocks, but along with that it also stores the pointer to the next block in the present block. Hence it requires some extra space to store that link.
How Scaler Transformed Careers in Different Fields
Scaler learners achieved 2.5x salary growth with average post-Scaler CTC reaching ₹23L.
 Google
 Amazon
 Microsoft
 Flipkart
 Adobe1200+ more
Advantages and Disadvantages
Advantages
- There is no external fragmentation.
- The directory entry just needs the address of starting block.
- The memory is not needed in contiguous form, it is more flexible than contiguous file allocation.
Disadvantages
- It does not support random access or direct access.
- If pointers are affected so the disk blocks are also affected.
- Extra space is required for pointers in the block.
What is Indexed File Allocation?
The indexed file allocation is somewhat similar to linked file allocation as indexed file allocation also uses pointers but the difference is here all the pointers are put together into one location which is called index block. That means we will get all the locations of blocks in one index file. The blocks and pointers were spread over the memory in the Linked Allocation method, where retrieval was accomplished by visiting each block sequentially. But here in indexed allocation, it becomes easier with the index block to retrieve.
Let's take an example to explain this better.
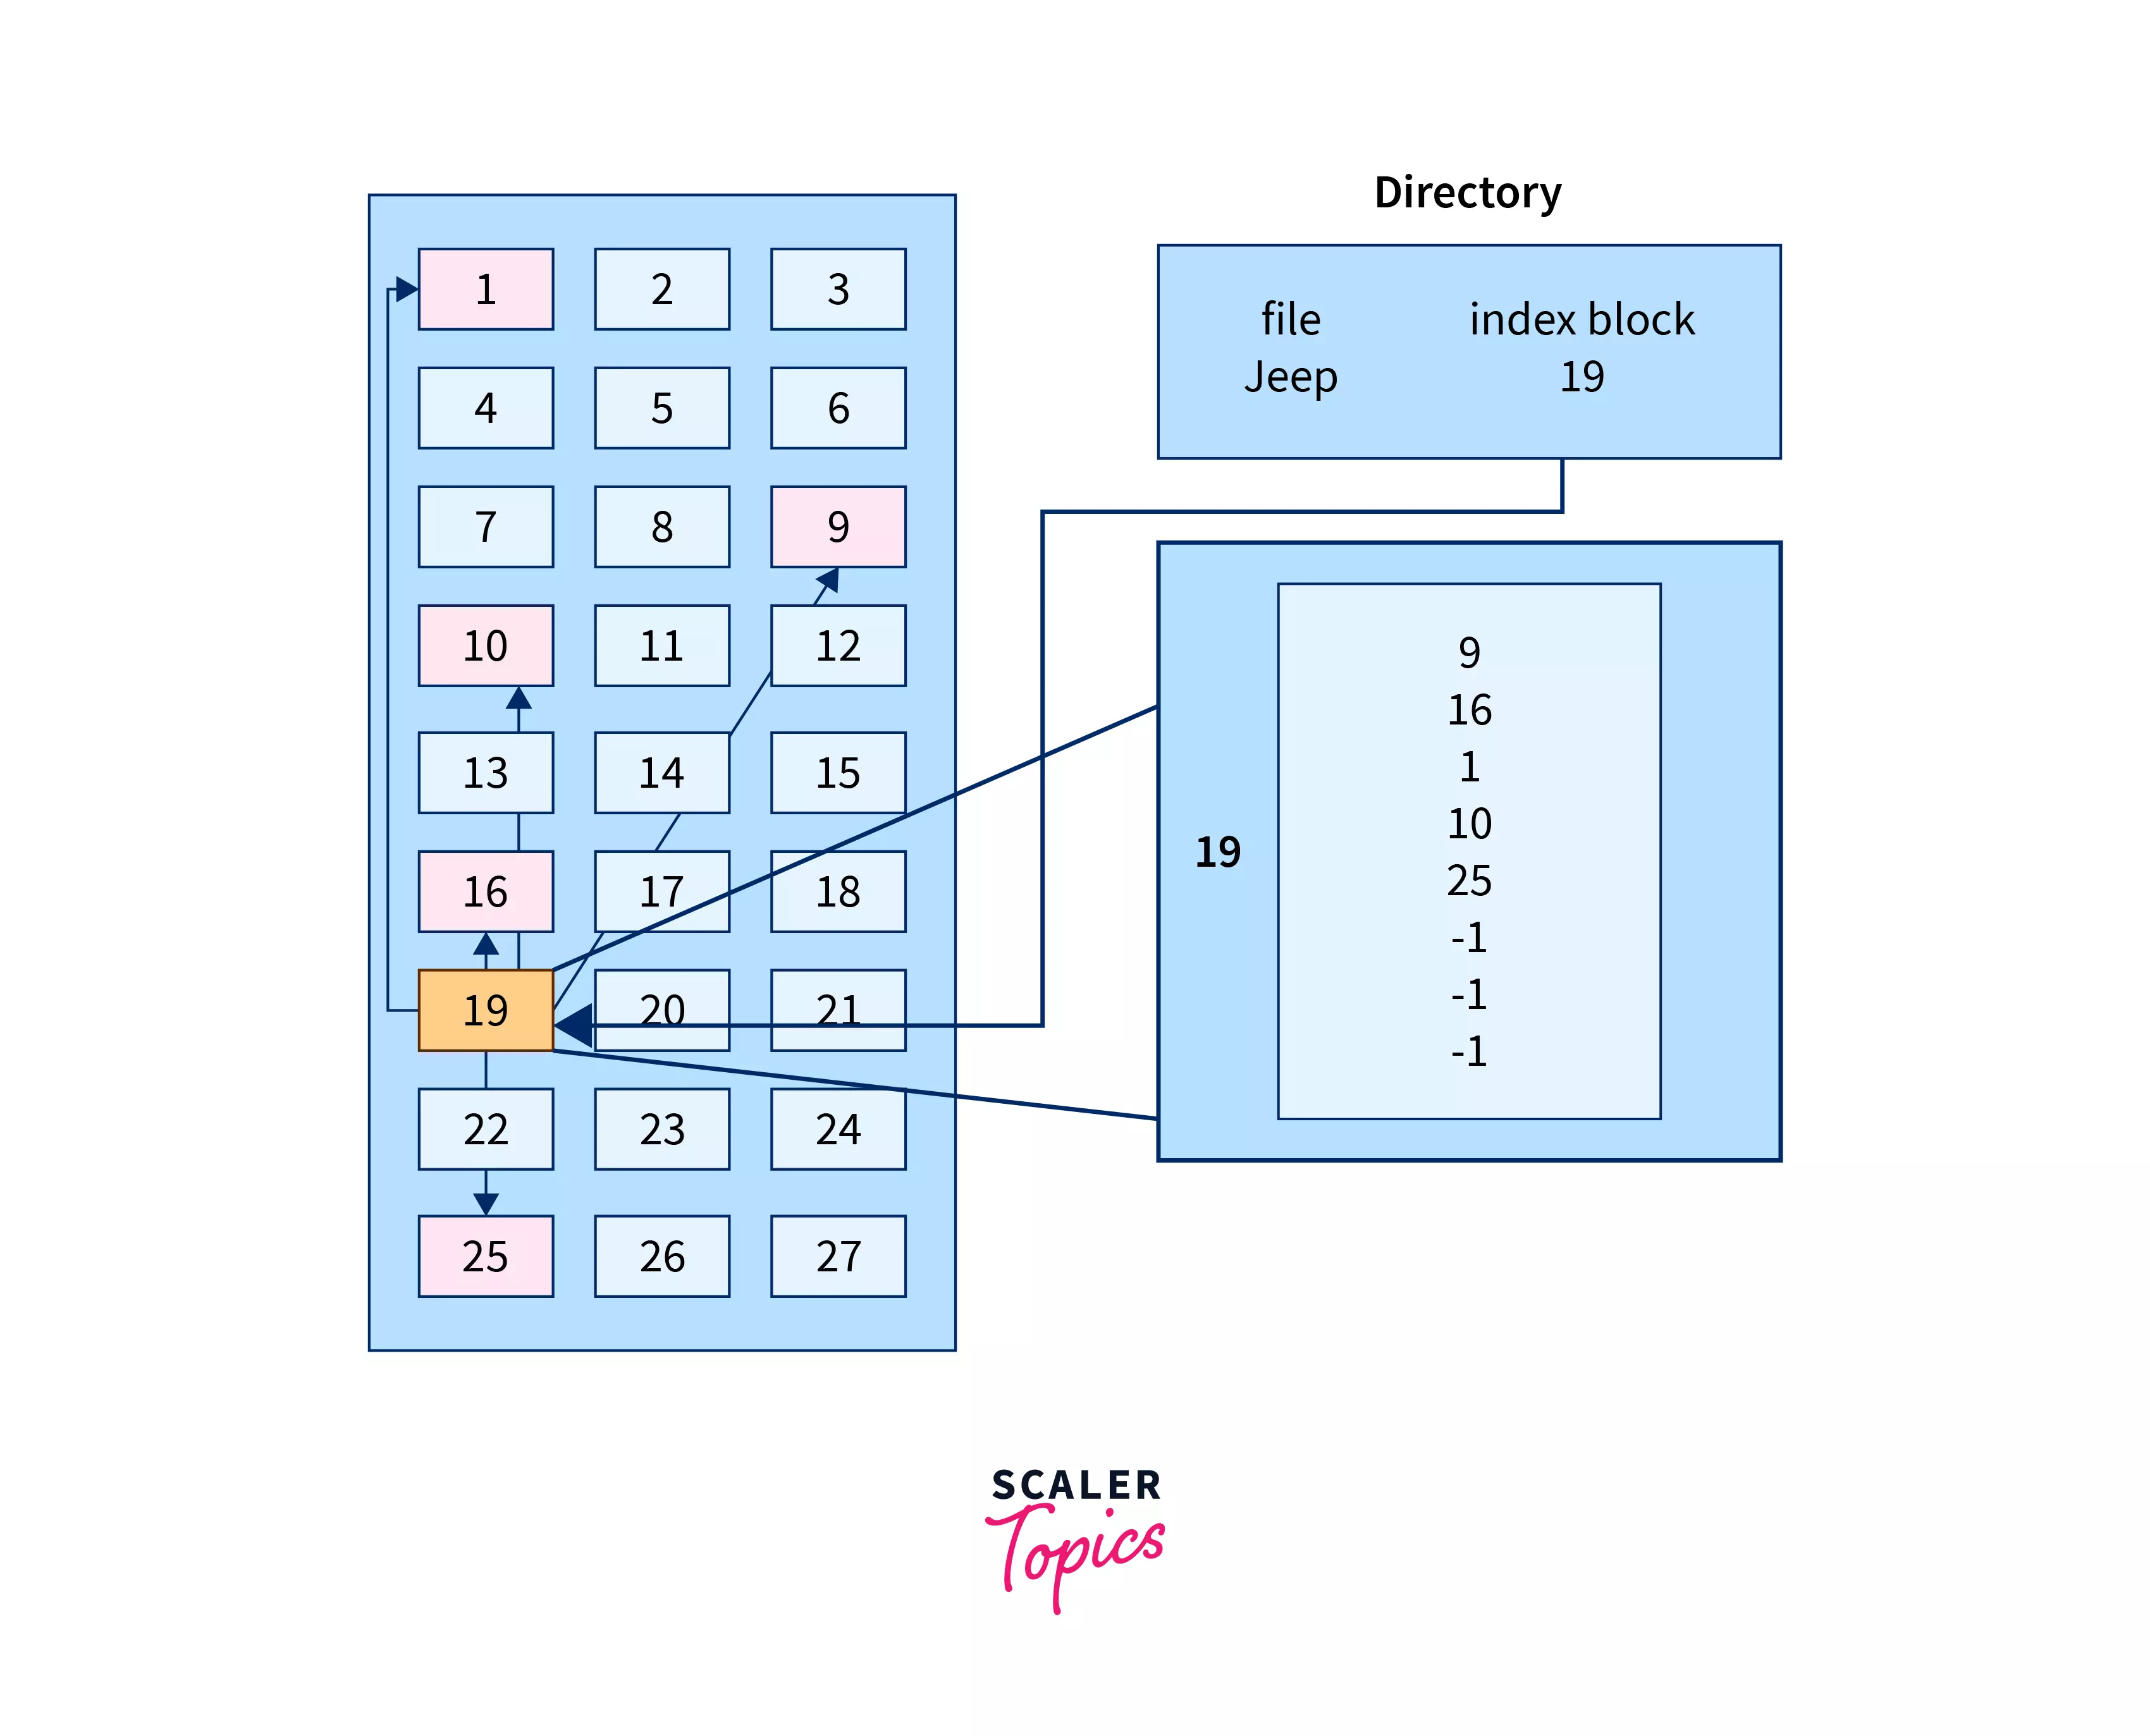
Example
As shown in the diagram below block 19 is the index block which contains all the addresses of the file named text1. In order, the first storage block is 9, followed by 16, 1, then 10, and 25. The negative number -1 here denotes the empty index block list as the file text1 is still too small to fill more blocks.
Advantages and Disadvantages
Advantages
- It reduces the possibilities of external fragmentation.
- Rather than accessing sequentially it has direct access to the block.
Disadvantages
- Here more pointer overhead is there.
- If we lose the index block we cannot access the complete file.
- It becomes heavy for the small files.
- It is possible that a single index block cannot keep all the pointers for some large files.
To resolve this issue, we can use the following approaches:
- Linked scheme
- Multilevel Index
- Combined Scheme
1. Linked Scheme
If the file is big then more blocks are required so one index block is insufficient to store all the pointers, therefore to store the pointers two or more index blocks are used where these index boxes are connected using linked file allocation that is each index block stores the pointer to the next index block.
Turn Learning into Career Growth
2. Multilevel Index
In this method, the multiple indexes blocks along with the levels of these blocks. Here, the level 1 block is used for pointing to the level 2 block which points to the blocks occupied by the file. These index blocks can be extended to three or more levels according to the size of the file.
3. Combined Scheme
In Combined Scheme, a special block is used to store all the information related to the file like name, authority, size, etc. The special block is called inode(information-node). Some space of this special block is used to store the information related to the field as mentioned above and the remaining space is used to store the addresses of blocks that contain the actual file. The inode is explained further in detail.
File Allocation Table (FAT).
The File Allocation Table (FAT) overcomes the drawback of Linked File allocation. The random access of a particular block is not possible in the linked file allocation. To access a particular block it is necessary to access all its previous blocks. Let's see how File Allocation Table works.
Explanation
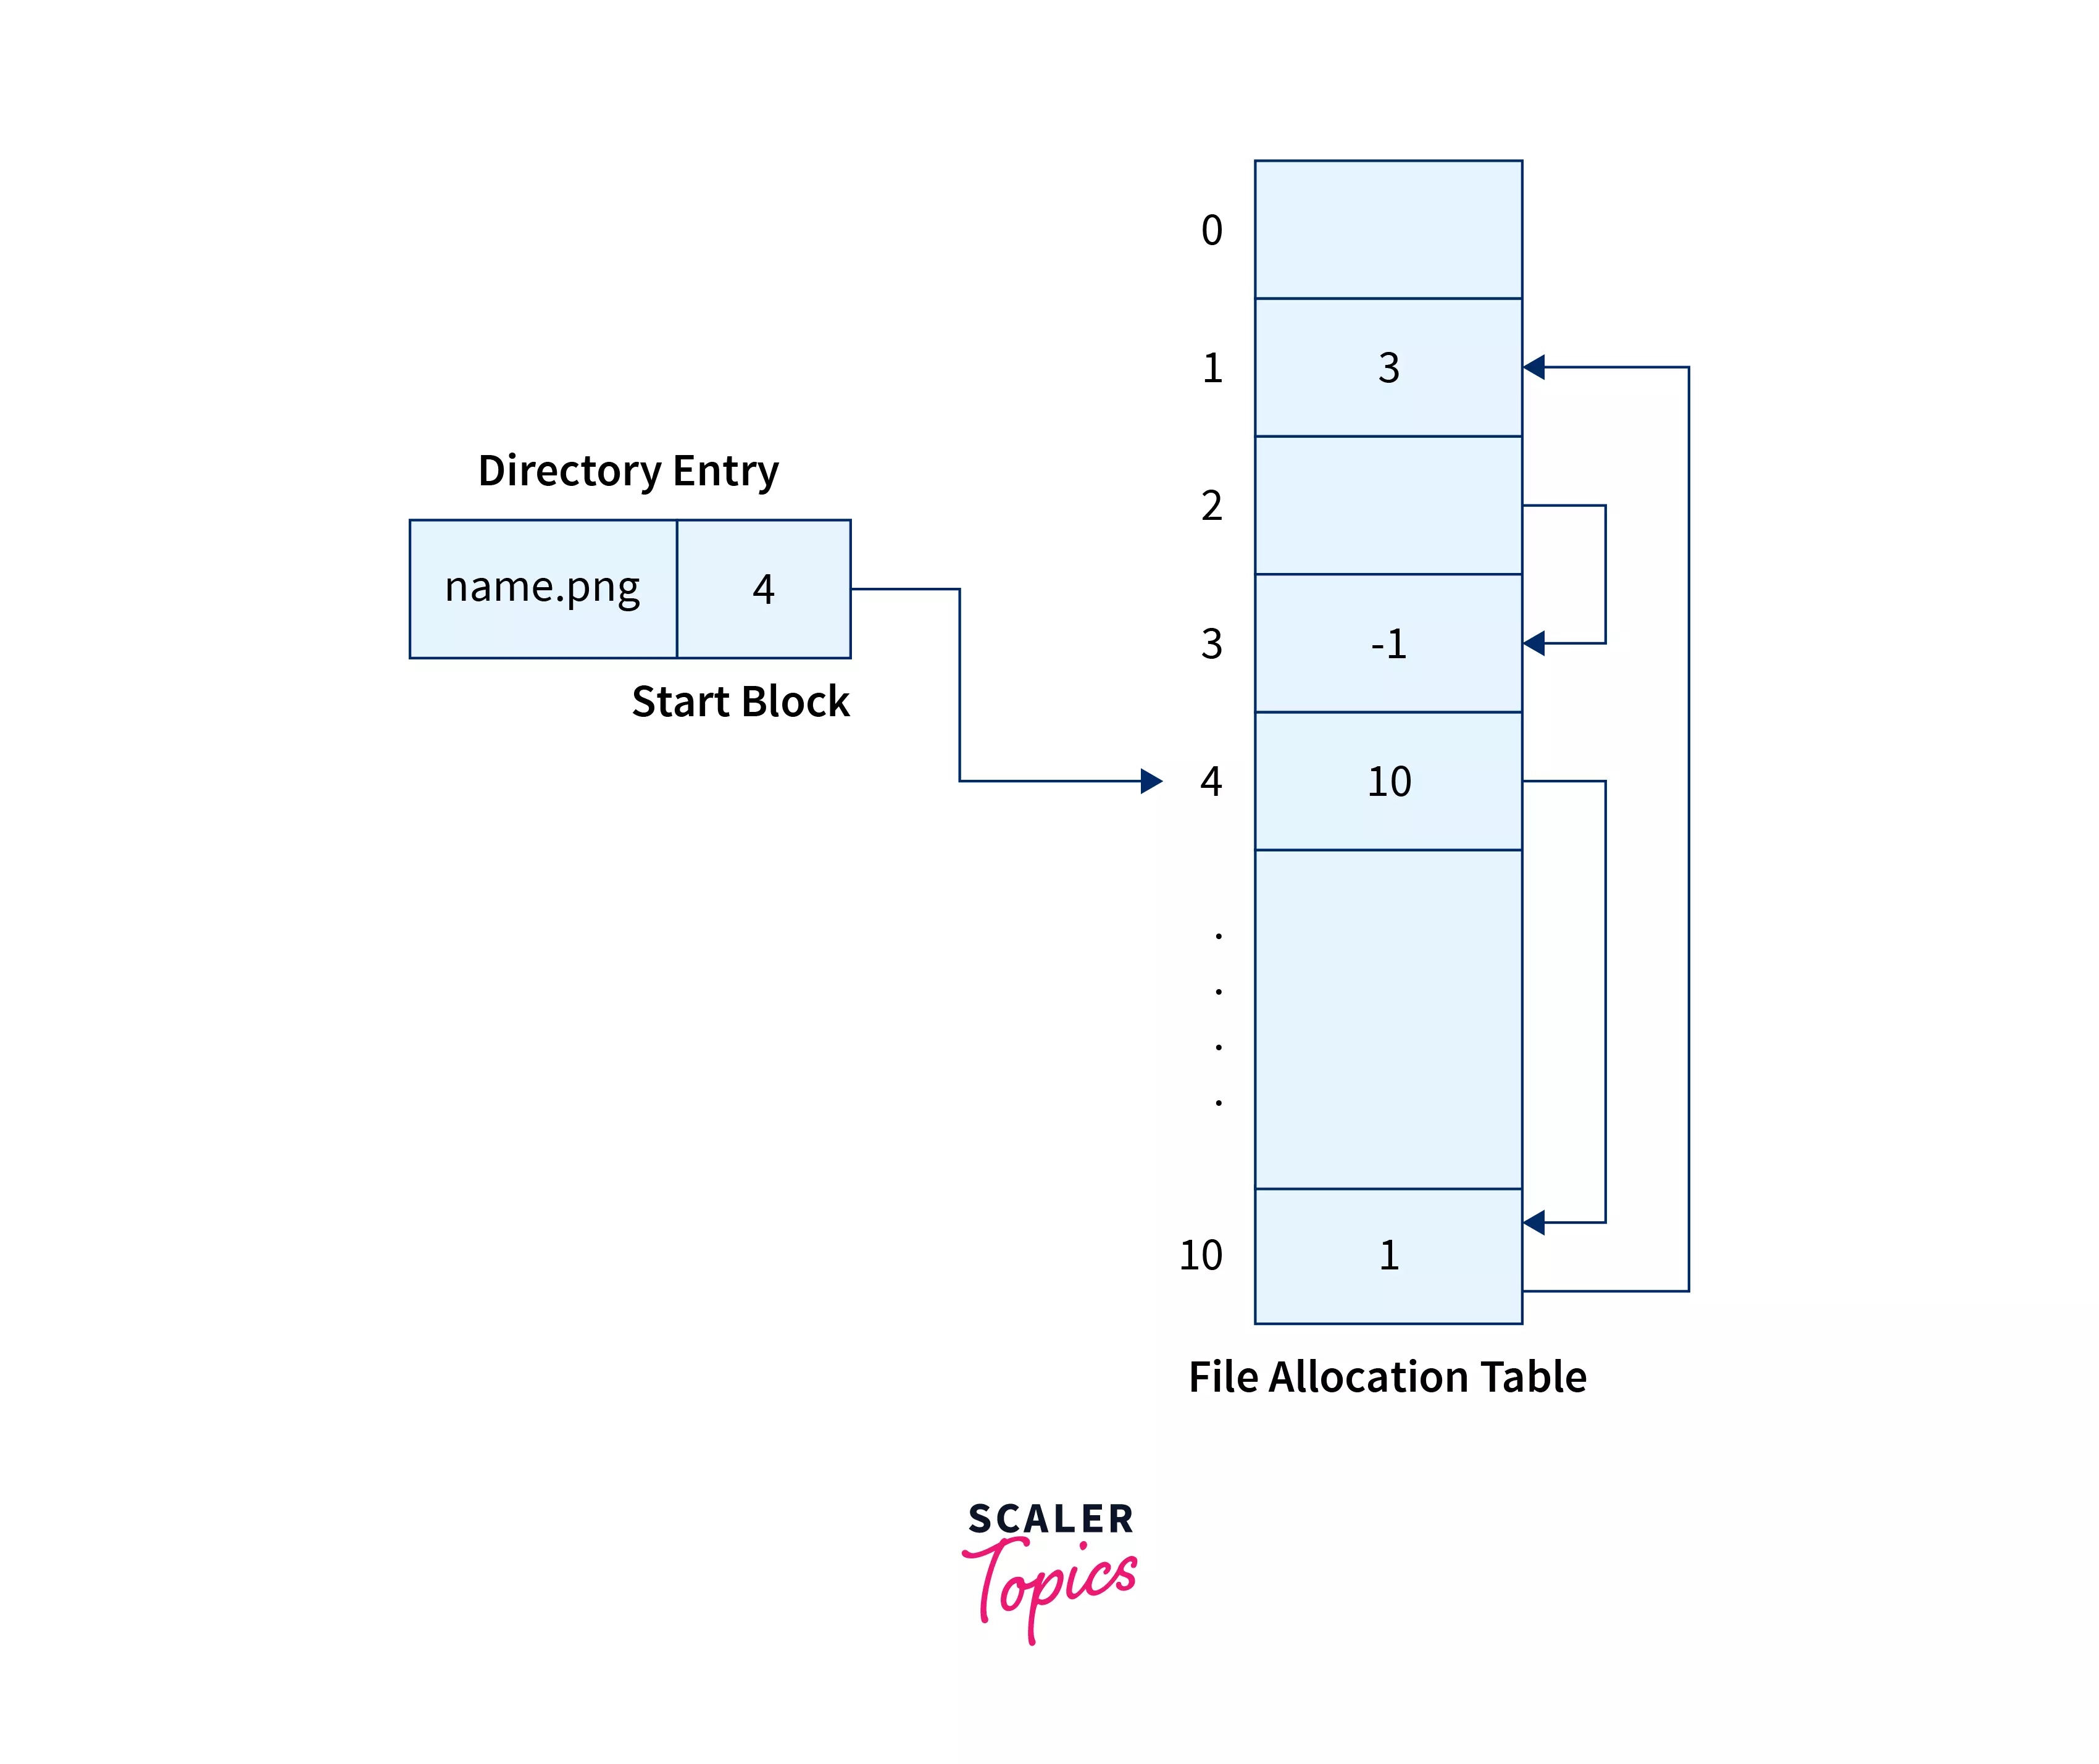
In the file allocation table, all disk block links are collected and maintained. Here the number of head seeks is reduced by caching the file allocation table so that the head does not need to go through all the disk blocks to access one particular block.
The whole process of randomly accessing any block using FAT is completed by reading the desired entry of a block from the file allocation table and accessing that particular block.
The diagrammatic representation of FAT is given below -
Become the Ai engineer who can design, build, and iterate real AI products, not just demos with an IIT Roorkee CEC Certification


AI Engineering Course Advanced Certification by IIT-Roorkee CEC
A hands on AI engineering program covering Machine Learning, Generative AI, and LLMs - designed for working professionals & delivered by IIT Roorkee in collaboration with Scaler.
Enrol Now
Advantages and Disadvantages
Advantages
- Random Access to the block is possible in FAT.
- One bad/corrupted disk block cannot corrupt all the other blocks.
- It uses all the disk blocks for data as in linked file allocation it needs extra space for pointers.
Disadvantages
- If entries increase so the FAT size also increases.
- Each entry requires the FAT entry.
- If Entries increase the FAT size increases which increases the size of a block so there are chances of internal fragmentation.
Inode.
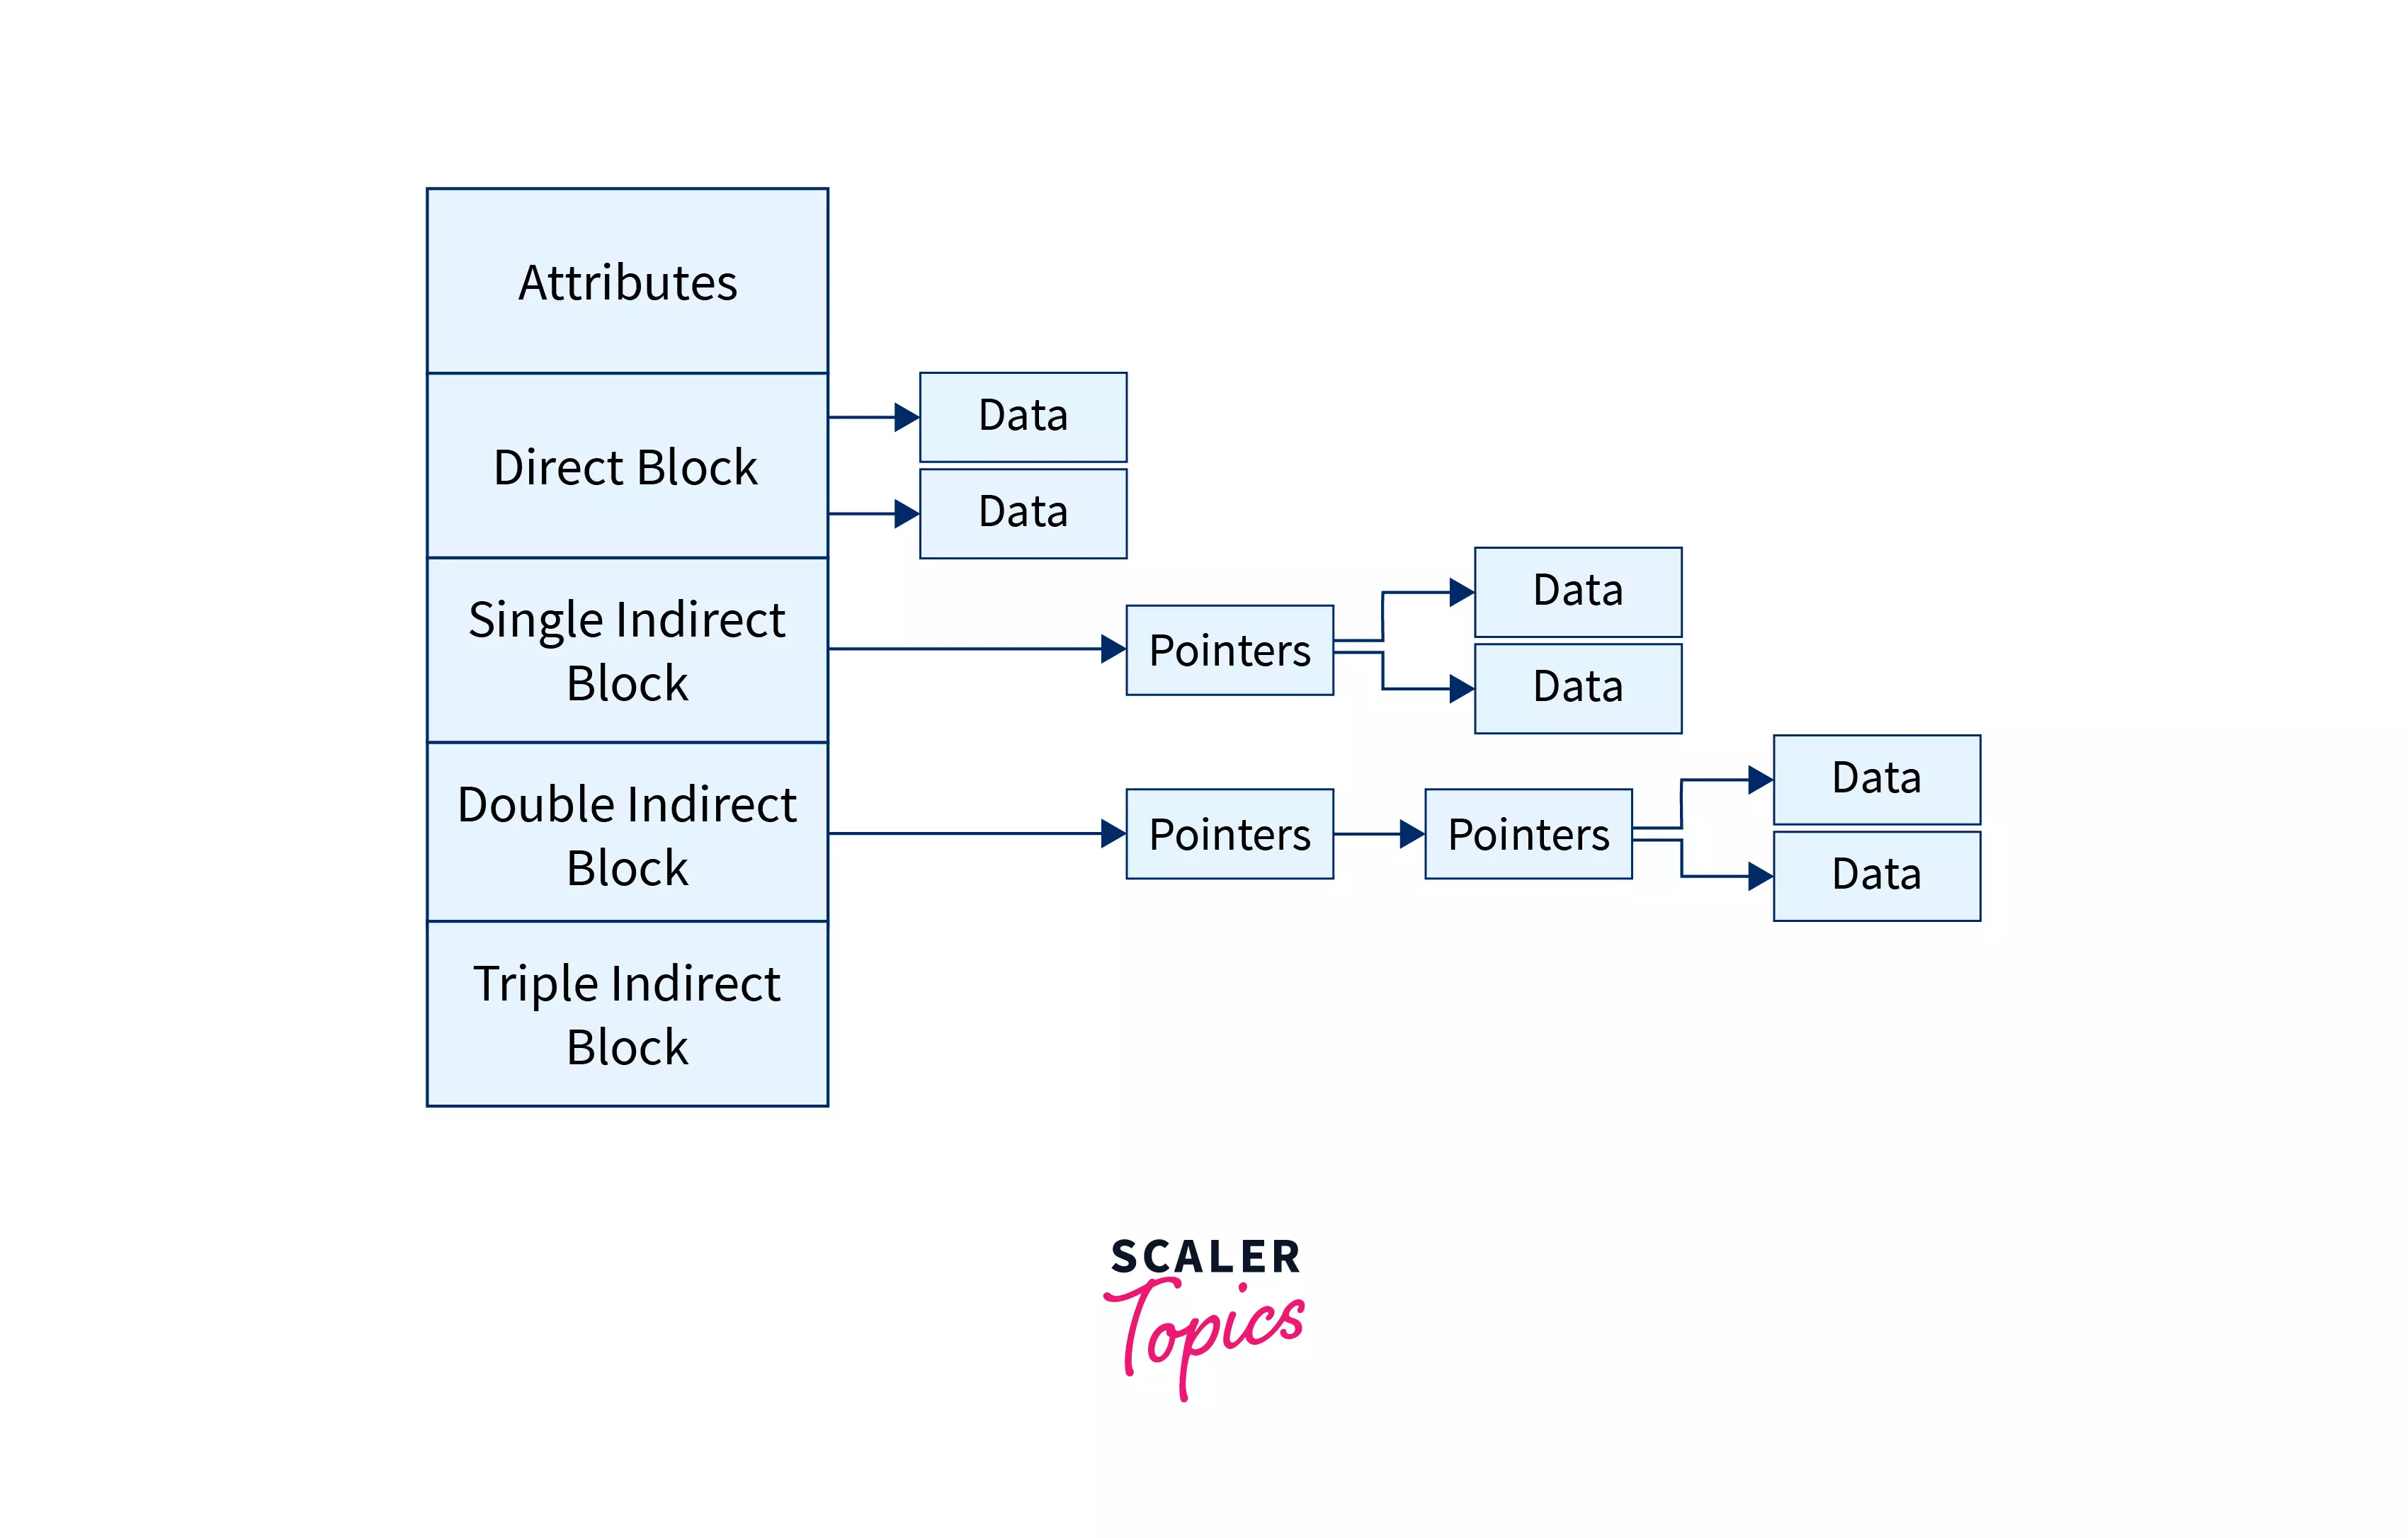
In Operating systems based on UNIX, every file is indexed using Inode(information-node). The inode is the special disk block that is created with the creation of the file system. This special block is used to store all the information related to the file like name, authority, size, etc along with the pointers to the other blocks where the file is stored.
Explanation
In this special block, some of its space is used to store the information related to the field as mentioned above and the remaining space is used to store the addresses of blocks that contain the actual file.
The first few pointers in Inode point to direct blocks, i.e they contain the addresses of the disk blocks containing the file data. A few pointers in inode point to the indirect blocks. There are three types of indirect blocks: single indirect, double indirect, and triple indirect.
A single indirect block contains nothing but the address of the block containing the file data, not the file itself as shown in the figure below. Furthermore, the double indirect block points to the pointers which again point to the pointers which point to the data blocks. Further, it goes in a similar way for triple indirect block.
The diagrammatic representation of Inode is given below -
Advantages and Disadvantages
Advantages
- Accessibility of file becomes easy as all the information like metadata and block address is stored inside inode.
- Read-write and creation timestamps are stored inside the inode.
- Filenames do not affect inodes. In other words, a single file can be copied and renamed without losing its address.
Disadvantages
- All new files and folders will be rejected as soon as a file system runs out of inodes.
- Upon 100% utilization of the inodes system will start to notice OS restarting, data loss, applications crashing, and more OS-related issues.
Conclusion
Let's recall what we have learned in this article,
- File allocation methods are different ways by which the operating system stores information in memory blocks.
- There are 5 types of file allocation methods in OS. Contiguous File allocation, Linked File Allocation, Indexed File Allocation, File Allocation Table (FAT), and Inode.
- In Contiguous file allocation, the block is allocated in such a manner that all the allocated blocks in the hard disk are contiguous(adjacent).
- In Linked file allocation the pointers are used to point to the next block of the same file.
- The Index file allocation is similar to Linked file allocation but here all the pointers are put together into one location which is called an index block.
- Using File allocation table (FAT) we can randomly access the disk block as it maintains the FAT for each file.
- Inode(information-node) contains some metadata about the file and stores all the pointers to the files where it can directly or indirectly access the file.


