


LRU Page Replacement Algorithm in OS: Complete Guide
Overview
The LRU page replacement algorithm (Least Recently Used) is one of the most important page replacement strategies in operating systems. When physical memory (RAM) is full and a program needs a page that isn't loaded, the OS must decide which page to evict. LRU replaces the page that hasn't been used for the longest time, based on the principle of temporal locality recently accessed pages are likely to be accessed again soon.
This article covers everything you need: a clear worked example with step-by-step tables, the comparison with FIFO and Optimal algorithms, Belady's anomaly analysis, and complete C and Python implementations. By the end, you'll be able to trace any page reference string through LRU by hand and write a working implementation.
What is the LRU Page Replacement Algorithm?
LRU stands for Least Recently Used. It is a page replacement algorithm that evicts the page which has not been accessed for the longest time when memory is full and a new page needs to be loaded. The core idea is simple: if a page was used recently, it's probably going to be used again soon. Pages that haven't been touched in a while are safer to replace.
Why LRU works: Programs exhibit temporal locality during execution, they tend to access the same memory locations repeatedly over short periods. Loops run the same code, functions access the same stack frames, and variables are read and written repeatedly. LRU exploits this pattern by keeping recently-used pages in memory and replacing the one that was used furthest in the past. Source: Silberschatz, Galvin & Gagne, Operating System Concepts, 10th Edition
When LRU is used: LRU is widely implemented in CPU caches, database buffer pools, and web caching systems not just operating systems. Redis, Memcached, and many file systems use LRU or LRU-variant eviction policies.
Build an AI-First Career, Master the Complete Skillset
Choose from our industry-leading programs designed for career success
Modern Software and AI Engineering Program
Master full-stack development with AI integration


 +1000 more
Modern Data Science and ML with specialisation in AI
Advanced data science techniques with AI specialization
+1000 moreAdvanced AIML with Specialisation in Agentic AI
Deep dive into AIML with focus on Agentic systems
+1000 moreDevOps, Cloud & AI Platform Engineering
Build and manage AI-powered cloud infrastructure
+1000 moreAI Engineering Advanced Certification by IIT-Roorkee
Premier AI engineering certification from IIT-Roorkee

AI Forward Deployed Engineer Program
Full-stack engineering, production AI and client-facing consulting
+1000 moreKey Terms: Page Fault, Page Hit, and Frame
Before tracing through examples, establish these four terms precisely—they are where most confusion originates.
| Term | Definition | In the Example |
|---|---|---|
| Page | A fixed-size block of logical memory (typically 4 KB) | Each referenced value (1, 2, 3...) is a page |
| Frame | A fixed-size block of physical memory (RAM) that holds one page | The three slots in our memory |
| Page Hit | The referenced page is already in a frame no I/O needed | Shown as a blank cell |
| Page Fault | The referenced page is not in memory the OS must load it from disk | Shown as a page fault |
| Hit Ratio | (Hits) / (Total References) × 100 | Our example: 6 hits / 18 references |
Example of LRU Algorithm in OS
Consider a reference string 1, 2, 1, 0, 3, 0, 4, 2, 4. Let us say there are 3 empty memory locations (or slots) available.
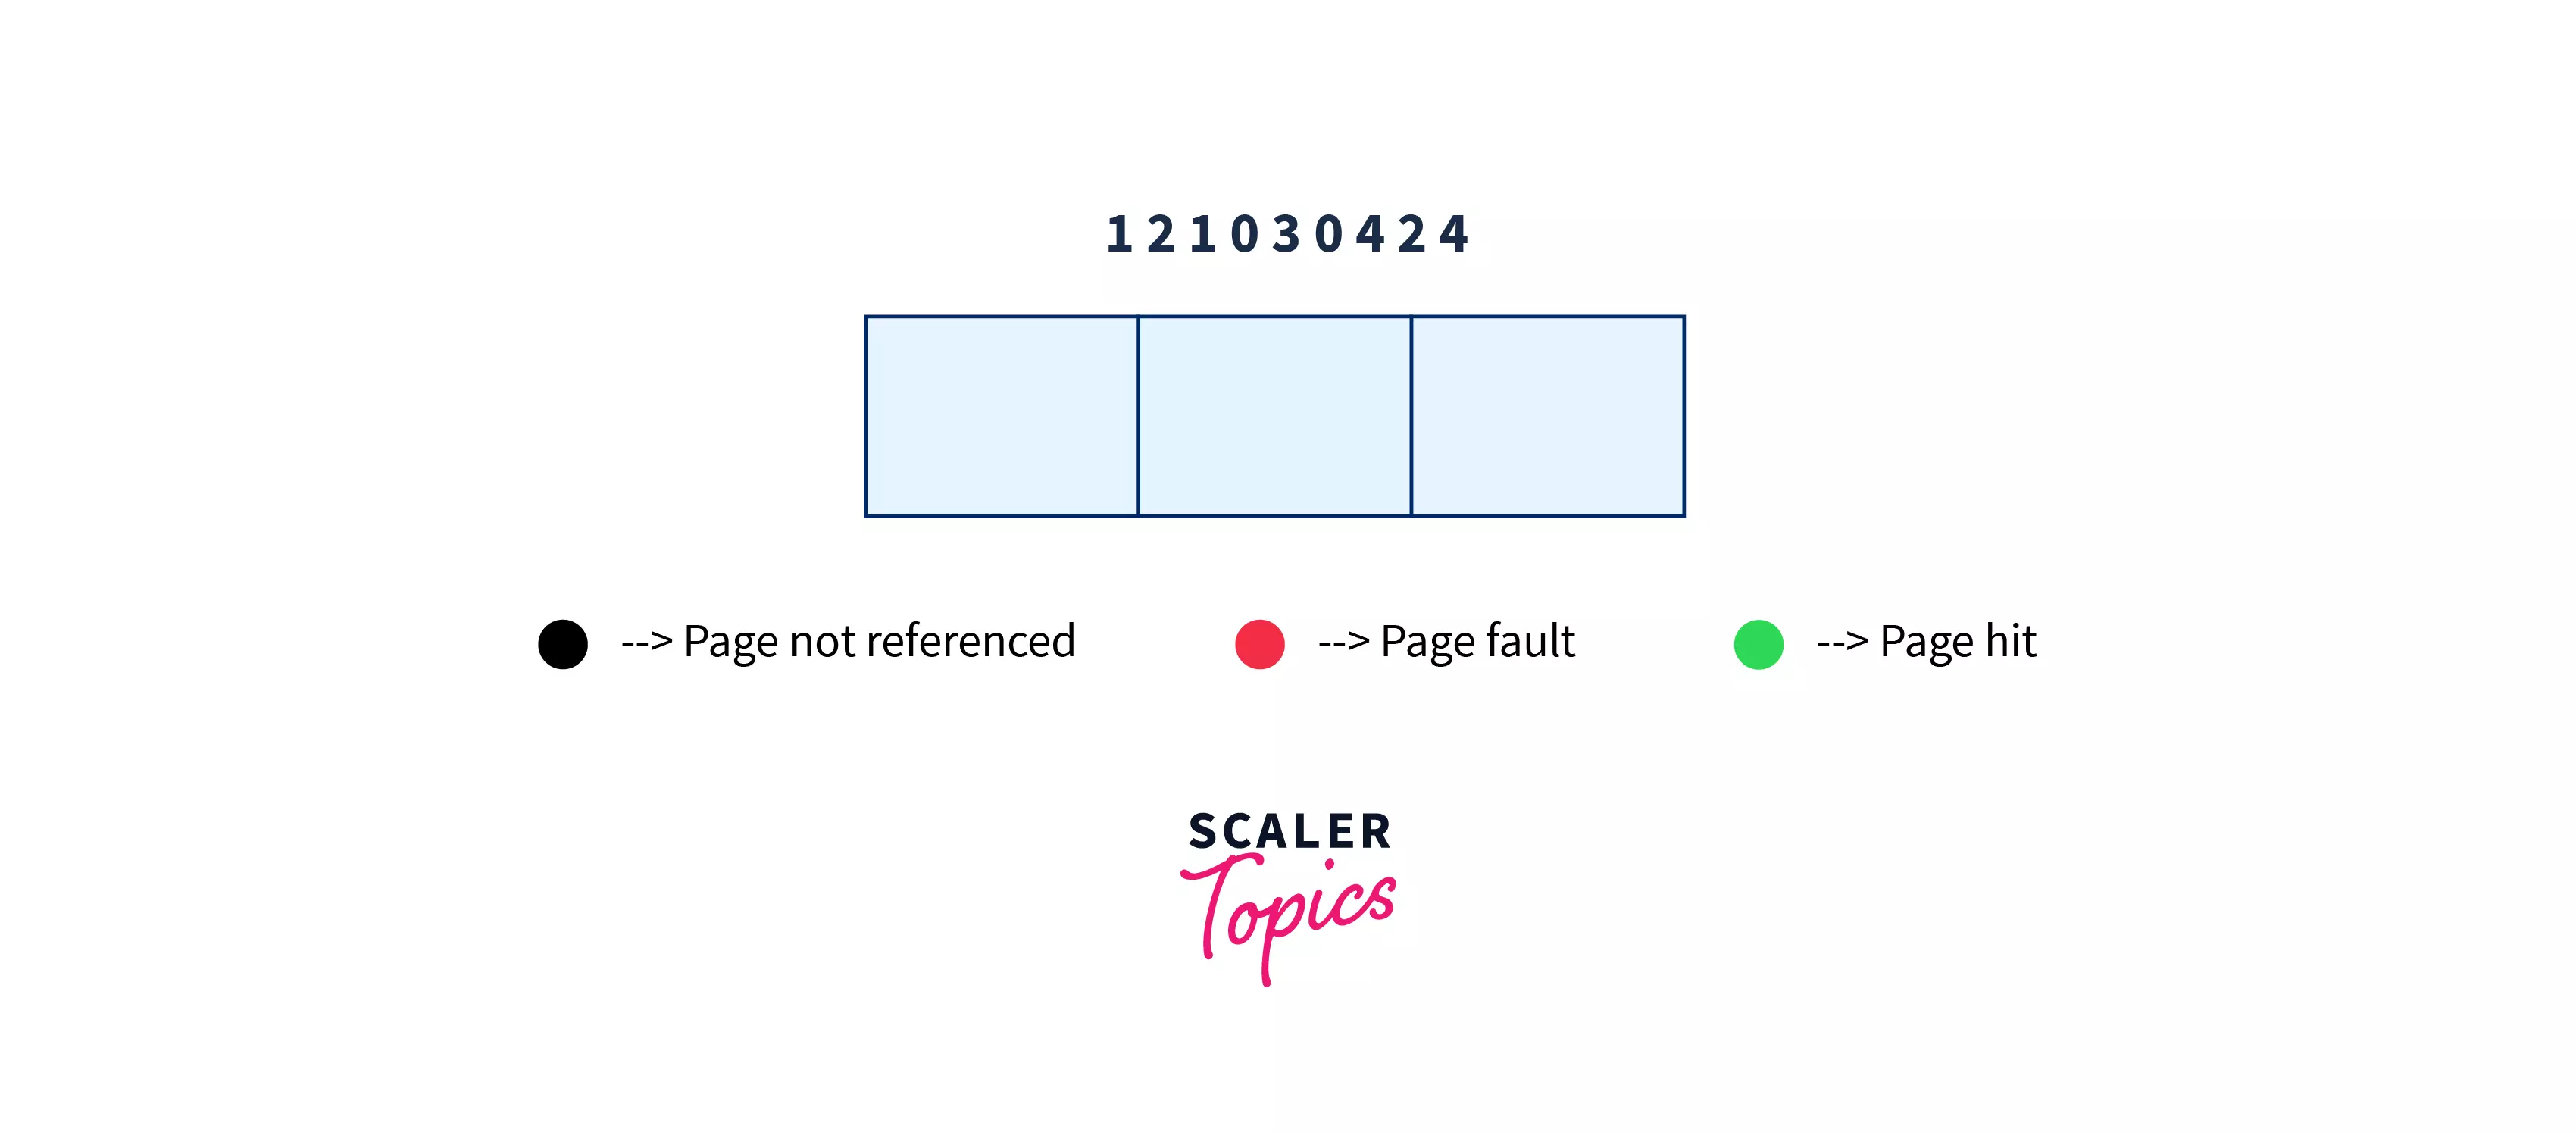
Initially, since all slots are empty, pages 1, 2 will be allocated to the empty memory slots and we will get two page faults (because neither page 1 nor page 2 was present in the memory).
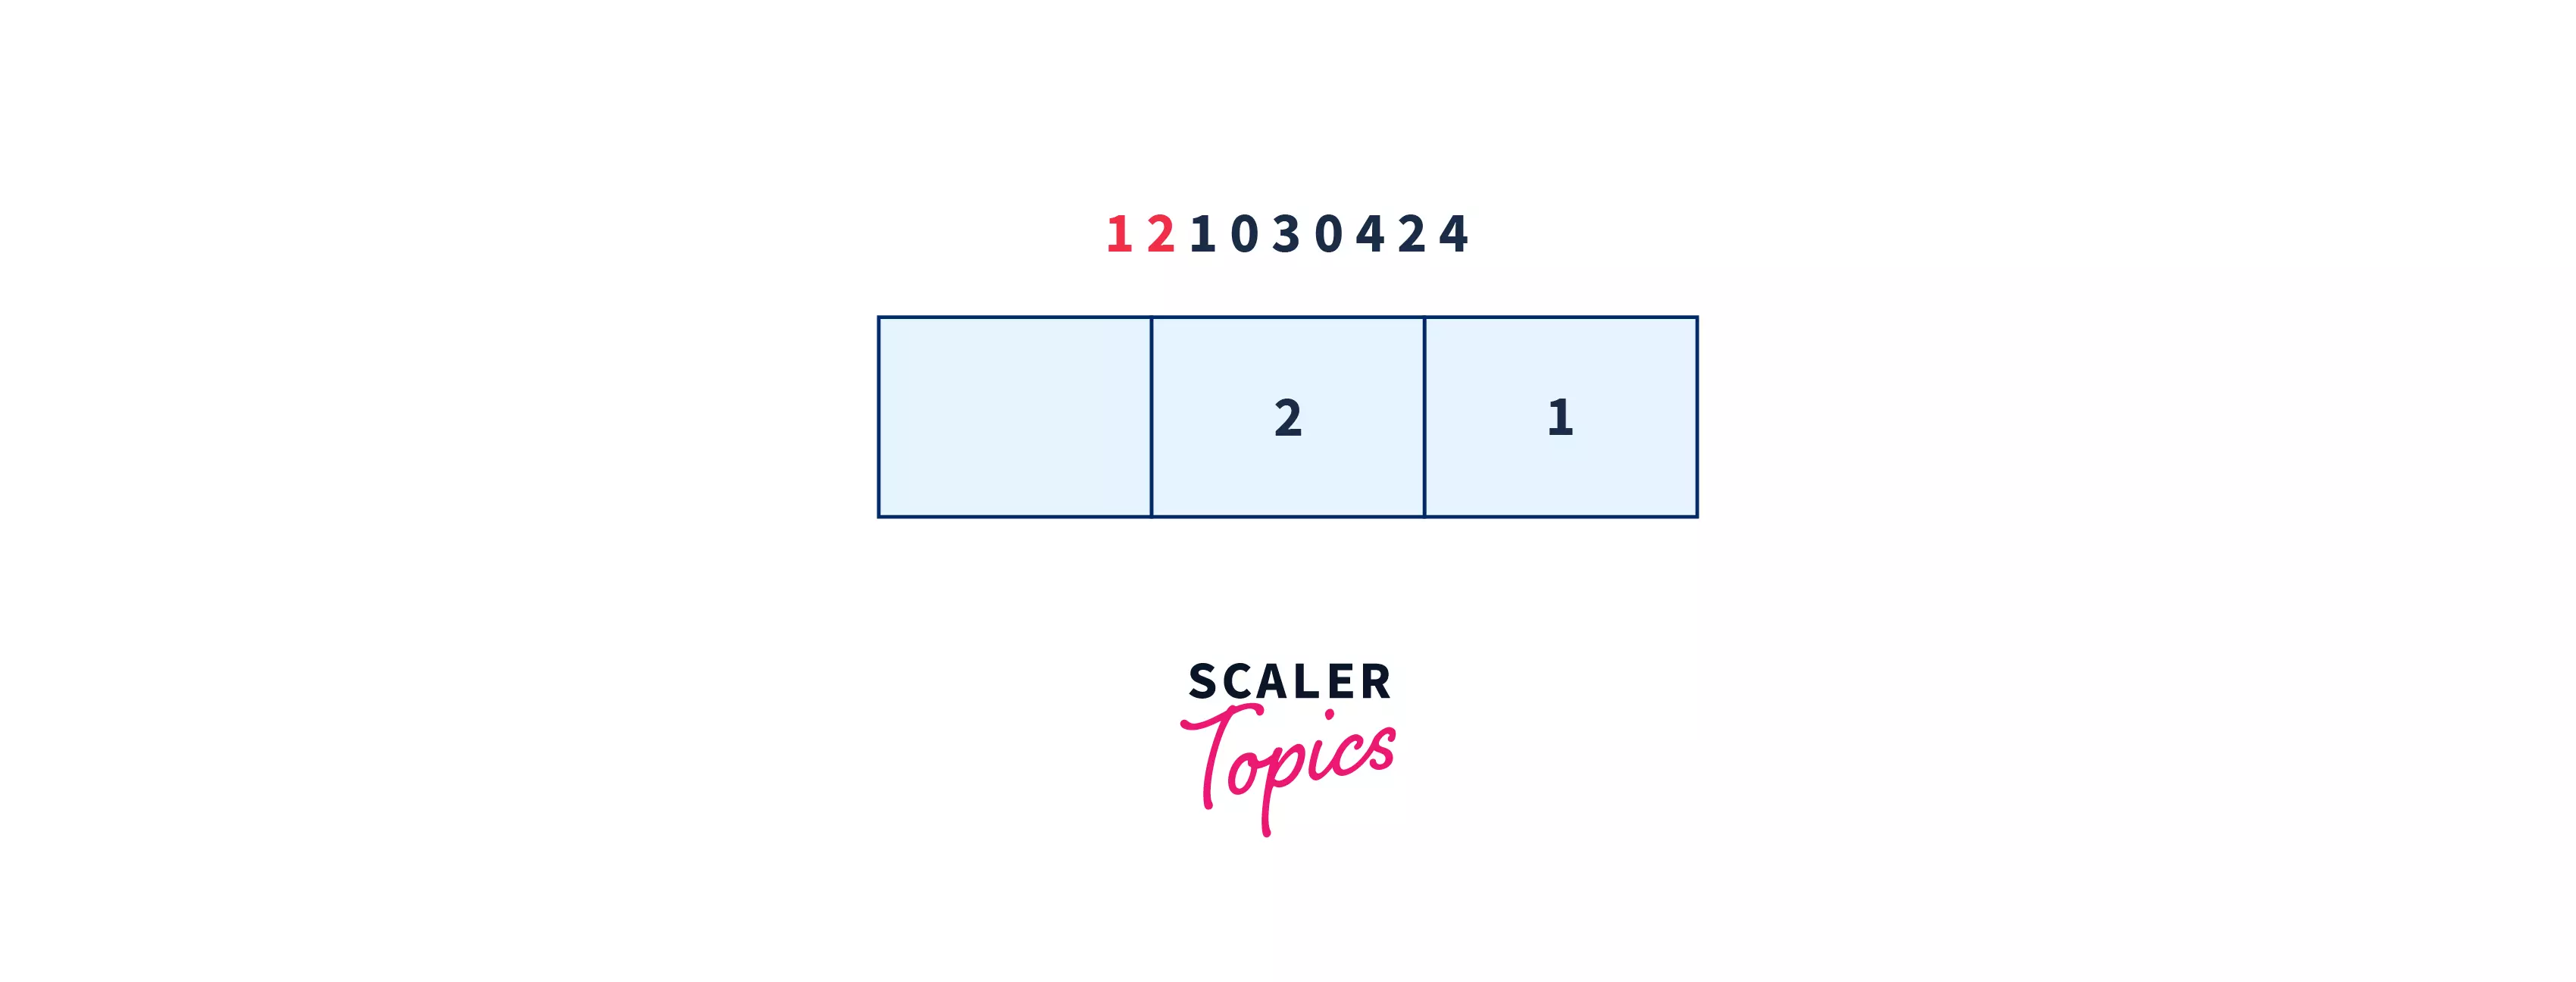
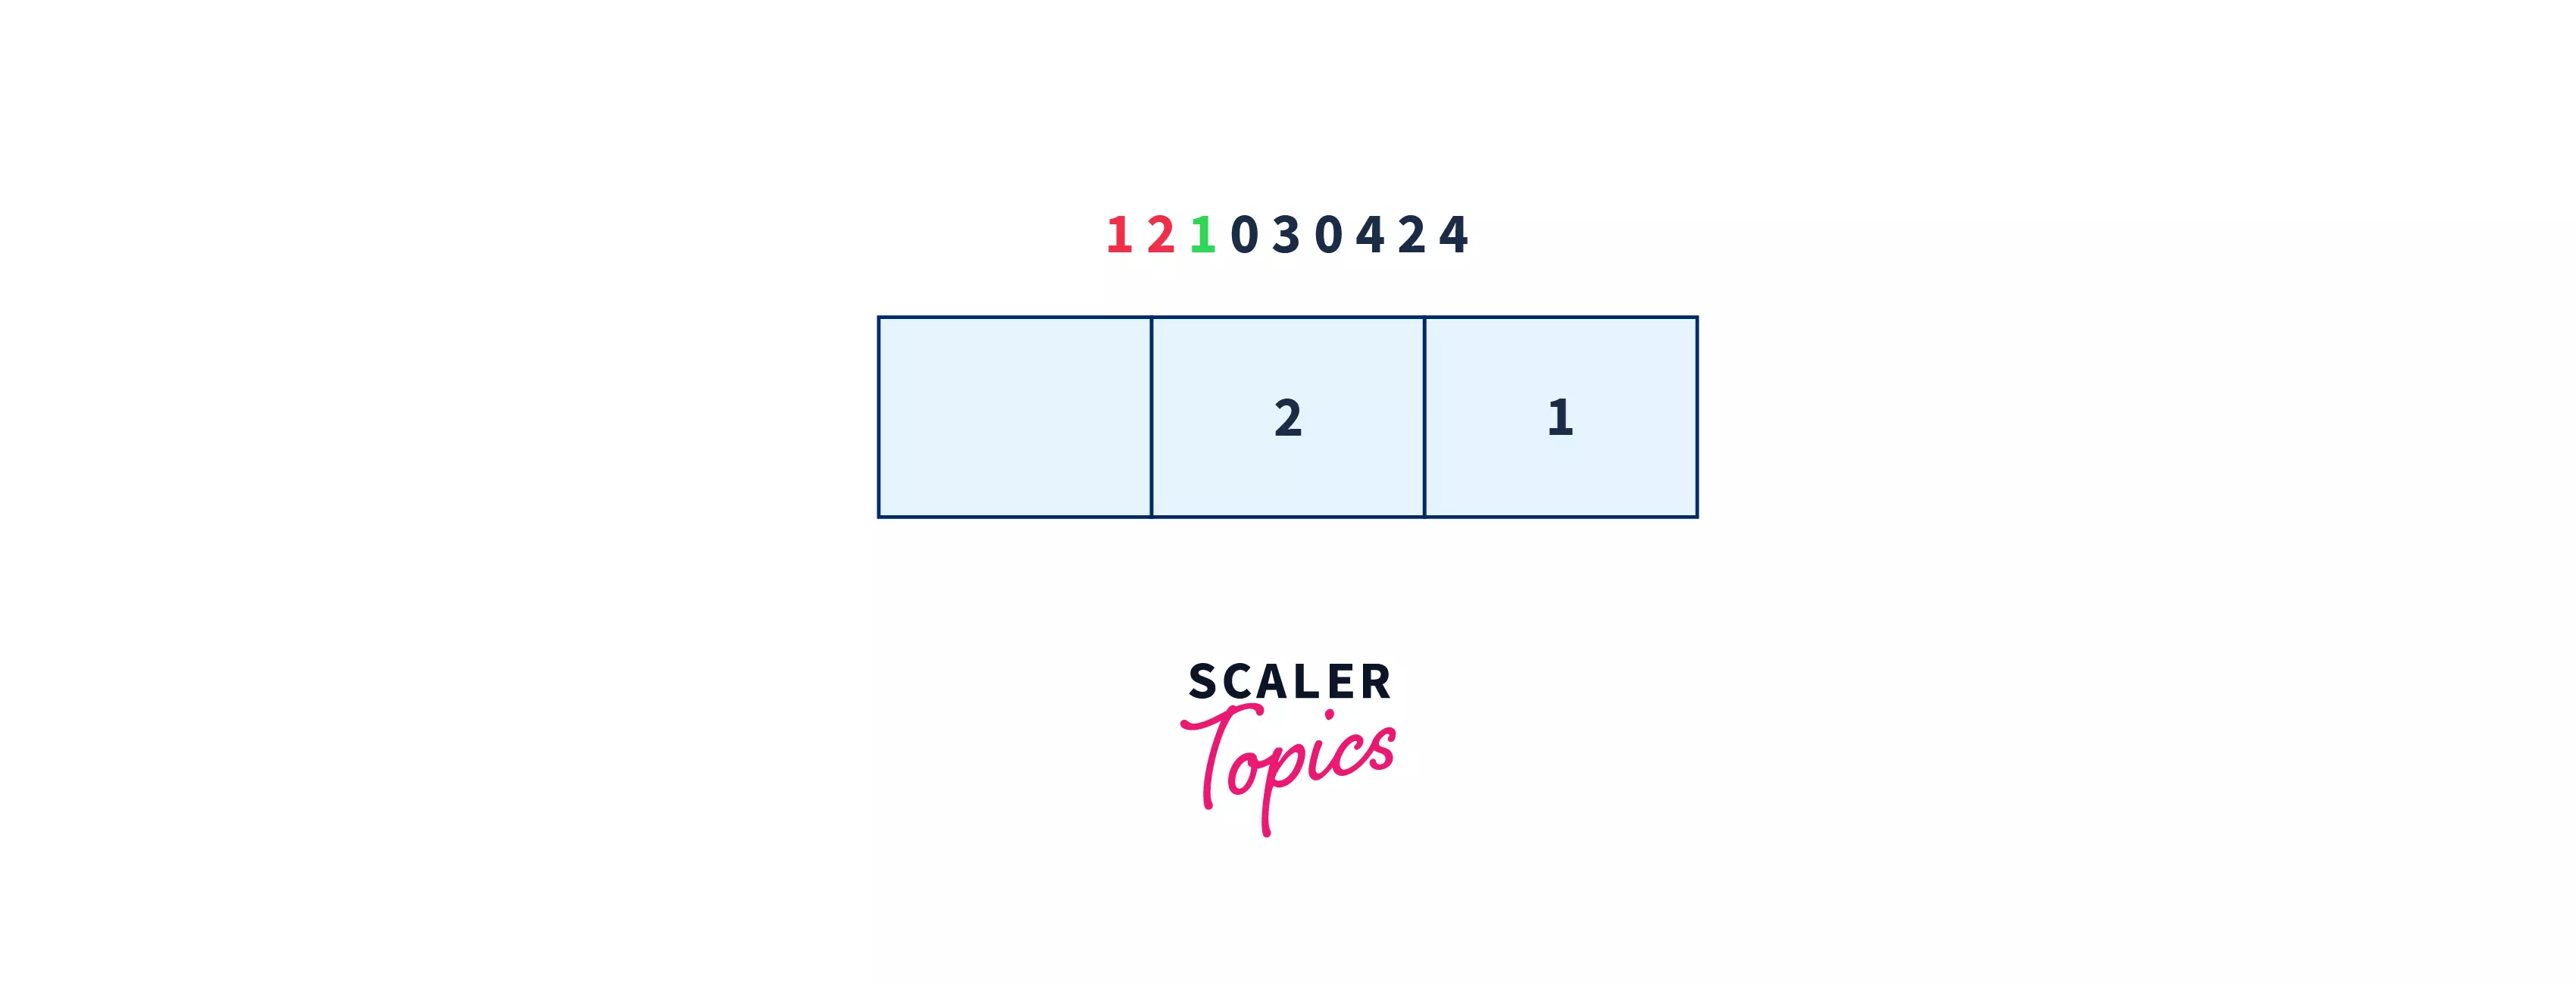
Now, page 1 is referenced again. Because it is already present in the memory, we get a page hit, and we do not need to allocate new memory to it. Also, we will not get a page fault.
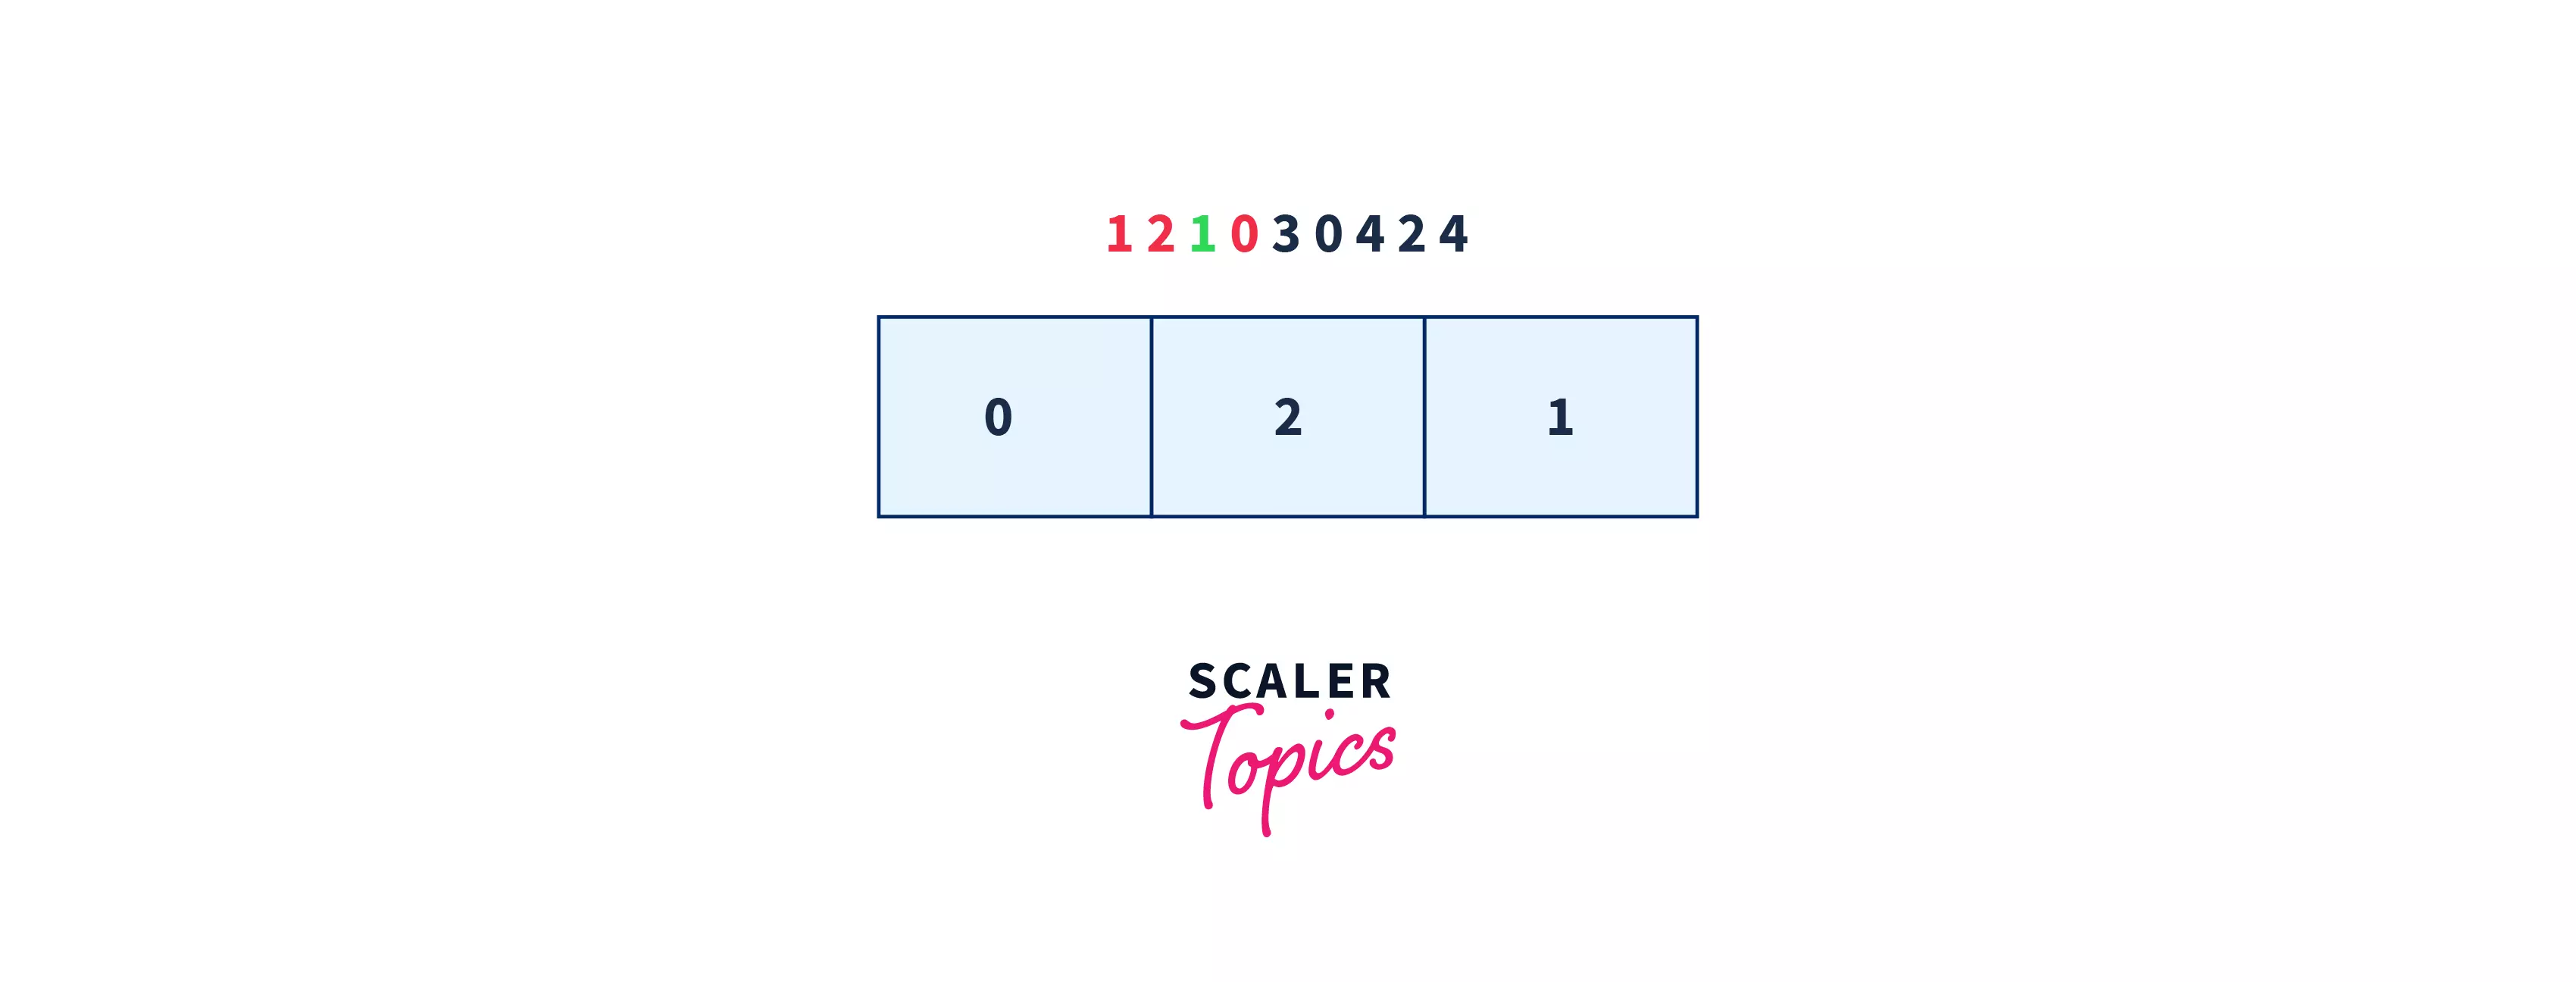
Next, page 0 is referenced. The page 0 will be allocated to the third empty slot in the memory, and we will get a page fault.
Now, page 3 is referenced and there is no empty slot in the memory. So, the LRU page replacement algorithm will come into the picture and the least recent page, i.e. page 2 will be replaced by the newly referenced page, i.e., page 3.
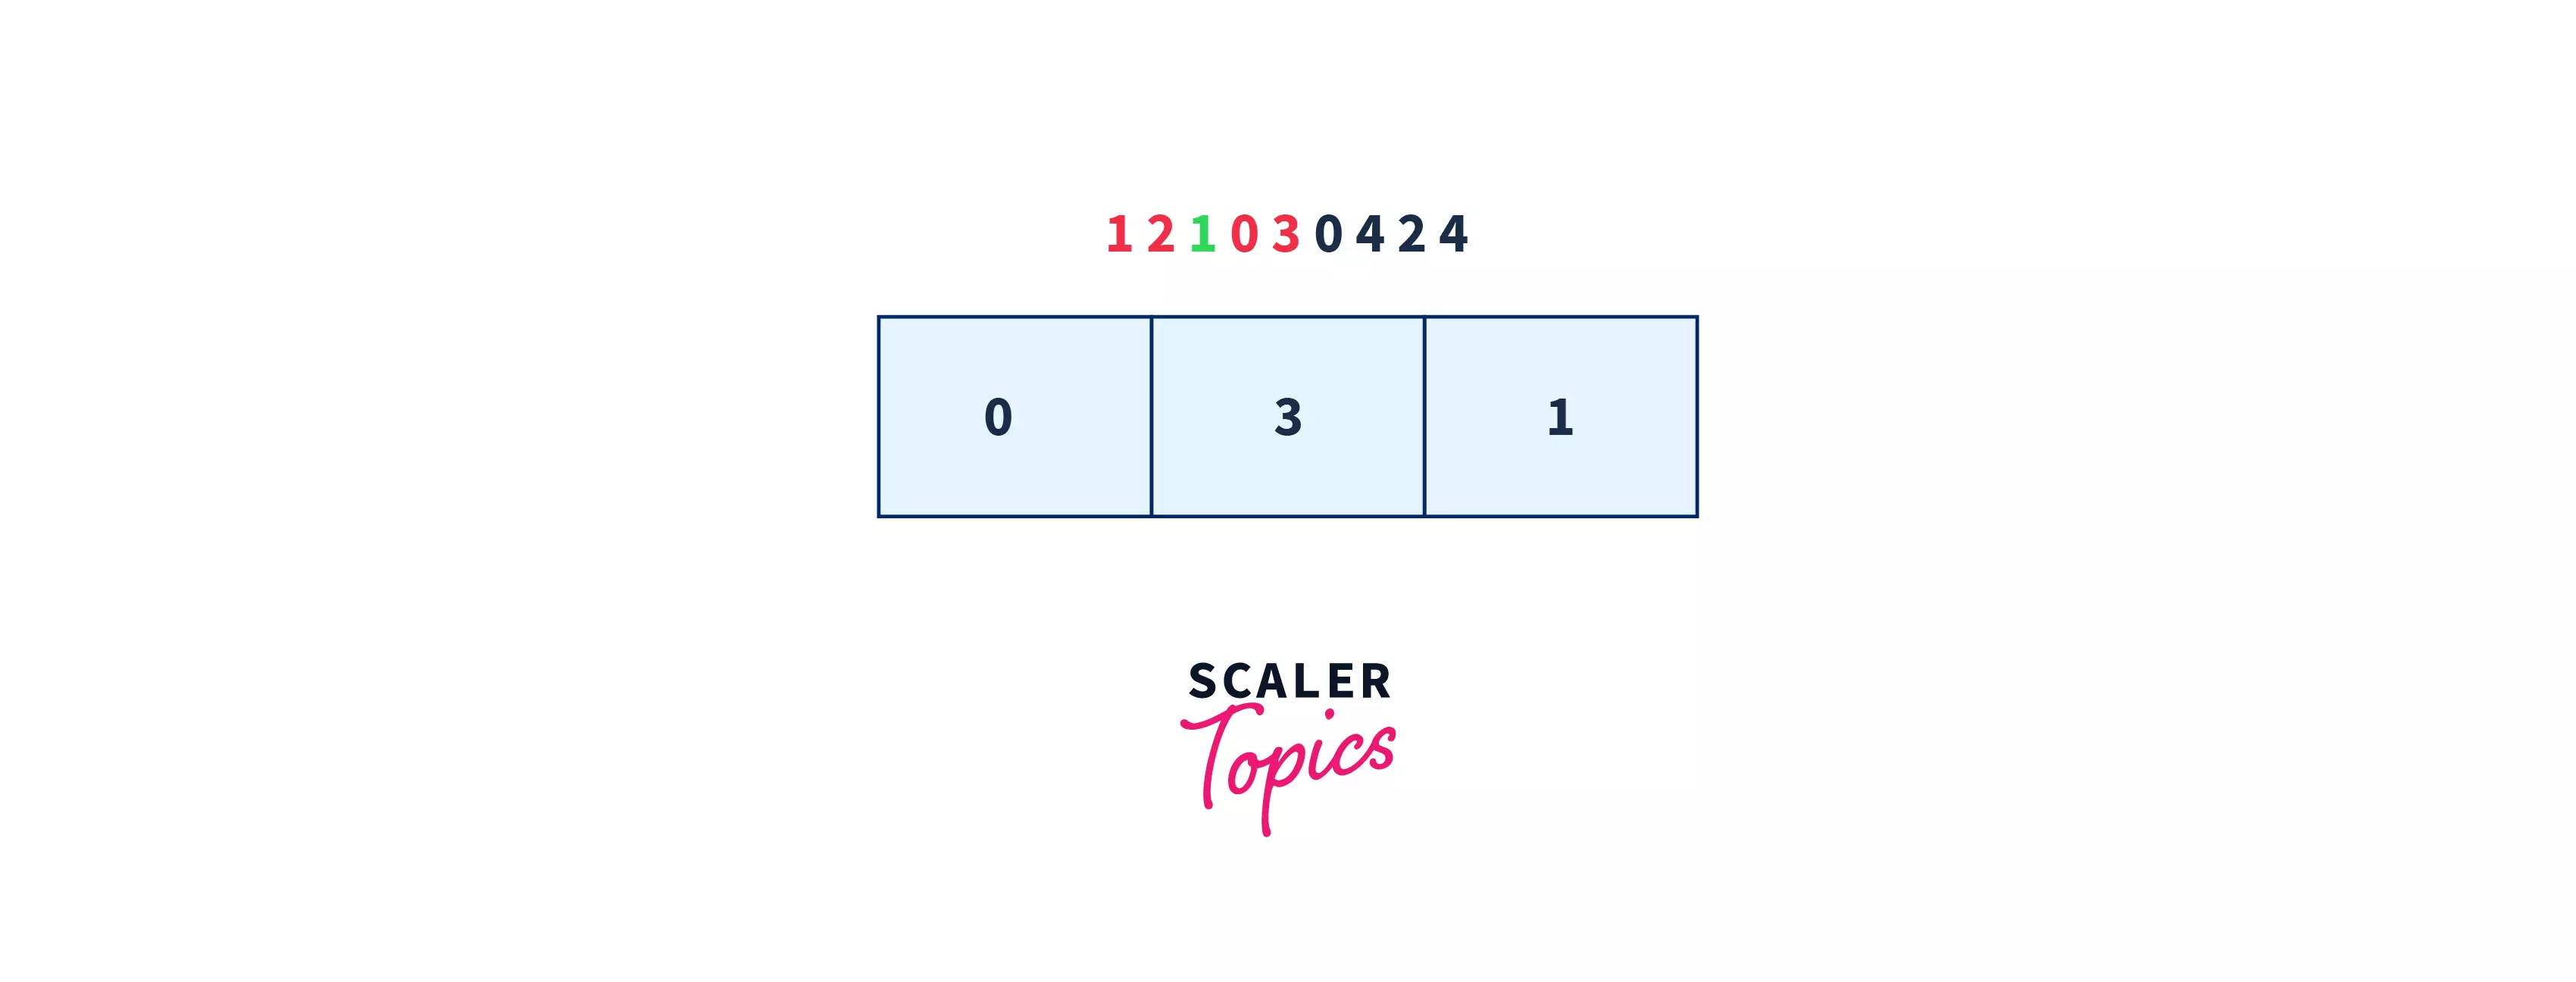
Next, page 0 is referenced and it is already present in the memory, so we get a page hit.
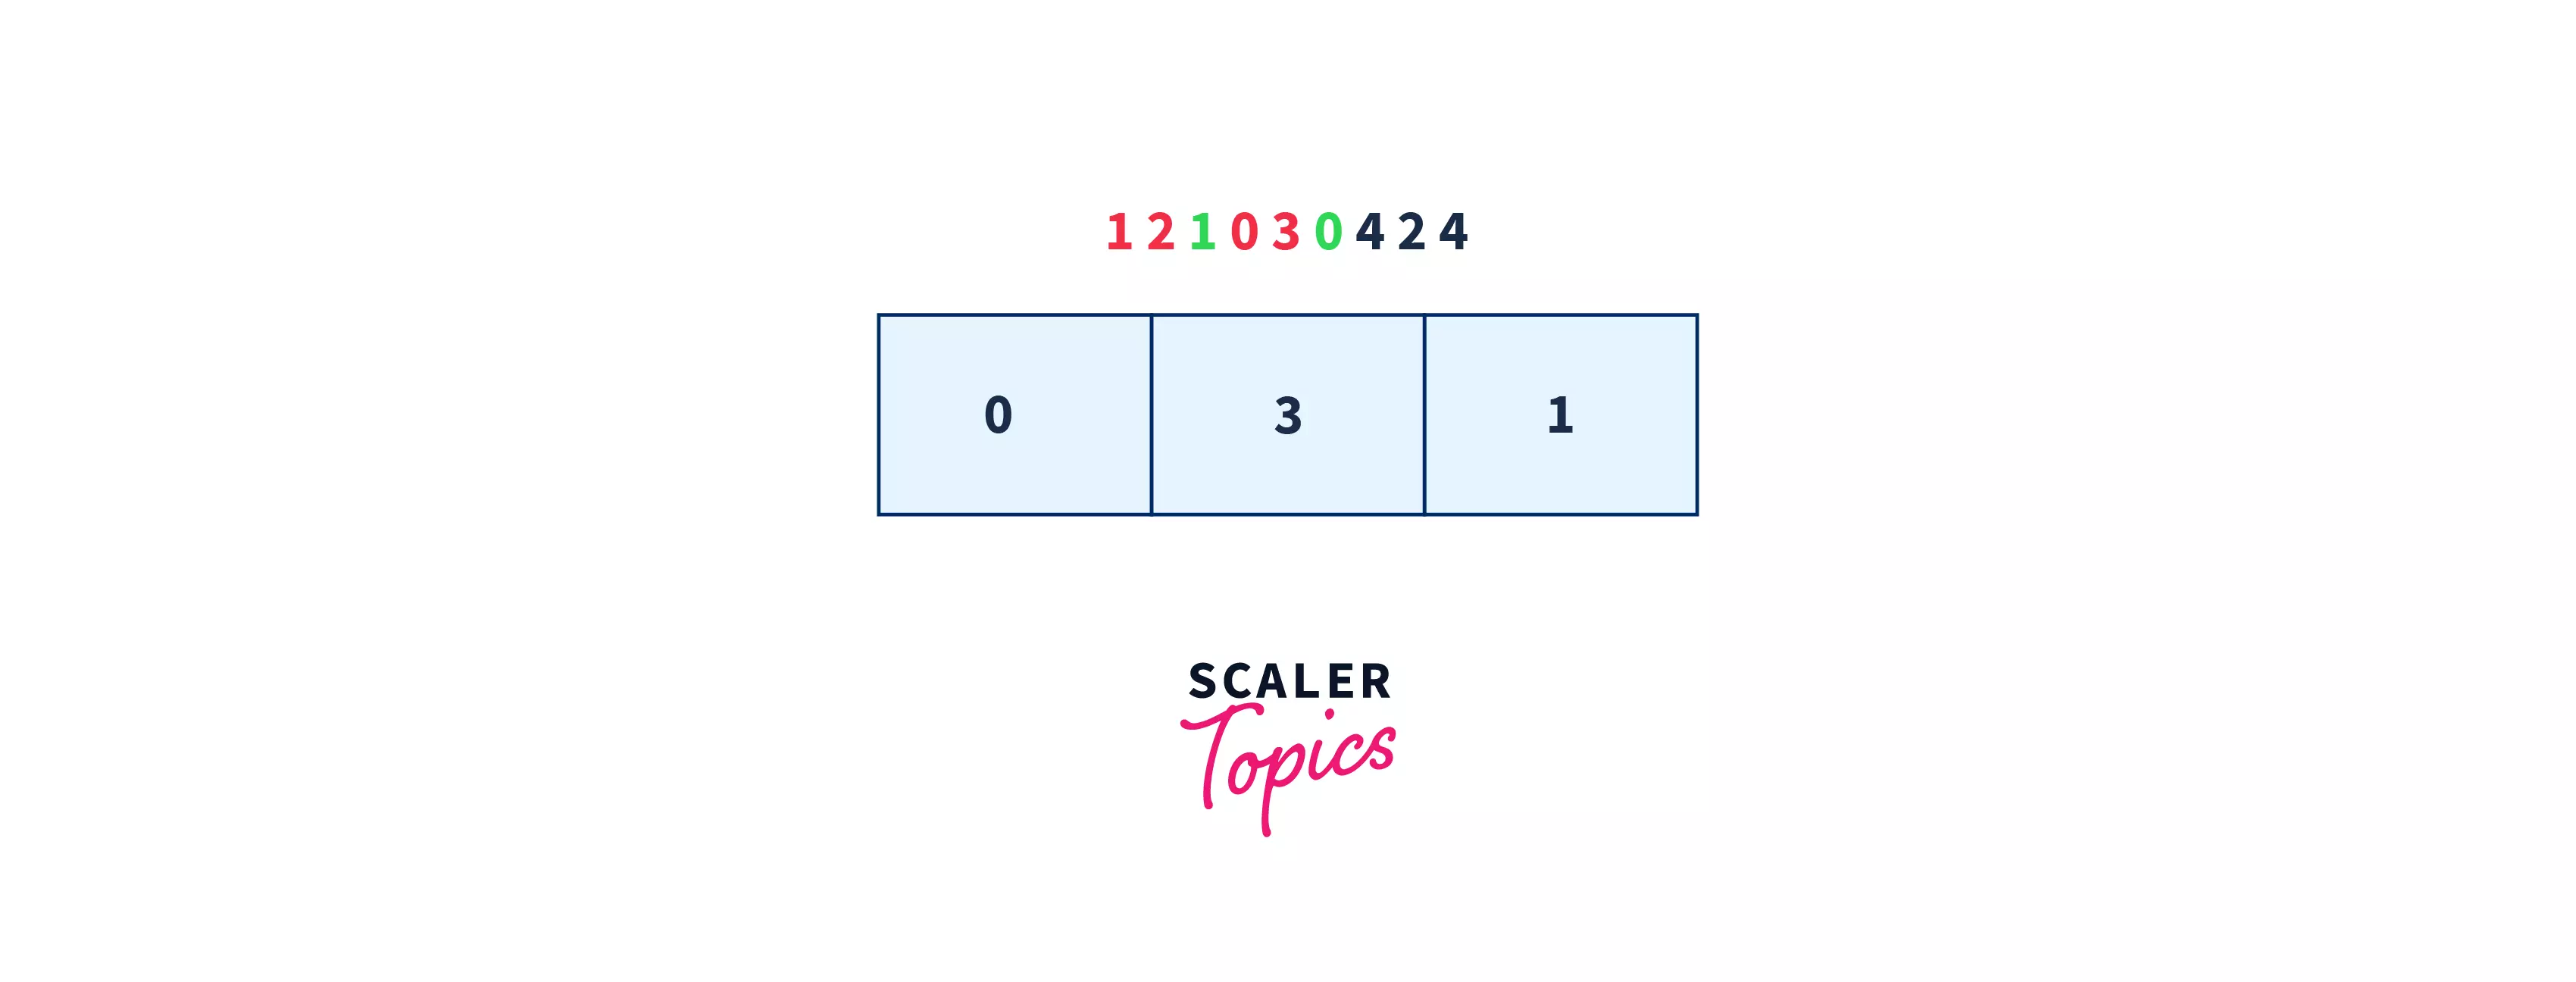
Next, page 4 is referenced. As it is not present in the memory, the LRU algorithm will be used. Since page 1 is the least recently used page, it will be replaced by page 4.
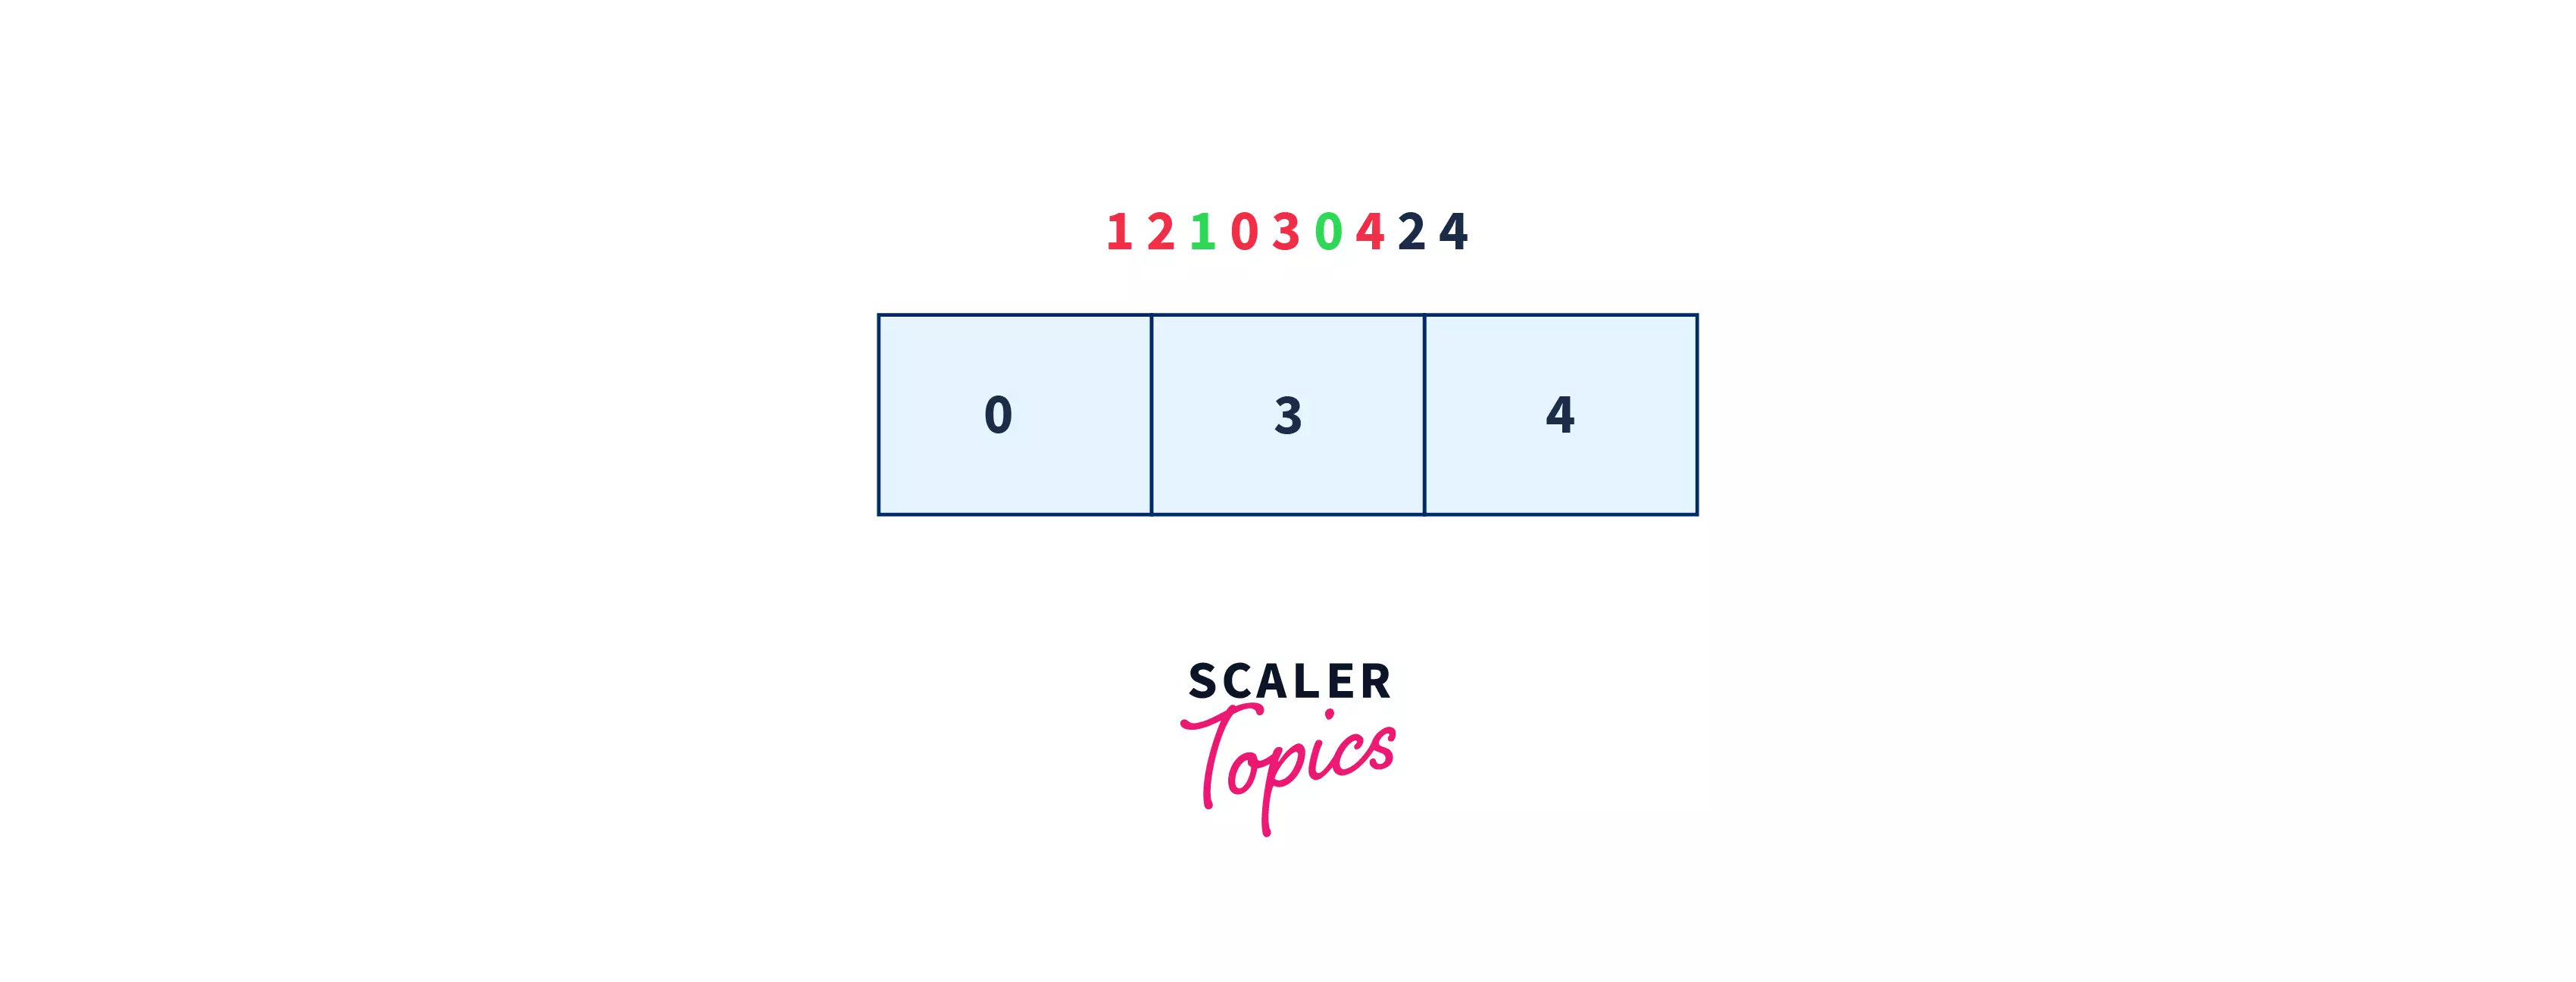
Next, page 2 is referenced. Since page 2 is not in the memory, the least recently used page, i.e. page 3 will be replaced by page 2.
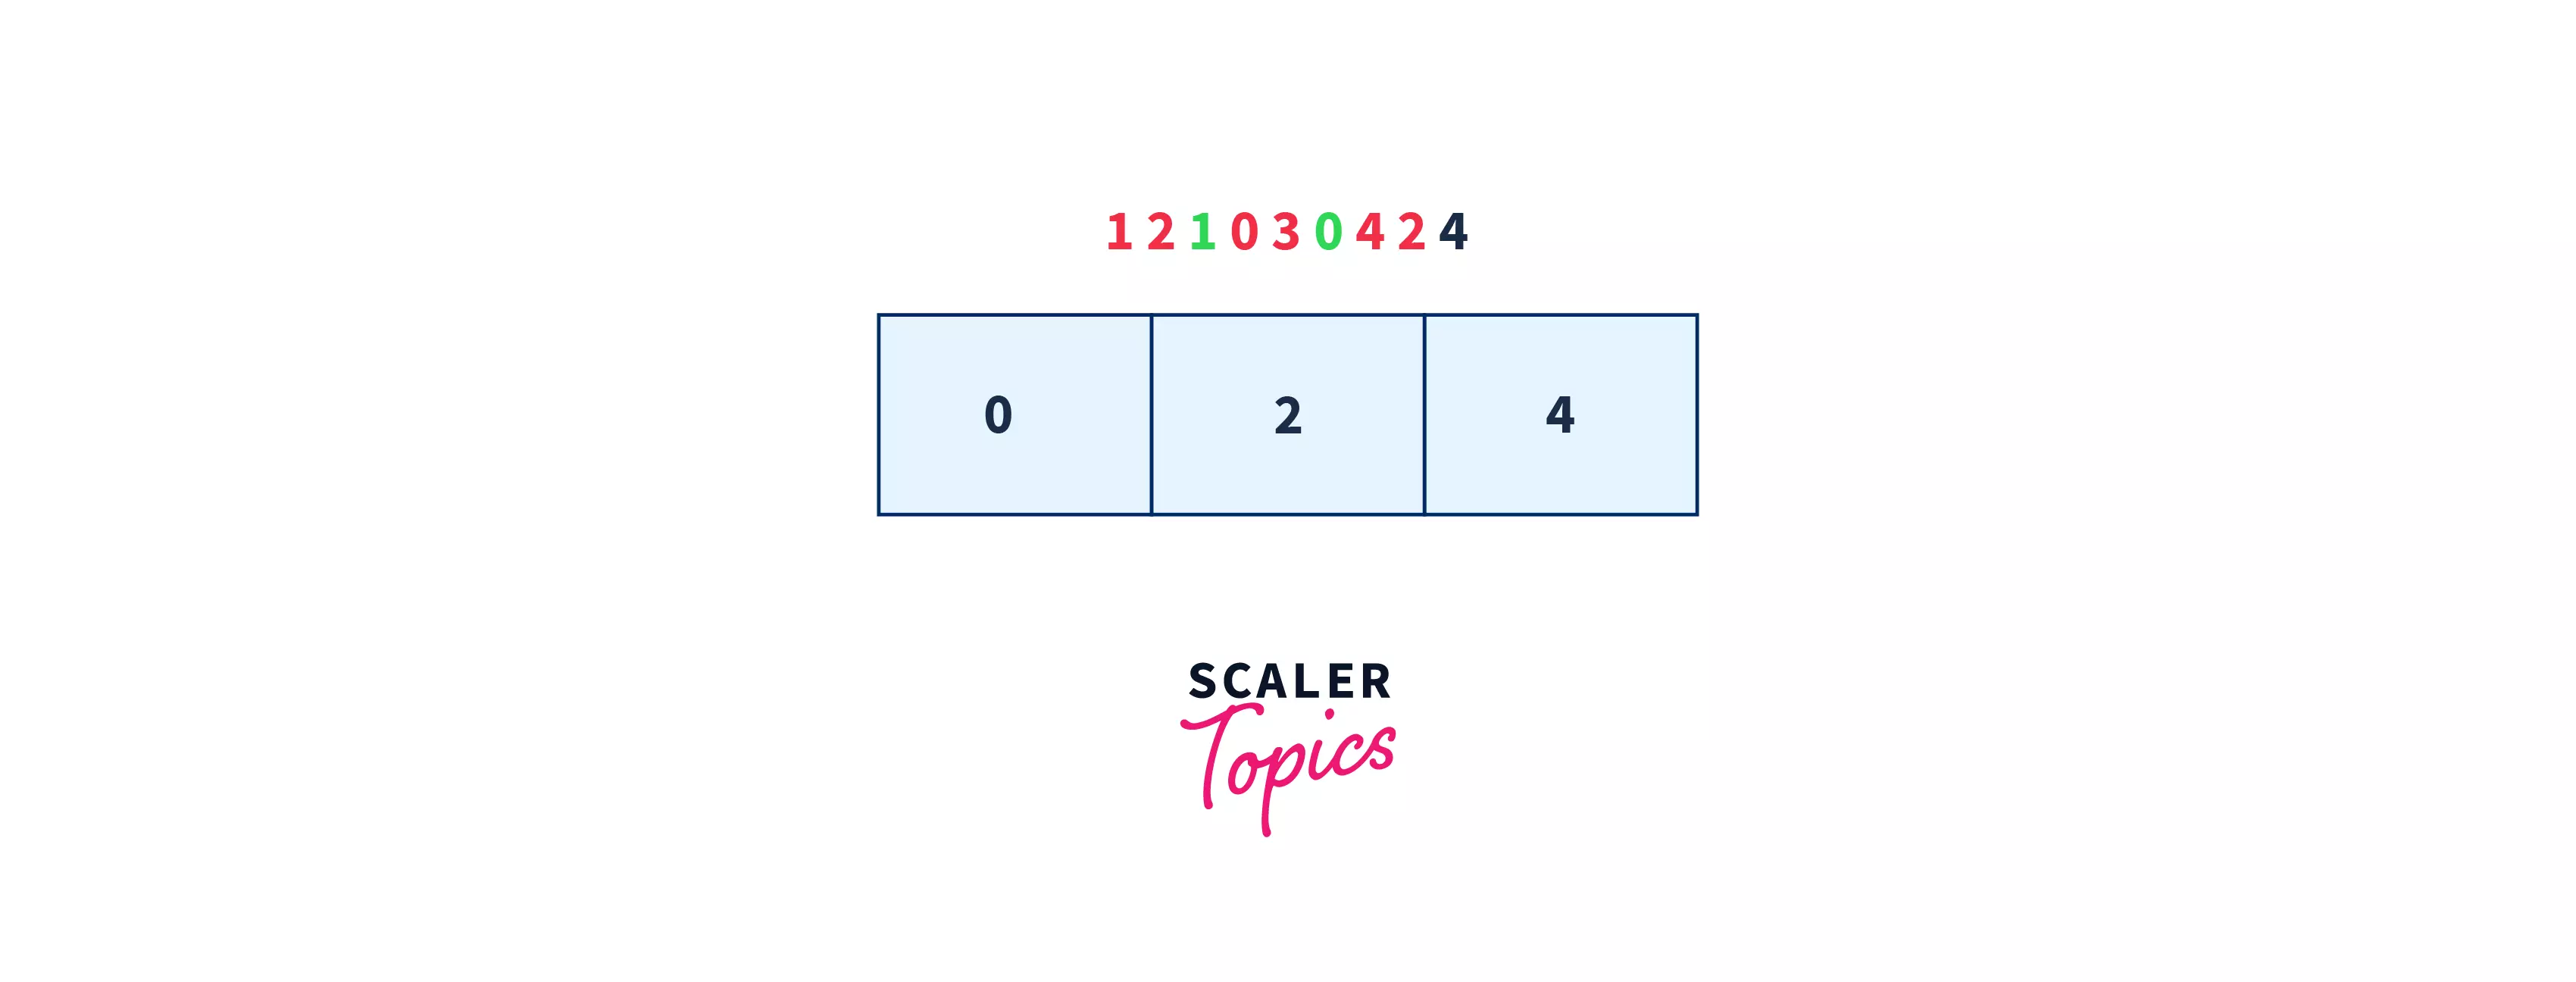
Finally, page 4 is referenced. Because page 4 is already present in the memory, we will get a page hit.
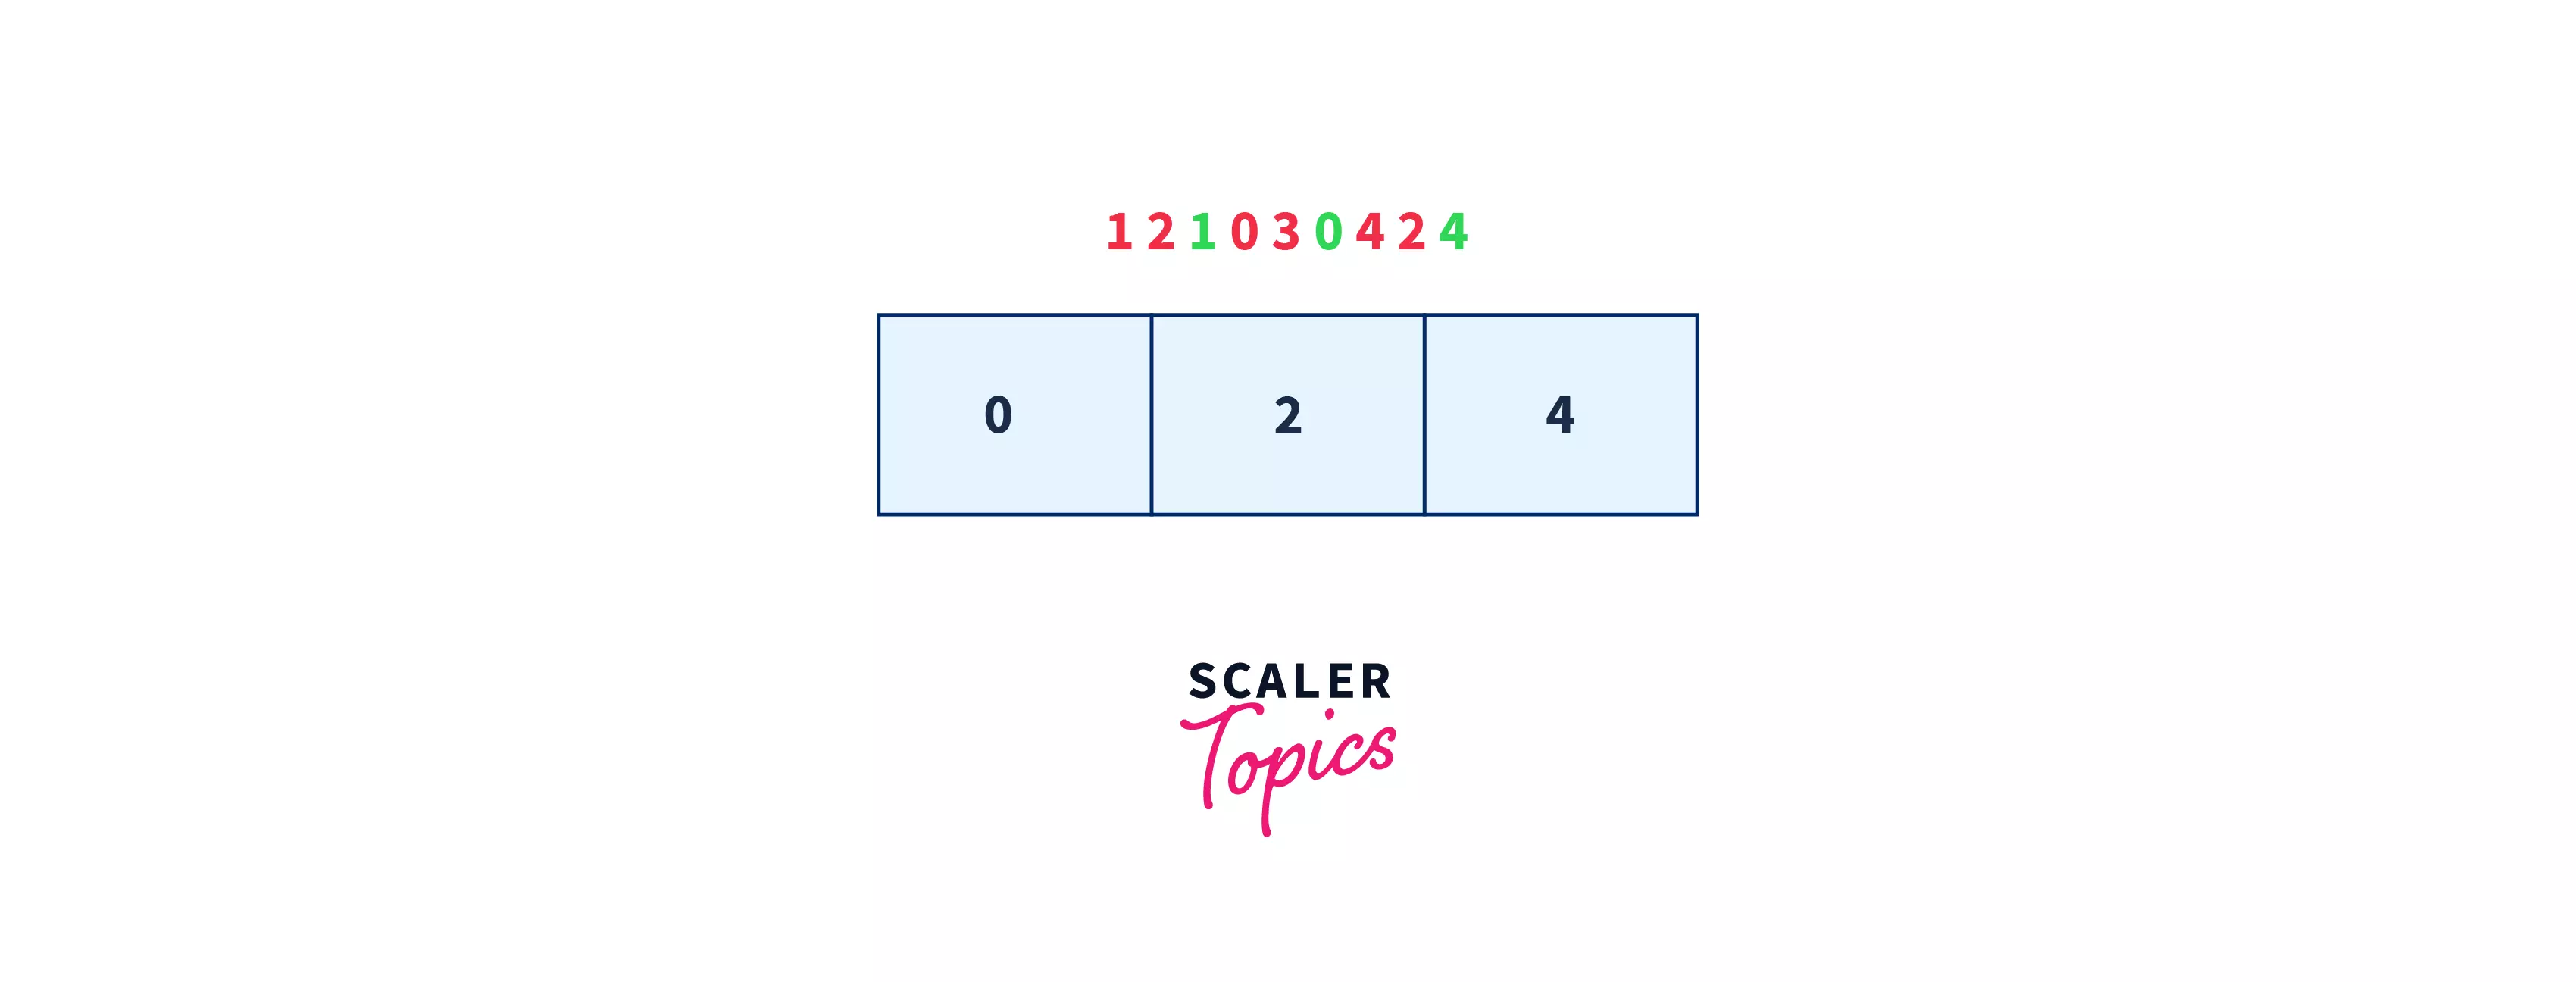
In the above example, we can conclude that we had 3-page hits and 6-page faults.
Pseudocode of LRU Algorithm in OS
Let us say that s is the main memory's capacity to hold pages and pages is the list containing all pages currently present in the main memory.
- Iterate through the referenced pages.
- If the current page is already present in pages:
- Remove the current page from pages.
- Append the current page to the end of pages.
- Increment page hits.
- Else:
- Increment page faults.
- If pages contains fewer pages than its capacity s:
- Append current page into pages.
- Else:
- Remove the first page from pages.
- Append the current page at the end of pages.
- If the current page is already present in pages:
- Return the number of page hits and page faults.
Implementation of LRU Algorithm in OS
Using Python Programming Language
Let us now understand the implementation of the LRU page replacement algorithm by taking an example.
Output:
Code Explanation: In the above example, we assumed the main memory's page holding capacity to be 3 pages. We created a list named pages to store the pages that are currently present in the memory. The variables faults and hits were made to count the number of page faults and page hits, respectively.
A for loop was used to iterate through the reference string (the reference string stores all the referenced pages). Firstly, we checked if the referenced page ref_page was already present in the pages list or not. If ref_page was present in the list, we removed ref_page from pages and appended the same ref_page to the end of the pages list. We did so in order to keep the most recently used pages at the end of the list and the least recently used pages at the start. Then, we incremented the value of hits by 1.
If ref_page was not in pages, we incremented the value of faults by 1. Then, we checked if the pages list had empty space or not. If the pages list had any empty space (i.e. length of pages list was less than the memory capacity), we appended the ref_page at the end of the list. Otherwise, we removed the first element of the pages list (the least recently used page), and then appended the ref_page at the end of the pages list.
Finally, we printed the number of hits and faults that occurred.
Advantages and Disadvantages of LRU
| Advantage | Explanation | Disadvantage | Explanation |
|---|---|---|---|
| Good performance | LRU closely approximates the optimal algorithm in practice, producing fewer page faults than simpler methods like FIFO | Implementation overhead | Requires tracking every page access hardware support or software counters are needed |
| No Belady's Anomaly | LRU never suffers from the counter-intuitive increase in faults when frames increase—a proven stack algorithm property | High hardware cost | Perfect LRU needs either a timestamp per page (expensive) or a stack maintained on every reference |
| Exploits temporal locality | Keeps recently-used pages, which are most likely to be used again, based on the principle of locality | Not optimal | LRU can still make suboptimal decisions when access patterns don't follow temporal locality |
| Widely applicable | Used in CPU caches, database buffer pools, web caches, and file systems not just OS page replacement | Scan vulnerability | Sequential scans (accessing N new pages once) can flush the entire cache of useful data |
| Adaptable | Adapts automatically to changing access patterns without configuration | Concurrent overhead | In multi-threaded systems, maintaining LRU order requires careful synchronization |
LRU Approximations (For Production Systems)
Since perfect LRU is expensive, operating systems use LRU approximations:
- Reference Bits: Each page has a hardware-managed reference bit. The OS periodically checks which pages have been used since the last check.
- Second-Chance (Clock) Algorithm: Pages are kept in a circular queue. When a page is considered for replacement, if its reference bit is 1, it's given a "second chance" and the bit is cleared. The pointer moves to the next page. Source: Silberschatz, Galvin & Gagne, Operating System Concepts, 10th Edition
- Aging Algorithm: An 8-bit counter per page records usage history over recent time intervals. Pages with lower counts are replaced first.
How Scaler Transformed Careers in Different Fields
Scaler learners achieved 2.5x salary growth with average post-Scaler CTC reaching ₹23L.
 Google
 Amazon
 Microsoft
 Flipkart
 Adobe1200+ more
FAQs
What is the LRU page replacement algorithm?
The LRU (Least Recently Used) page replacement algorithm evicts the page that has not been accessed for the longest time when memory is full and a new page needs to be loaded. It is based on the principle of temporal locality recently accessed pages are likely to be accessed again soon. LRU is implemented in most CPU caches and database buffer pools. Source: Silberschatz, Galvin & Gagne, Operating System Concepts, 10th Edition
What is the difference between LRU and FIFO page replacement?
FIFO (First-In-First-Out) replaces the oldest page in memory the one that was loaded first. LRU (Least Recently Used) replaces the page that was used furthest in the past. FIFO is simple to implement (just a queue) but suffers from Belady's anomaly; LRU performs better in most cases but requires hardware or software support to track access order. Source: Silberschatz, Galvin & Gagne, Operating System Concepts, 10th Edition
Does LRU suffer from Belady's anomaly?
No. LRU does not suffer from Belady's anomaly it is a stack algorithm. When you increase the number of frames, the set of pages in memory with N frames is always a subset of the pages in memory with N+1 frames. FIFO, however, does suffer from Belady's anomaly: increasing frames can increase page faults.
Turn Learning into Career Growth
How do you calculate page faults in LRU?
Count every reference where the page is not already in a frame. In a trace table, a page fault occurs when the referenced page does not appear in any of the current frames. The formula is: Hit Ratio = Hits / Total References, and Fault Ratio = Faults / Total References.
What is the LRU approximation algorithm?
LRU approximation algorithms use hardware-supported reference bits to approximate LRU without full timestamp tracking. The most common is the Second-Chance (Clock) algorithm, which processes pages in a circular queue and gives a page a "second chance" if its reference bit is set. It requires only one reference bit per page and one pointer, making it practical for real operating systems. Source: Silberschatz, Galvin & Gagne, Operating System Concepts, 10th Edition
What is the time complexity of LRU?
With a doubly-linked list + hash map, both the get and put operations run in O(1) time the hash map finds the page, and the linked list moves it to the front or removes the tail in constant time. With a simple counter-based approach, operations are O(n) for finding the minimum counter. Source: Algocademy — Understanding Cache Replacement Policies
Why is LRU used in caches?
LRU is used in caches (CPU L1/L2/L3, disk caches, database buffer pools) because it provides a good balance between implementation complexity and hit rate. For workloads with temporal locality where recently accessed items are likely to be accessed again LRU reliably keeps hot data in the cache. Its O(1) implementation with linked list + hash map makes it practical for production systems. Source: Algocademy Understanding Cache Replacement Policies
Is LRU better than optimal?
In practice, LRU is the best implementable algorithm because optimal page replacement requires knowledge of future references, which is impossible in a real system. Optimal is used only as a theoretical benchmark. LRU typically produces page fault rates within a few percent of optimal for real workloads. Source: Silberschatz, Galvin & Gagne, Operating System Concepts, 10th Edition
Conclusion
The LRU page replacement algorithm is one of the most important concepts in operating system memory management. It works on a simple, intuitive principle: replace the page that hasn't been used for the longest time, because pages used recently are most likely to be used again soon. This makes LRU effective for real workloads that exhibit temporal locality.
The key takeaways for any exam or interview:
- LRU evicts the least recently used page when memory is full
- It does NOT suffer from Belady's anomaly unlike FIFO
- Perfect LRU is expensive to implement most systems use approximations like the Clock algorithm
- LRU is close to optimal in practice, typically producing near-minimum page faults
- The two formulas to remember: Hit Ratio = Hits / Total References; Page Faults = Total References − Hits
LRU appears not just in operating systems but in every caching layer of modern computing from your CPU's L3 cache to Redis to your browser's CDN cache. Understanding LRU gives you insight into how all of these systems manage limited memory efficiently.


