


Types of Errors in Machine Learning: Bias, Variance & More
Overview
One of the most popular fields of study and work in Computer Science right now, Machine Learning is the process of using data and algorithms to make computers think and behave on their own. Yes, it sounds very interesting, but it has its fair share of computational steps and solutions. Calculating errors is the way for Machine Learning Engineers to take a step back, assess what's wrong with their model, and try to change some parameters to get the least amount of error possible. In this article, we will look at a few concepts that are required for us to understand errors in Machine Learning, and then look at the various metrics by which we measure errors in Machine Learning.
Prerequisites
Before this article, you must know a bit about:
- Basic probability concepts.
- The lifecycle of a Machine Learning project.
Build an AI-First Career, Master the Complete Skillset
Choose from our industry-leading programs designed for career success
Modern Software and AI Engineering Program
Master full-stack development with AI integration


 +1000 more
Modern Data Science and ML with specialisation in AI
Advanced data science techniques with AI specialization
+1000 moreAdvanced AIML with Specialisation in Agentic AI
Deep dive into AIML with focus on Agentic systems
+1000 moreDevOps, Cloud & AI Platform Engineering
Build and manage AI-powered cloud infrastructure
+1000 moreAI Engineering Advanced Certification by IIT-Roorkee
Premier AI engineering certification from IIT-Roorkee

AI Forward Deployed Engineer Program
Full-stack engineering, production AI and client-facing consulting
+1000 moreIntroduction
As we discussed earlier in this article, calculating errors in our Machine Learning models helps us understand our model's less-impacting areas and various ways to tackle them. Amongst the uses of errors in Machine Learning, it is also used quite a lot when comparing various Machine Learning algorithms for a problem statement. With the help of errors, we can determine which model has the highest accuracy.
Error calculation is the process of isolating, observing, and diagnosing various ML predictions, thereby helping understand the highs and lows of the model. This article will unravel various methods to calculate and minimize errors.
Types of Errors in Machine Learning at a Glance
| Error type | What it means | Symptom | Can it be reduced? |
|---|---|---|---|
| Bias error | Model is too simple to capture the true pattern | High training error and high test error (underfitting) | Yes: more features, a more complex model, less regularisation |
| Variance error | Model is too sensitive to the training data | Low training error, much higher test error (overfitting) | Yes: more data, regularisation, simpler model, cross-validation |
| Irreducible error (noise) | Randomness or unmeasured factors in the data | An error floor no model can beat | No (only better data or new features can shift it) |
| Type I error (false positive) | Predicting positive when the truth is negative | A genuine payment flagged as fraud | Trade it off by moving the decision threshold |
| Type II error (false negative) | Predicting negative when the truth is positive | A fraudulent payment marked safe | Trade it off by moving the decision threshold |
The first three explain why a model is wrong. Type I and Type II describe which way a classifier is wrong.
Reducible vs Irreducible Error
A model's total prediction error splits into two parts. Reducible error is the part that a better model, better tuning or more data can lower, and it has two components: bias and variance. Irreducible error is the part no model can remove.
Bias Error (Underfitting)
Bias comes from wrong assumptions in the model, such as fitting a straight line to data that actually curves. A high-bias model misses the real pattern, so it's wrong in a consistent way.
- Symptoms: high training error and high test error.
- Fixes: use a richer model, add features, or reduce regularisation.
Variance Error (Overfitting)
Variance comes from a model being too sensitive to the particular training sample. A high-variance model learns the noise along with the pattern, so a slightly different training set would give a very different model.
Importance of Hypothesis
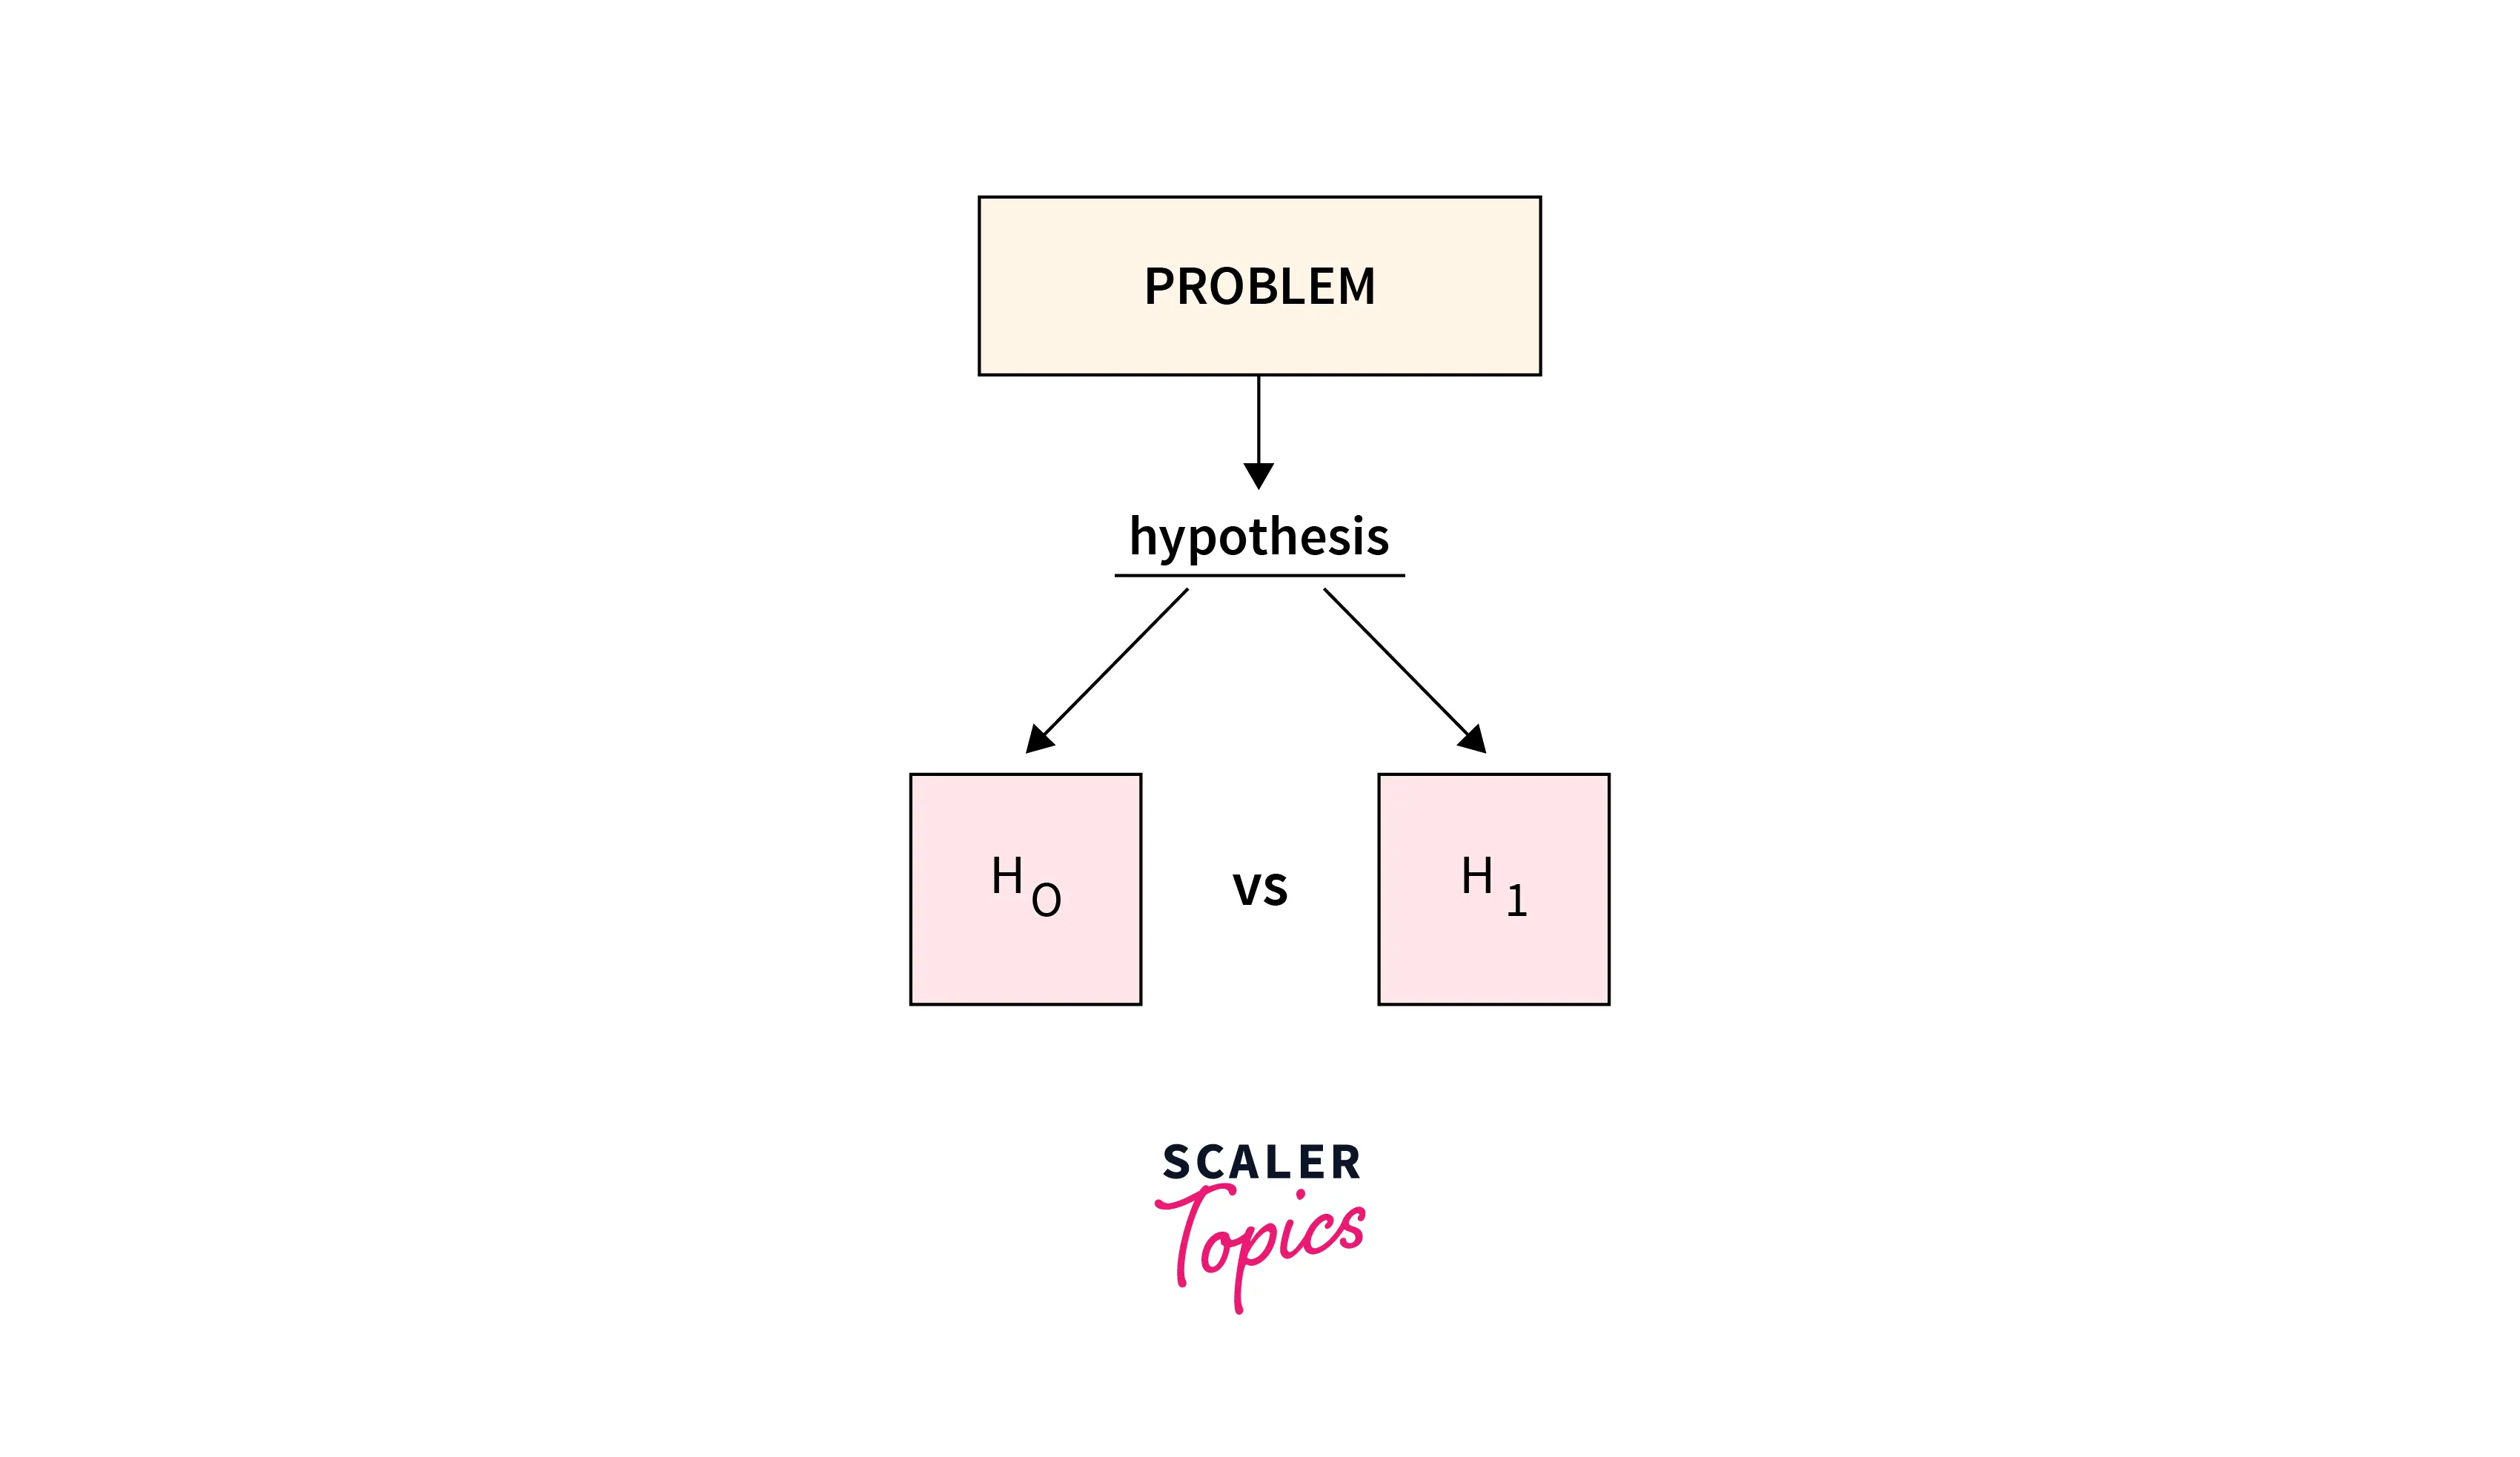
Hypothesis (Hypothesis Testing, to be precise) is an idea generated from an educated guess. We basically take a statement (should be falsifiable) and then try to prove its authenticity. If the educated assumption holds, then the hypothesis is considered true, else it's not held in contention.
Using statistical hypothesis, we calculate a critical effect; this effect determines if our observed assumption holds true or not. In practice, we generate a null hypothesis(H0), in which there is no difference between population means based on samples. Then, we use the statistical/alternate hypothesis (H1) to challenge the null hypothesis, to either accept or deny the hypothesis.
Note: The alternate/statistical hypothesis doesn't necessarily have to be the exact opposite of the null hypothesis. It's just a different observation made using an educated guess.
How Scaler Transformed Careers in Different Fields
Scaler learners achieved 2.5x salary growth with average post-Scaler CTC reaching ₹23L.
 Google
 Amazon
 Microsoft
 Flipkart
 Adobe1200+ more
Probability and P-Values
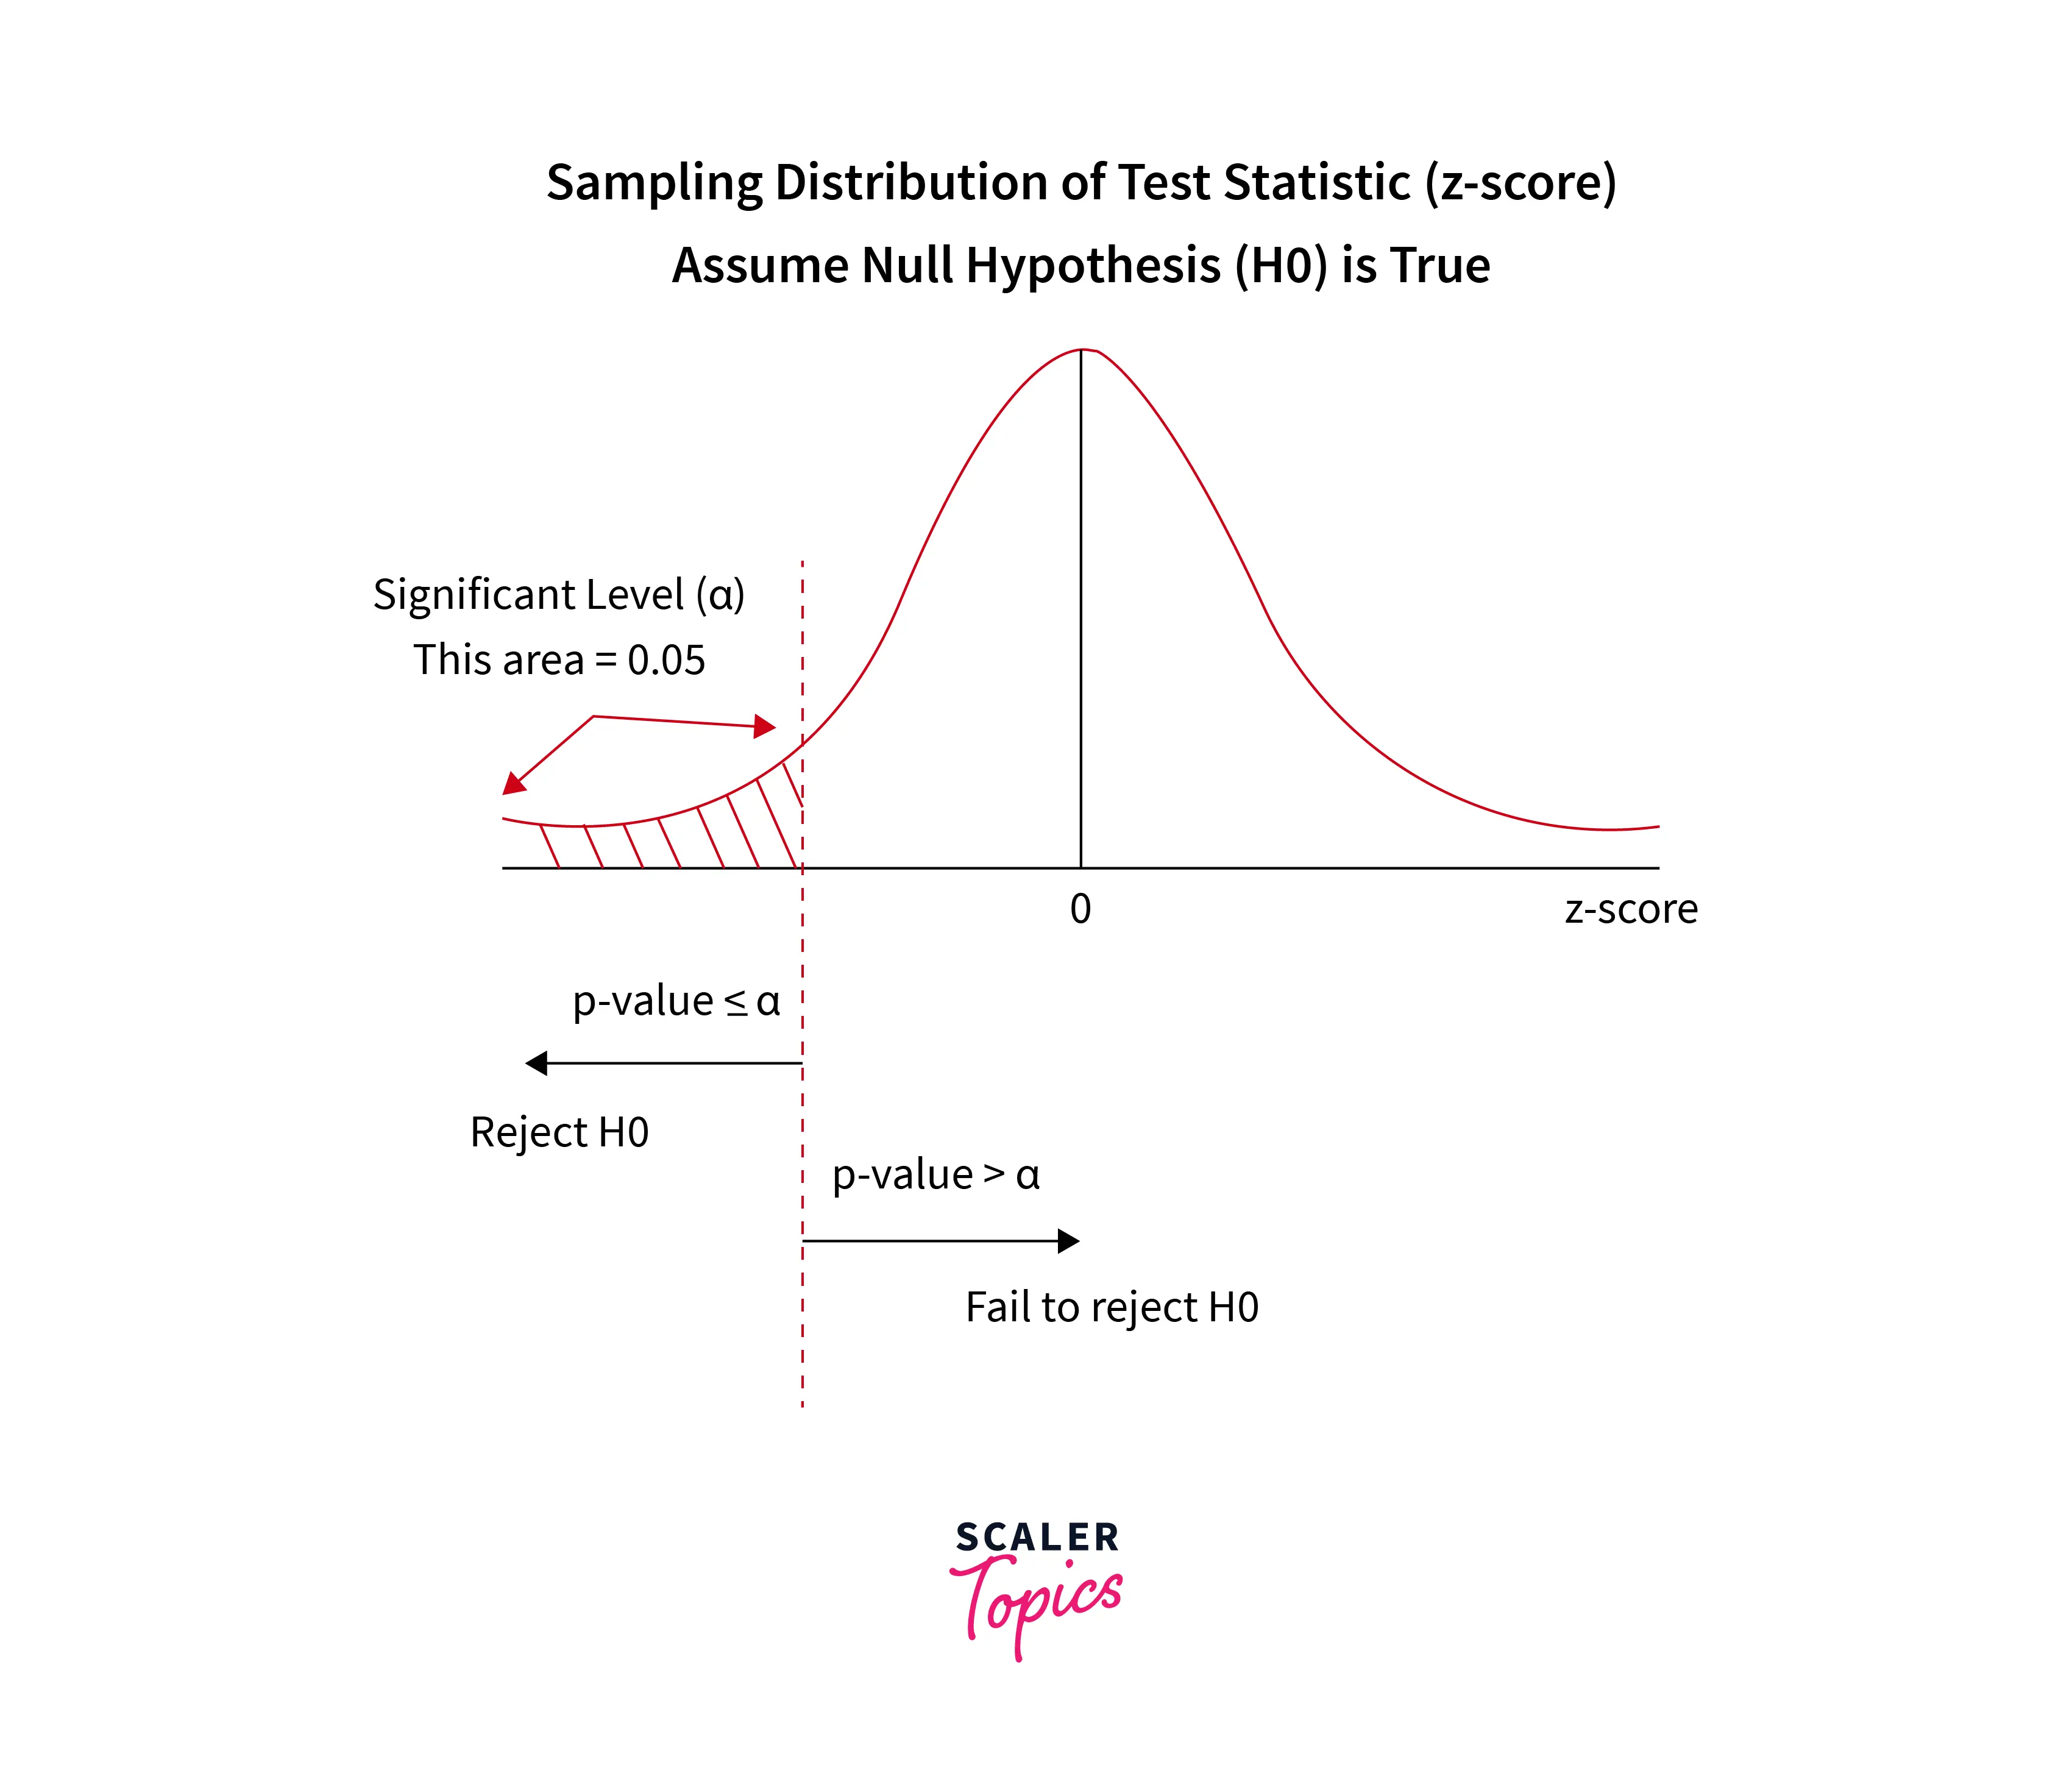
Probability can be described as the foundation of Machine Learning. Most of the Machine Learning models run on probability. Probability measures the level of certainty associated with an ambiguous event. In hypothesis testing, the probability is also known as P-Value, and it lies between 0 and 1. The P-value in Hypothesis Testing signifies whether the statistical hypothesis (H1) is true. This means that the lesser the P value, the better the chances for the null hypothesis to be true.
This threshold for P-Value is known as the Level of Significance. The main condition regarding the Level of Significance is:
If the p-value is equal to or less than 0.05 (depending on the use case), then the result can be called significant.
The P value is the probability that the observed results would occur if the null hypothesis were true. So a p-value less than 0.05 means that the observed results would occur less than five out of a hundred times if the null hypothesis is true. Hence, we must reject the null hypothesis. However, if the p-value is greater than 0.05, the null hypothesis is not rejected because the deviation from it is not statistically significant.
Error Measurement in Classification Problems
Now that we have covered what errors are in Machine Learning and how they influence the accuracy of our model, let us dive deep into the various types of error measurement metrics used in Machine Learning.
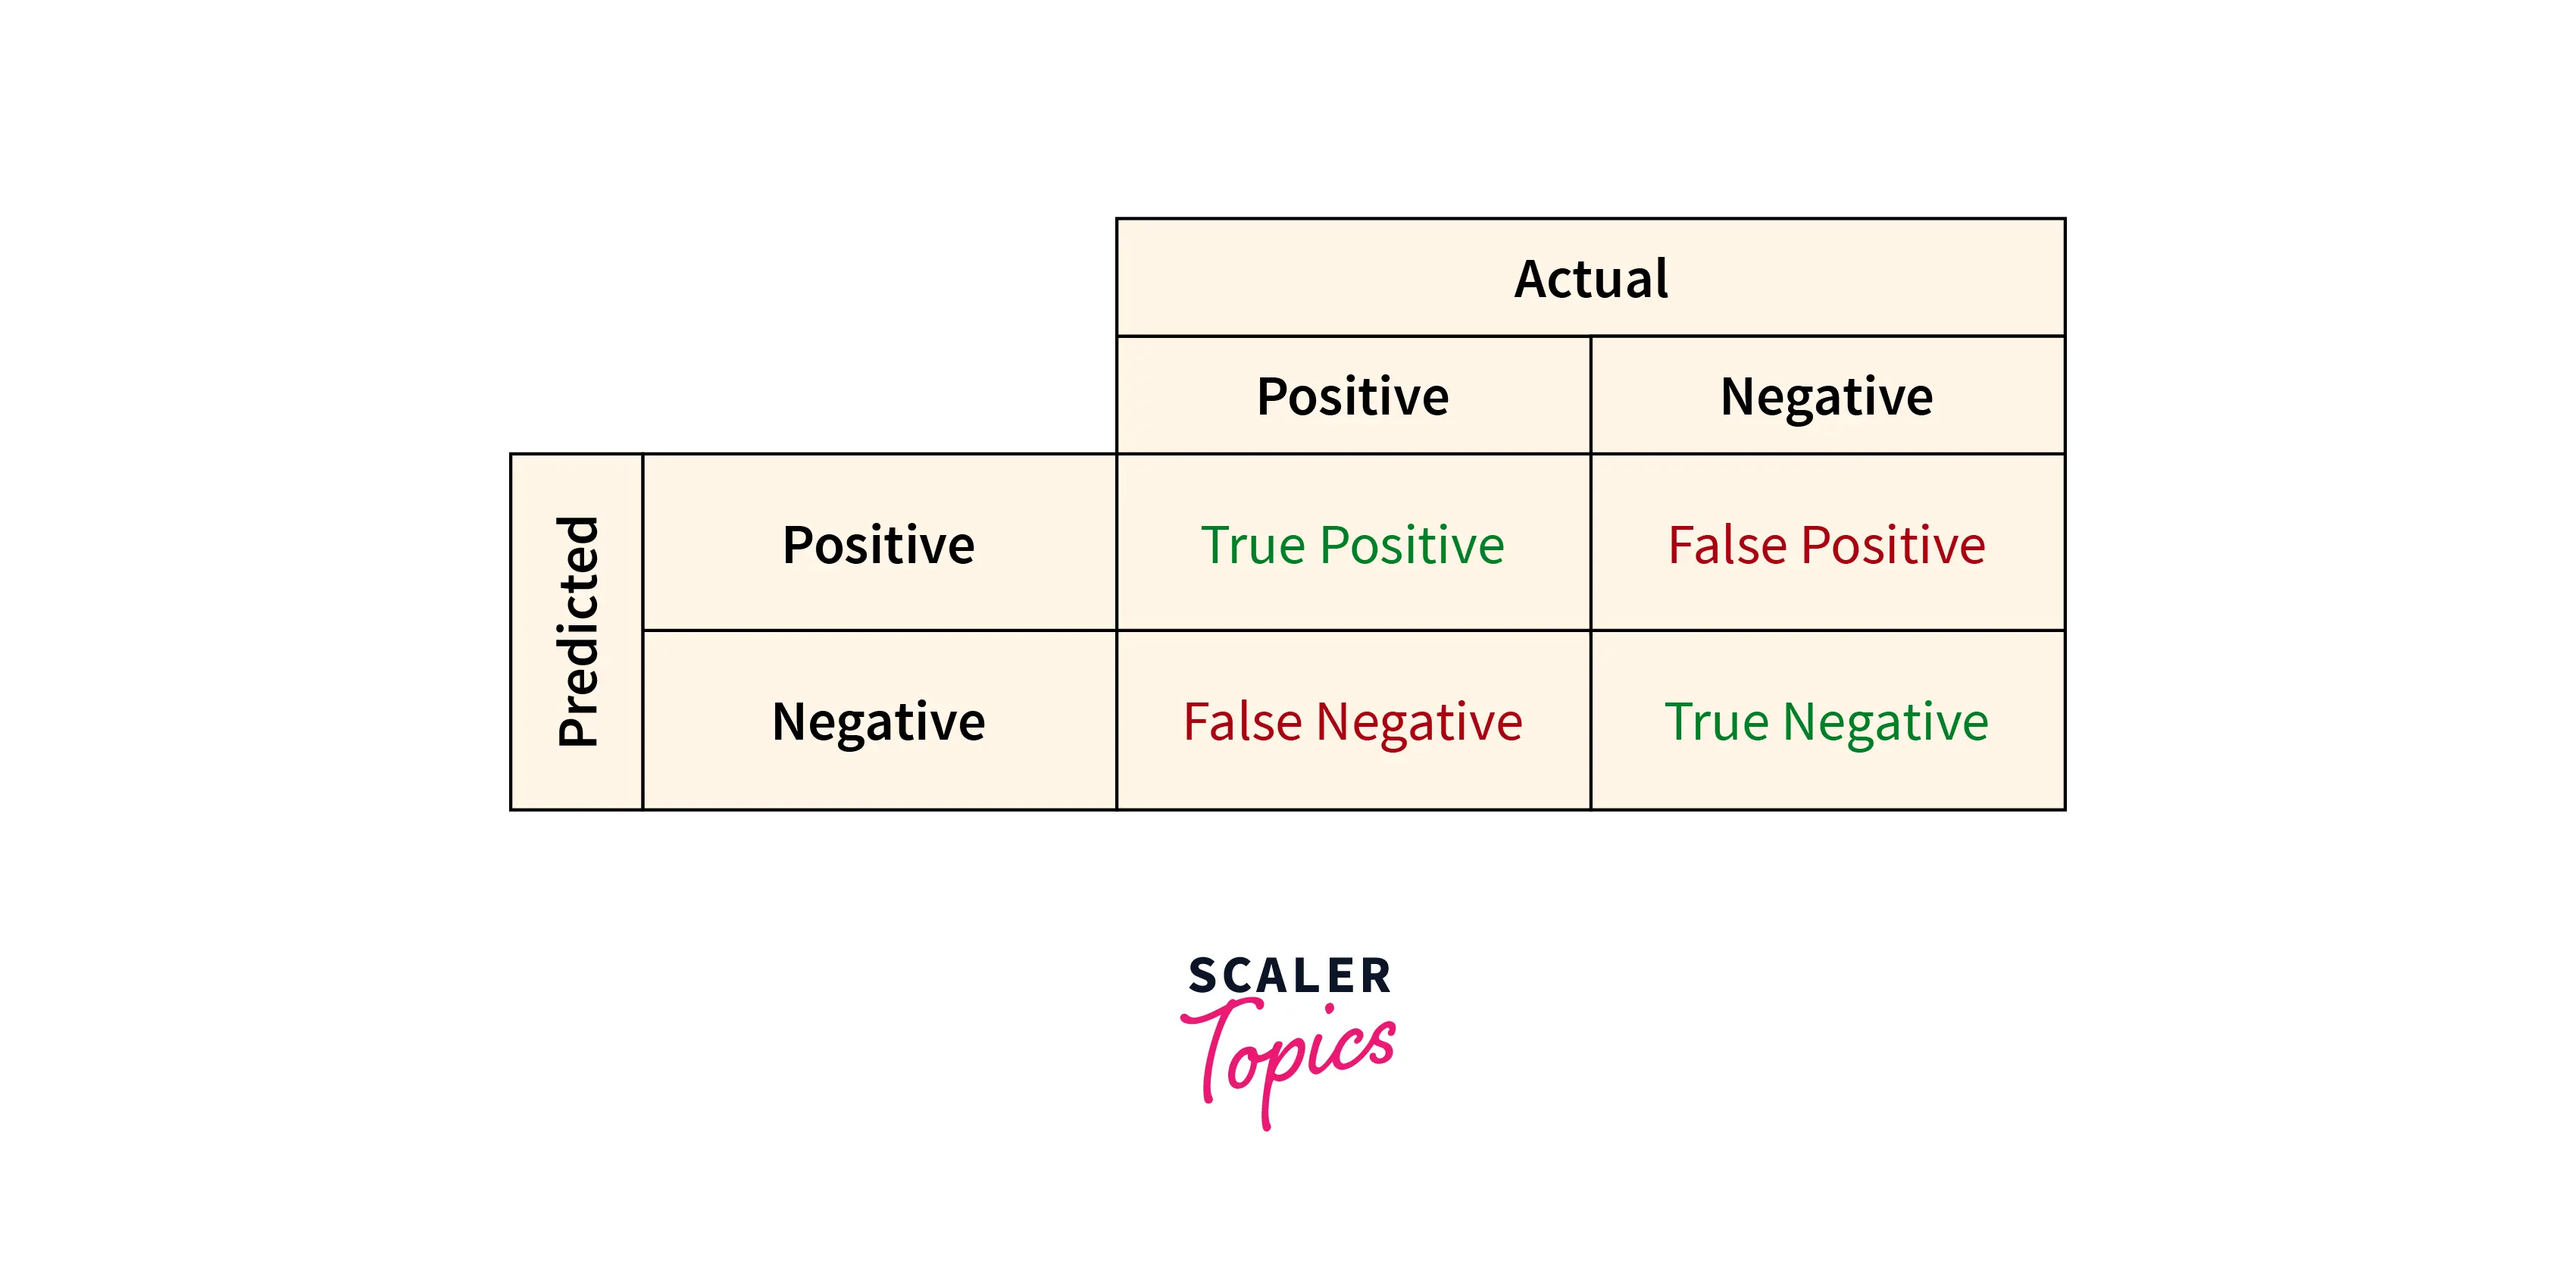
Error Measurements are mostly used in binary classification problems (determining if a certain observation is right or not). There are four types of error measurement methods in classification problems:
- True Positive (TP) When the observation from the dataset is true, and the value calculated using our model comes out to be true, we have a true positive scenario.
- False Positive (FP) In the False Positive error, the value in the dataset is true, while the computed value appears to be false. It is also known as Type I error.
- False Negative (NP) A false negative error is one where the computed value is false while the value in the dataset is true. It is also called Type II error.
- True Negative (TN) Similar to True Positive, True Negative happens when the value computed is the same as the value in the dataset, the value being false.
Confusion Matrix
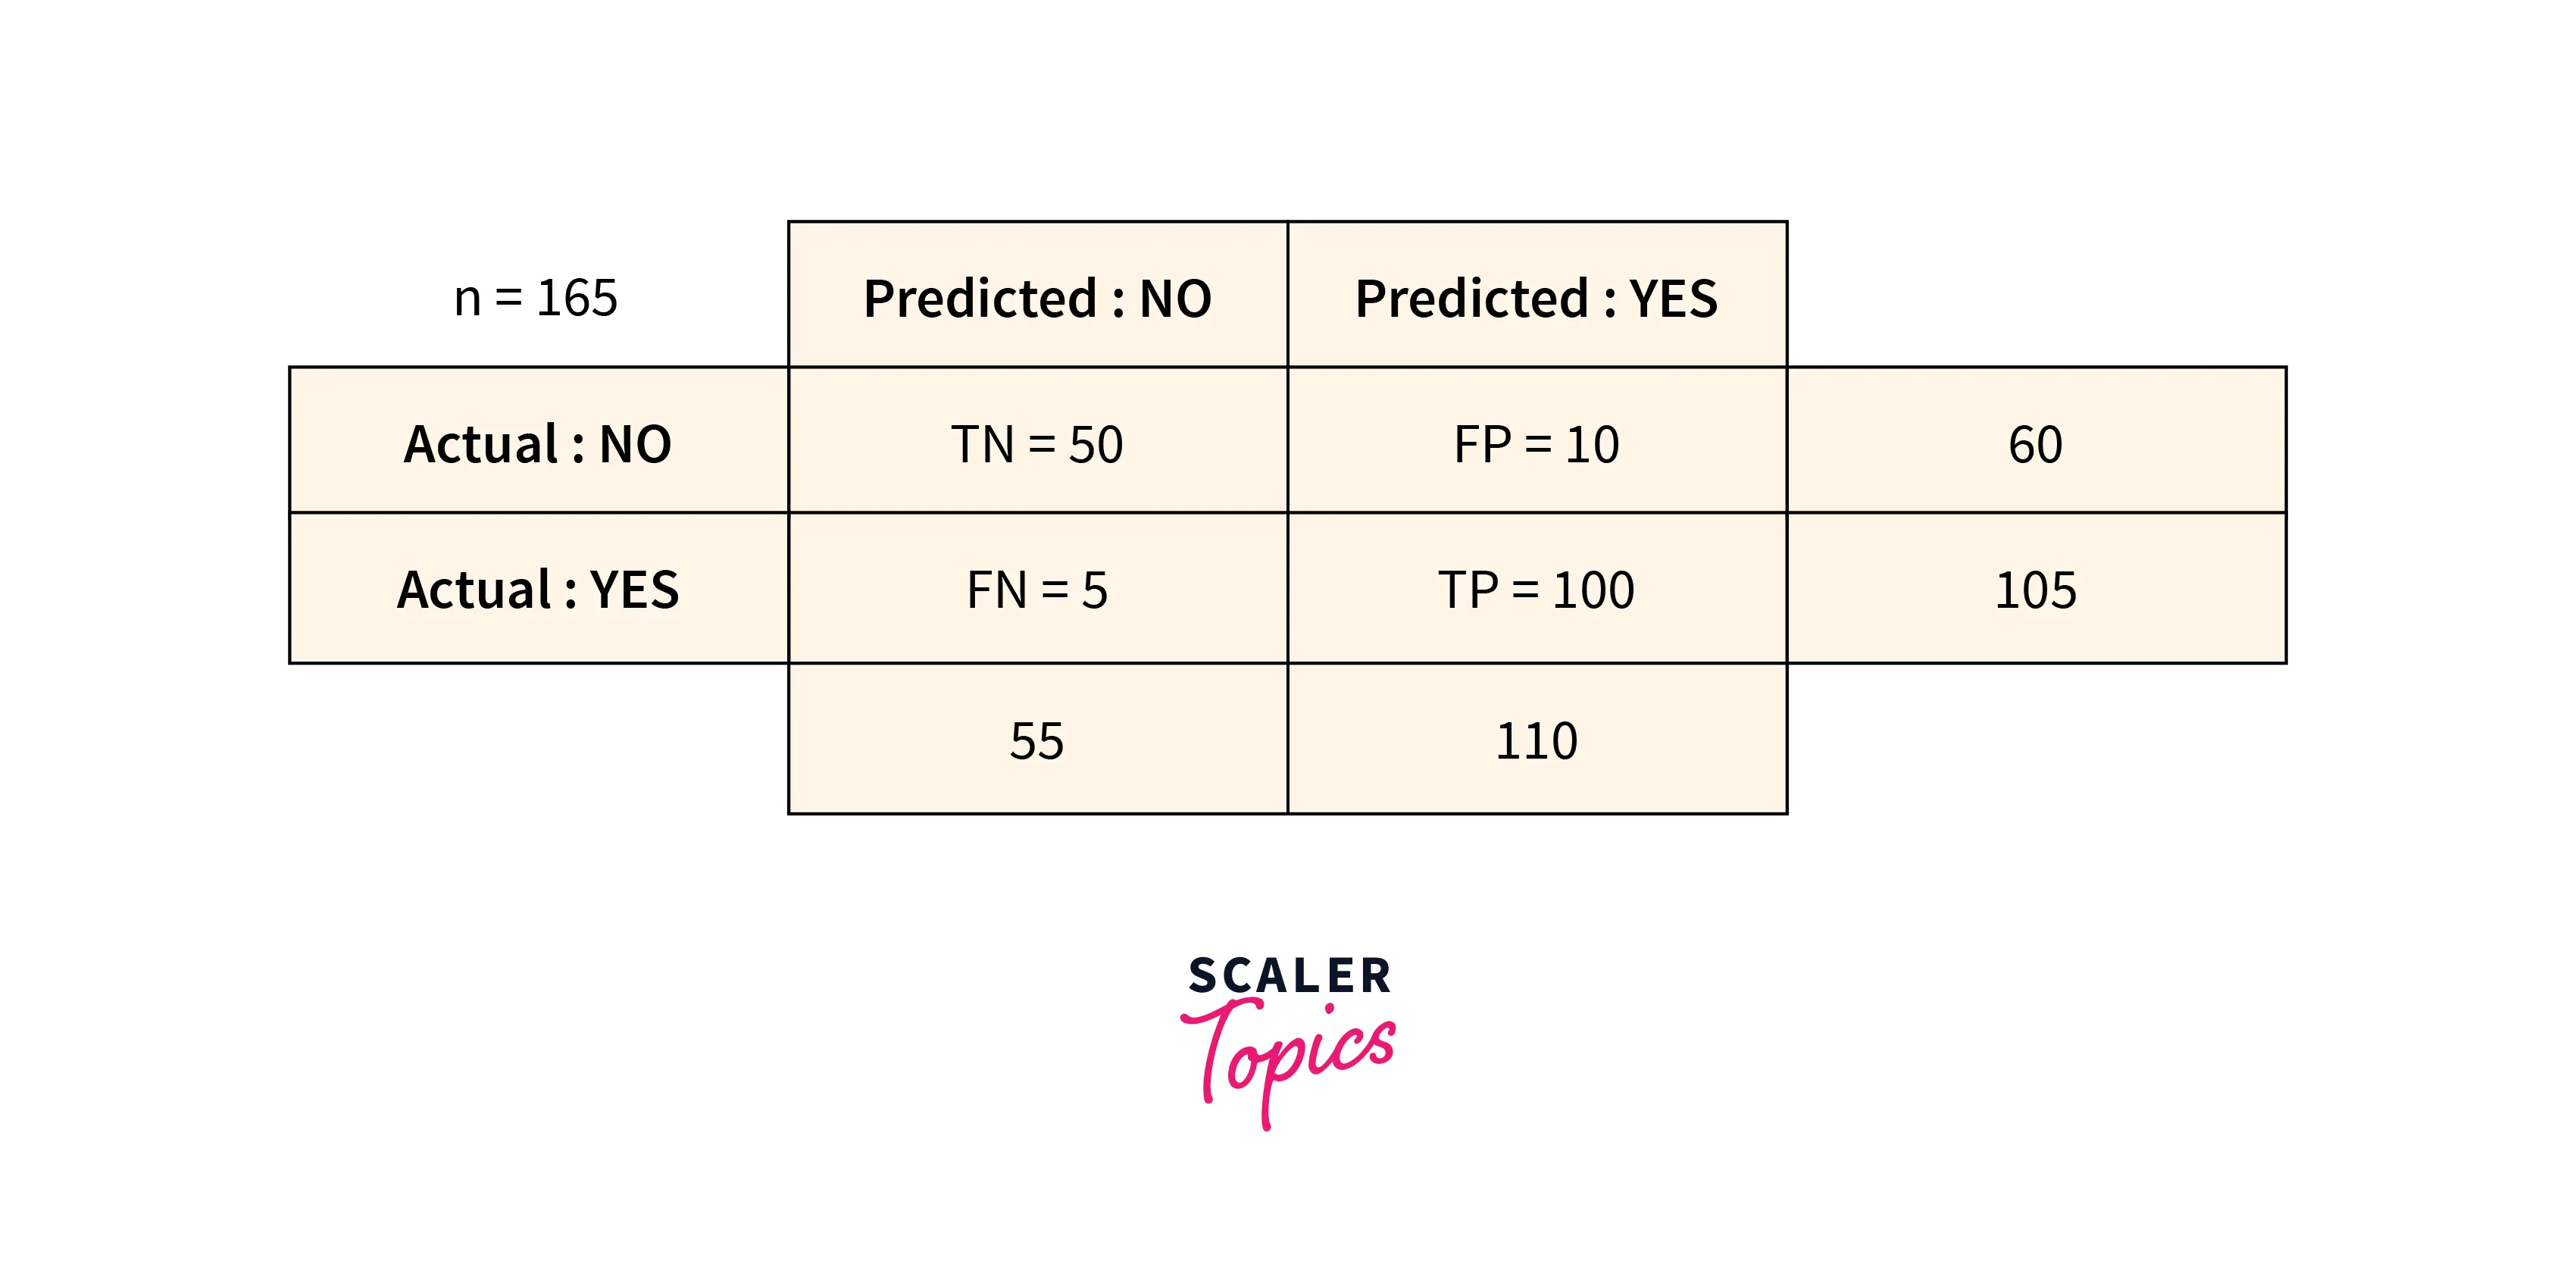
An additional method to measure errors in the Machine Learning model is a Confusion Matrix. It is an upgrade over the methods discussed earlier in this article; it computes metrics like recall, precision, specificity, accuracy, and ROC scores.
-
Recall Recall, also known as sensitivity, is the proportion of correctly predicted positive observations to all of the actual class's observations.
-
Precision The proportion of accurately anticipated positive observations to all predicted positive observations is known as precision.
-
Accuracy Accuracy, the proportion of properly predicted observations to all observations, is the most used performance metric.
-
ROC Score The ROC (Reciever Operating Characteristic) score is the slope of a ROC plot, which shows the performance of a classification model at all classification thresholds. The two parameters for the ROC score are True Positive Rate and False Positive Rate
Conclusion
- In this article, we learned about errors in Machine Learning, their purpose, and the different ways they are calculated.
- Importance of fundamentals in Machine Learning like Hypothesis Testing and Probability were covered.
- To conclude, we learned about the various error measurement metrics used to calculate the accuracy and precision of Machine Learning models, which help them be more robust.
Turn Learning into Career Growth
FAQs
What are the main types of errors in machine learning?
Model prediction error has three components. Bias comes from a model that is too simple. Variance comes from a model that is too sensitive to its training data. Irreducible error comes from noise. For classifiers, errors are also described as Type I (false positives) and Type II (false negatives).
What is the difference between reducible and irreducible error?
Reducible error is the part of the total error you can lower by choosing a better model, tuning it, or adding data. It consists of bias and variance. Irreducible error comes from randomness and unmeasured factors in the data itself, so no model can remove it, however good it is.
What is the difference between Type I and Type II errors in machine learning?
A Type I error is a false positive: the model predicts the positive class when the truth is negative, such as flagging a genuine payment as fraud. A Type II error is a false negative: the model misses a real positive. Moving the decision threshold reduces one type at the cost of the other.
Is high bias underfitting or overfitting?
High bias means underfitting. The model is too simple to capture the real pattern, so both training error and test error stay high. High variance means overfitting: the model memorises the training data, giving very low training error but much higher error on new, unseen data.
What does a low p-value mean?
A low p-value, typically below 0.05, means results this extreme would be unlikely if the null hypothesis were true. That is evidence against the null hypothesis, so it is rejected. A high p-value does not prove the null hypothesis. It only means the data does not give enough evidence against it.


