

Title: CPU Scheduling in Operating System: Types & Algorithms
Overview
CPU scheduling is the task performed by the CPU that decides the way and order in which processes should be executed. There are two types of CPU scheduling - Preemptive, and non-preemptive. The criteria the CPU takes into consideration while "scheduling" these processes are - CPU utilization, throughput, turnaround time, waiting time, and response time.
What is CPU Scheduling?
CPU scheduling is the process by which an operating system decides which of the ready processes gets the CPU next, and for how long. It exists because the CPU can run only one process at a time. A scheduling algorithm makes that choice using criteria such as arrival time, burst time, and priority.
Before we get to CPU scheduling, let's define a process. A process is essentially just a set of instructions or a program in execution.The operating system maintains information about each process in a process control block, including details such as its current state and other execution-related information. This explains what the process control block stores.

As you can see in the diagram above, we have processes that come from the job queue to the ready queue (in primary memory) that are one by one, in some manner given resources, and then their execution is completed.
Say you have a uni programming system (like MS-DOS) and a process that requires I/O is being executed. While it waits for the I/O operations to complete, the CPU remains idle. This is wrong, because we're wasting the resources of the CPU, as well as time, and might result in some processes waiting too long for their execution.
In multiprogramming systems, however, the CPU does not remain idle whenever a process currently executing waits for I/O. It starts the execution of other processes, making an attempt to maximize CPU utilization. How does the CPU decide which process should be executed next from the ready queue for maximum utilization of the CPU? This procedure of "scheduling" the processes, is called CPU scheduling.
What are the Types of CPU Scheduling?
There are essential 4 conditions under which CPU scheduling decisions are taken:
- If a process is making the switch between the running state to the waiting state (could be for an I/O request, or invocation of wait() for terminating one of its child processes)
- If a process is making the switch from the running state to the ready state (on the occurrence of an interrupt, for example)
- If a process is making the switch between waiting and ready state (e.g. when its I/O request completes)
- If a process terminates upon completion of execution.
So in the case of conditions 1 and 4, the CPU does not really have a choice of scheduling, if a process exists in the ready queue the CPU's response to this would be to select it for execution. In cases 2 and 3, the CPU has a choice of selecting a particular process for executing next.
There are mainly two types of CPU scheduling:
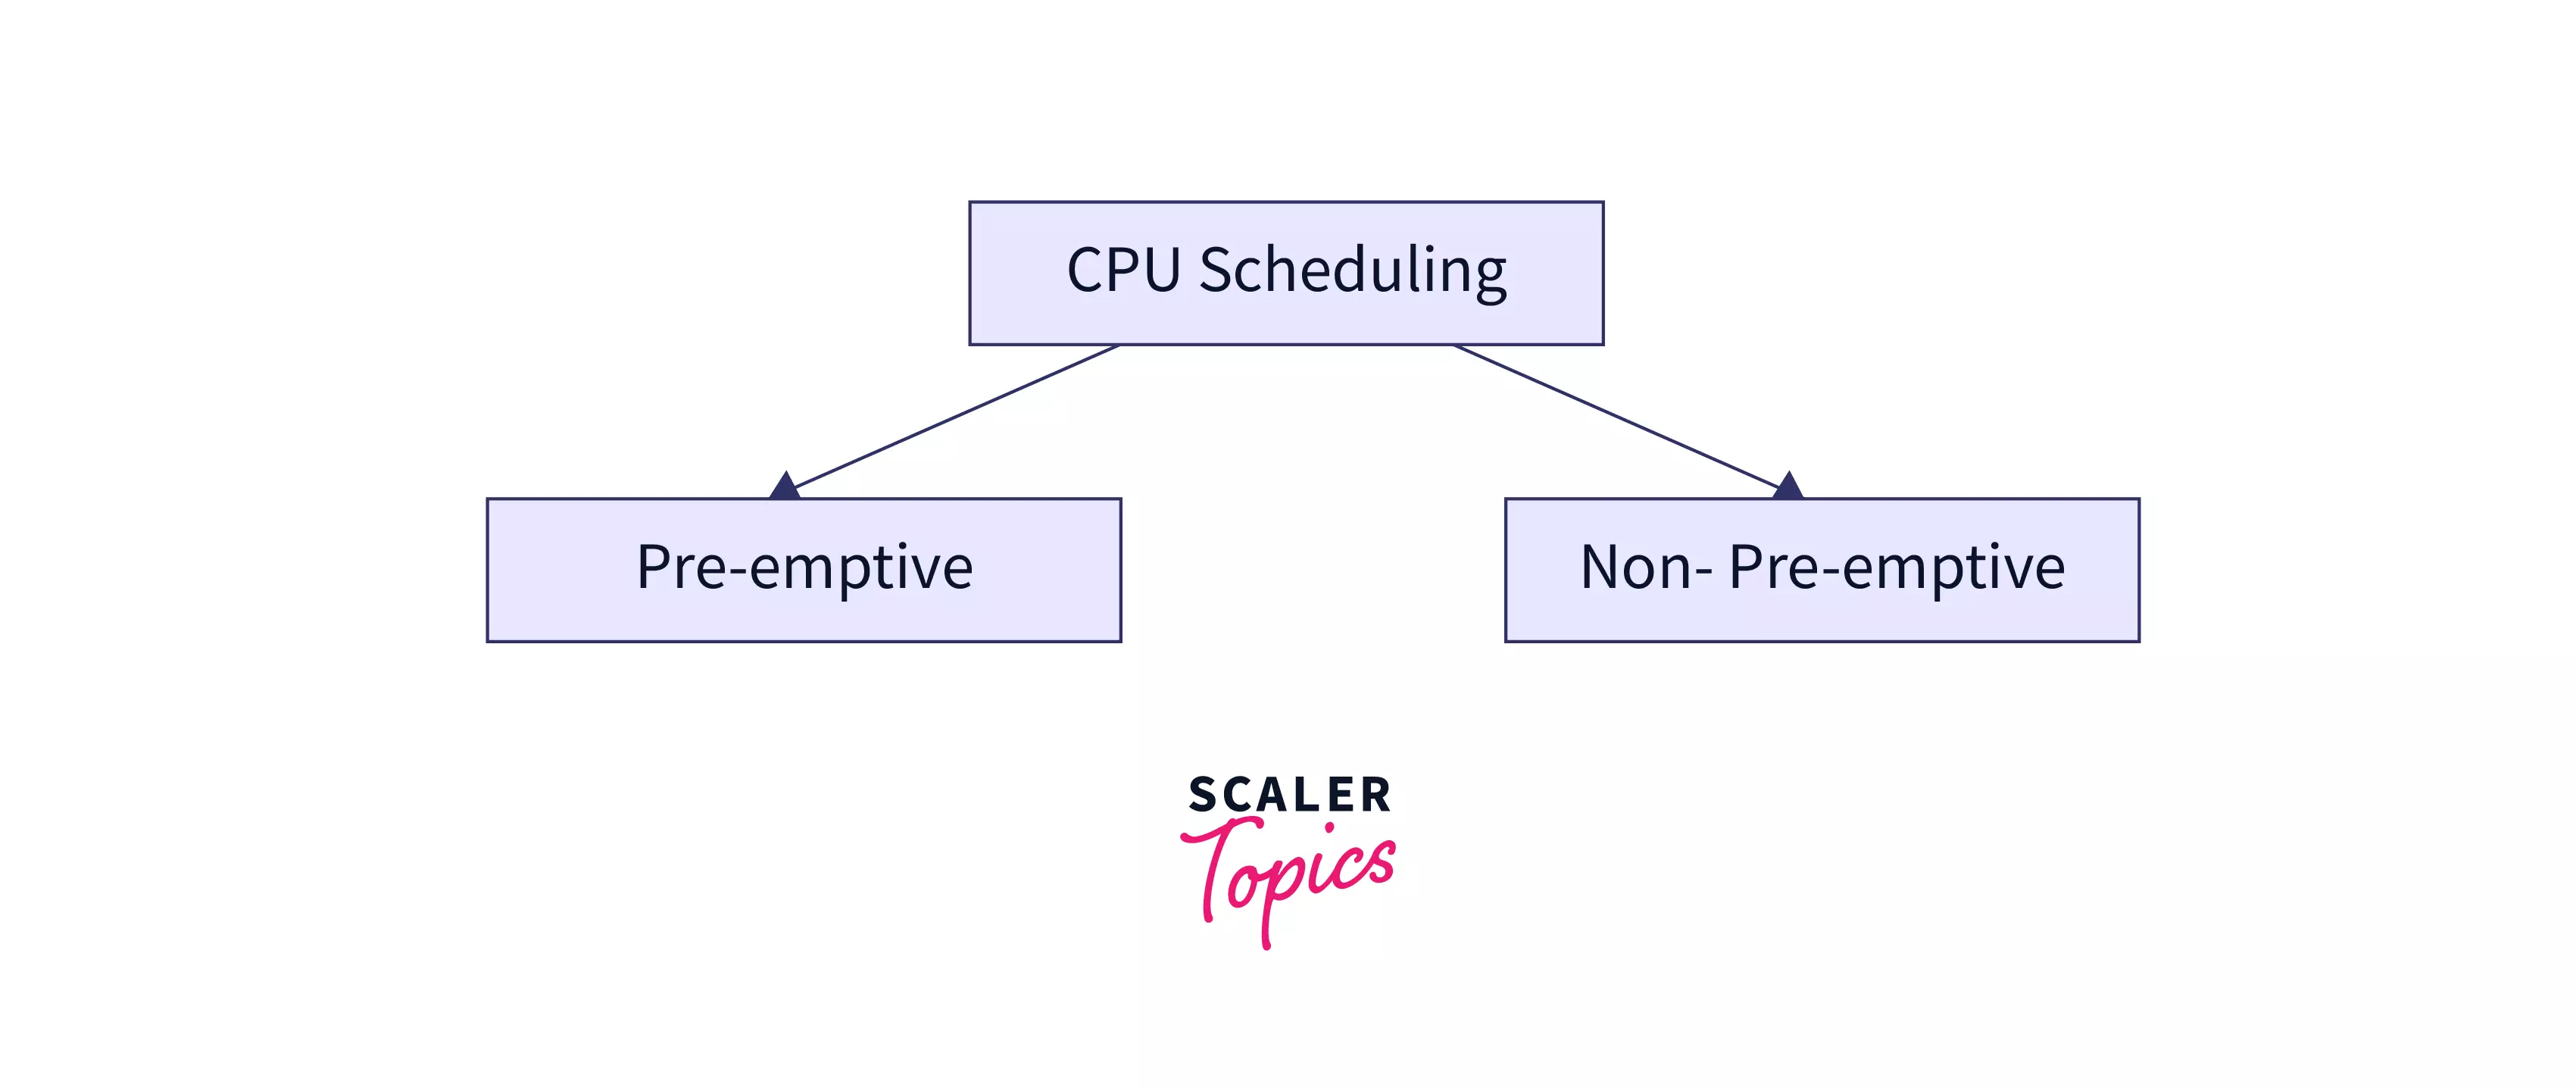
| Preemptive Scheduling | Non-Preemptive Scheduling |
|---|---|
| The running process can be interrupted, and the CPU can be assigned to another process. | Once a process gets the CPU, it continues until it terminates or moves to the waiting state. |
| More context switching can take place because a running process may be interrupted. | Fewer context switches are required because the running process is not interrupted. |
| Generally has higher scheduling overhead due to context switching. | Generally has lower scheduling overhead. |
| Starvation can occur in algorithms such as preemptive priority scheduling. | Starvation can occur in algorithms such as non-preemptive SJF and priority scheduling. |
| Commonly used where quick response to processes is important, such as interactive and time-sharing systems. | Commonly used where processes can run to completion without requiring frequent interruption, such as batch systems. |
Build an AI-First Career, Master the Complete Skillset
Choose from our industry-leading programs designed for career success
Modern Software and AI Engineering Program
Master full-stack development with AI integration


 +1000 more
Modern Data Science and ML with specialisation in AI
Advanced data science techniques with AI specialization
+1000 moreAdvanced AIML with Specialisation in Agentic AI
Deep dive into AIML with focus on Agentic systems
+1000 moreDevOps, Cloud & AI Platform Engineering
Build and manage AI-powered cloud infrastructure
+1000 moreAI Engineering Advanced Certification by IIT-Roorkee
Premier AI engineering certification from IIT-Roorkee

AI Forward Deployed Engineer Program
Full-stack engineering, production AI and client-facing consulting
+1000 moreNon-Preemptive Scheduling
In the case of non-preemptive scheduling, new processes are executed only after the current process has completed its execution. The process holds the resources of the CPU (CPU time) till its state changes to terminated or is pushed to the process waiting state. If a process is currently being executed by the CPU, it is not interrupted till it is completed.
Once the process has completed its execution, the processer picks the next process from the ready queue (the queue in which all processes that are ready for execution are stored).
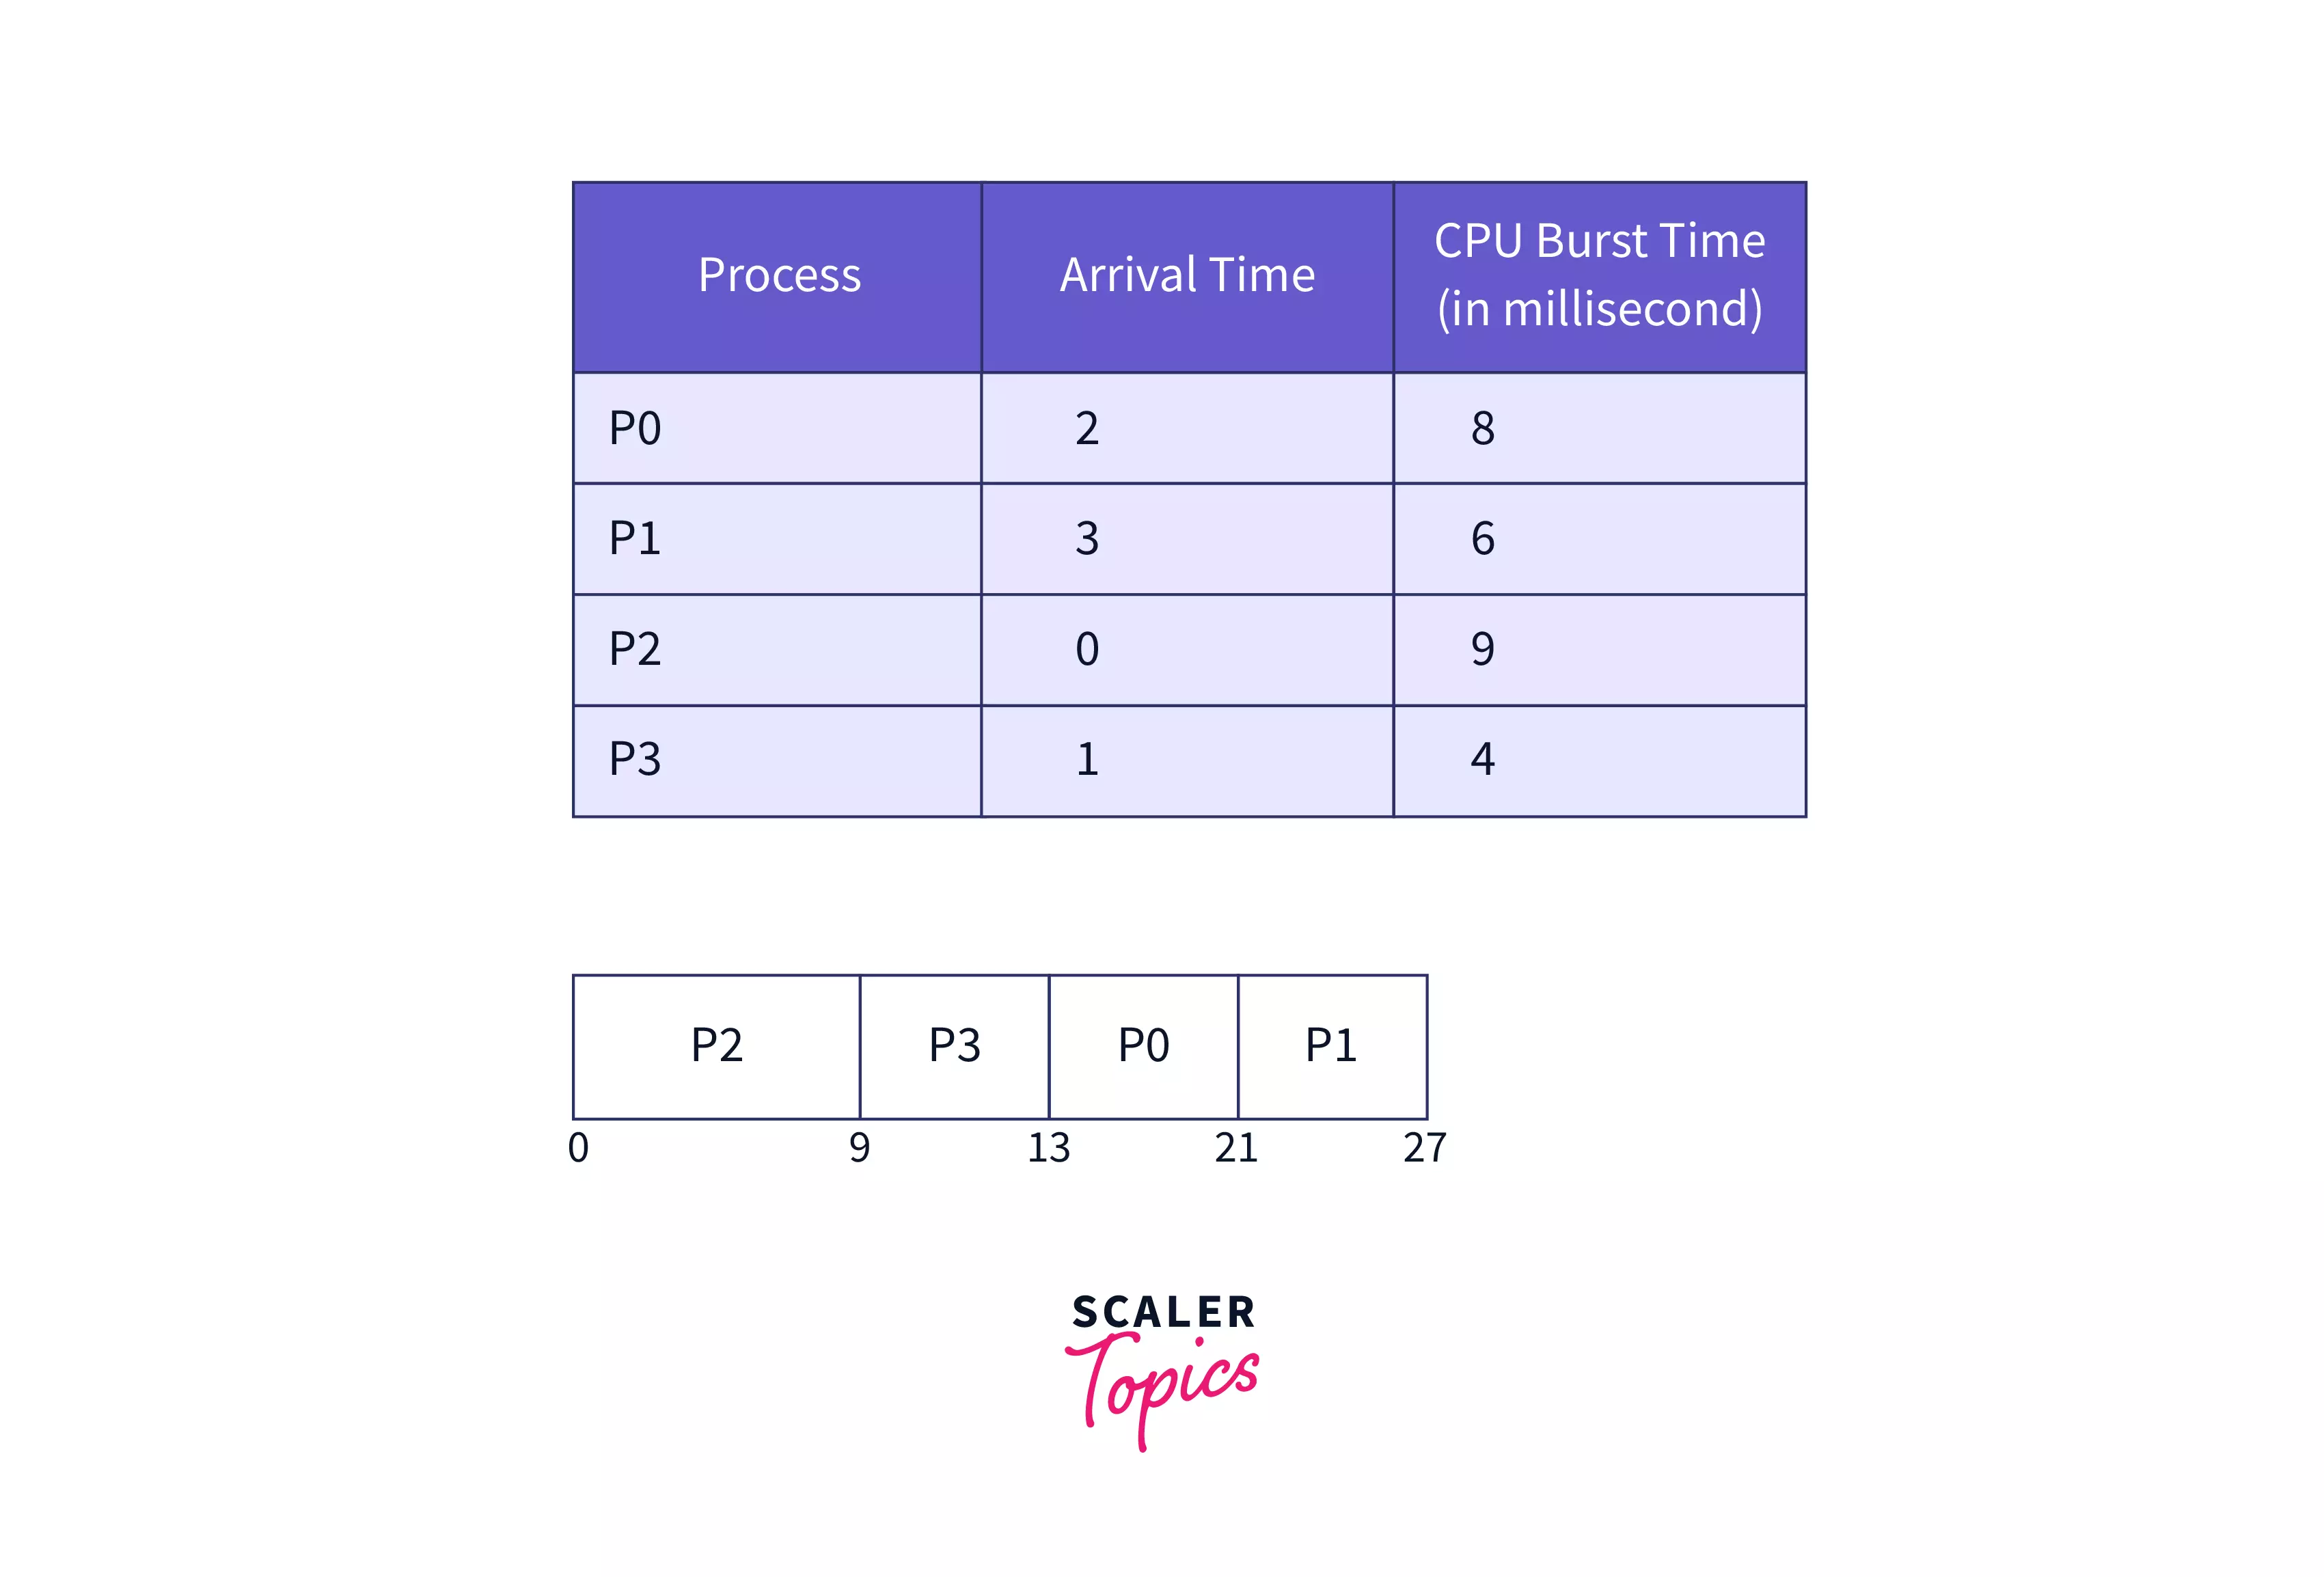
For Example:
In the worked example below, we use the same four processes throughout the different scheduling algorithms. Under non-preemptive FCFS, P1 arrives at time 0 and starts execution first. Although P2, P3, and P4 arrive while P1 is running, none of them can interrupt P1. P1 therefore continues until time 5, after which the remaining processes are executed in their arrival order.
Preemptive Scheduling
Preemptive scheduling takes into consideration the fact that some processes could have a higher priority and hence must be executed before the processes that have a lower priority.
In preemptive scheduling, the CPU resource is allocated to a process for only a limited period of time and then those resources are taken back and assigned to another process (the next in execution). If the process was yet to complete its execution, it is placed back in the ready state, where it will remain till it gets a chance to execute once again.
So, when we take a look at the conditions under which CPU scheduling decisions are taken on the basis of which CPU provides its resources to processes, we can see that there isn't really a choice in making a decision when it comes to condition 1 and 4. If we have a process in the ready queue, we must select it for execution.
However, we do have a choice in conditions 2 and 3. If we opt to make the choice of scheduling only if a process terminates (condition 4) or if the current process execution is waiting for I/O (condition 1) then we can say that our scheduling is non-preemptive, however, if we make scheduling decisions in other conditions as well, we can say that our scheduling process is preemptive.
Important CPU Scheduling Terminologies
Let's now discuss some important terminologies that are relevant to CPU scheduling.
- Arrival time: Arrival time (AT) is the time at which a process arrives at the ready queue.
- Burst Time: As you may have seen the third column is 'burst time', It is the time required by the CPU to complete the execution of a process, or the amount of time required for the execution of a process. It is also sometimes called the execution time or running time.
- Completion Time: As the name suggests, completion time is the time at when a process completes its execution. It is not to be confused with burst time.
- Turn-Around Time: Also written as TAT, turn-around time is simply the difference between completion time and arrival time (Completion time - arrival time).
- Waiting Time: The Waiting time (WT) of a process is the difference between turn around time and burst time (TAT - BT), i.e. the amount of time a process waits to get CPU resources in the ready queue.
- Response Time: Response time (RT) of a process is the time after which any process gets CPU resources allocated after entering the ready queue.
The key CPU scheduling formulas are:
- Turnaround Time = Completion Time − Arrival Time
- Waiting Time = Turnaround Time − Burst Time
- Response Time = First CPU Allocation − Arrival Time
CPU Scheduling Criteria
Now if the CPU needs to schedule these processes, it must definitely do it wisely. What are the wise decisions it should make to create the "best" scheduling?
- CPU Utilization: It would make sense if the scheduling was done in such a way that the CPU is utilized to its maximum. If a scheduling algorithm does not waste any CPU cycle or makes the CPU work most of the time (100% of the time, ideally), then the scheduling algorithm can be considered good.
- Throughput: Throughput by definition is the total number of processes that are completed (executed) per unit of time or, in simpler terms, it is the total work done by the CPU in a unit of time. Now, of course, an algorithm must work to maximize throughput.
- Turn Around Time: The turnaround time is essentially the total time that it took for a process to arrive in the ready queue and complete. A good CPU scheduling criteria would be able to minimize this time taken.
- Waiting Time: A scheduling algorithm obviously cannot change the time that is required by a process to complete its execution, however, it can minimize the waiting time of the process.
- Response Time: If your system is interactive, then taking into consideration simply the turnaround time to judge a scheduling algorithm is not good enough. A process might produce results quicker, and then continue to compute new results while the outputs of previous operations are being shown to the user. Hence, we have another CPU scheduling criteria, which is the response time (time taken from submission of the process until its first 'response' is produced). The goal of the CPU would be to minimize this time.

Become the Ai engineer who can design, build, and iterate real AI products, not just demos with an IIT Roorkee CEC Certification

AI Engineering Course Advanced Certification by IIT-Roorkee CEC
A hands on AI engineering program covering Machine Learning, Generative AI, and LLMs - designed for working professionals & delivered by IIT Roorkee in collaboration with Scaler.
Enrol Now
What is the Need for CPU Scheduling Algorithm?
CPU (Central Processing Unit) scheduling algorithm is needed to efficiently allocate the available processing time of a CPU among multiple processes that are competing for the CPU's resources.
The need for CPU scheduling arises because modern operating systems allow multiple processes to execute concurrently on a single CPU. When multiple processes are running, they contend for the CPU's resources, and the CPU must choose which process to execute at any given moment.
The CPU scheduling algorithm determines the order in which processes are executed and how much CPU time each process is allocated. A good CPU scheduling algorithm should ensure that each process gets a fair share of the CPU time, while also maximizing overall system throughput and minimizing response time.
CPU scheduling determines which process gets CPU time, while process synchronisation deals with coordinating processes when they need to work with shared resources.
Types of CPU scheduling Algorithms
There are several types of CPU scheduling algorithms, each with its own strengths and weaknesses. Some of the most common types of CPU scheduling algorithms include:
-
First-Come, First-Served (FCFS): The simplest CPU scheduling algorithm, in which processes are executed in the order in which they arrive. Its implementation is covered in FCFS scheduling implemented in C.
Preemptive: No. FCFS is a non-preemptive scheduling algorithm.
-
Shortest Job First (SJF): This algorithm schedules processes based on their expected CPU burst time. The process with the shortest expected burst time is executed first.
Preemptive: No. The version described here is non-preemptive SJF. SJF selects the process with the shortest expected CPU burst time. The same scheduling logic is demonstrated through shortest job first scheduling in C.
-
Shortest Remaining Time First (SRTF): This is the preemptive version of SJF. The process with the shortest remaining CPU burst time is selected for execution. If a new process arrives with a shorter remaining burst time than the currently running process, the CPU can be assigned to the new process.
Preemptive: Yes.
-
Priority Scheduling: This algorithm assigns a priority value to each process, and processes with higher priority values are executed first.
Preemptive: It can be either preemptive or non-preemptive, depending on the scheduling method used.
-
Round Robin (RR): This algorithm allocates a fixed time slice (quantum) to each process in a cyclic order. If a process has not completed its execution within its allotted time slice, it is preempted, and the next process in the queue is executed. Learn more about round robin scheduling with a worked example.
Preemptive: Yes.
-
Multilevel Queue Scheduling: This algorithm divides the processes into separate queues based on their characteristics. Each queue has its own scheduling algorithm, and processes are moved between queues based on their priority or other criteria.
Preemptive: It depends on how the queues and scheduling algorithms are configured.
-
Multilevel Feedback Queue Scheduling: This algorithm is an extension of multilevel queue scheduling that allows processes to move between queues based on their behavior. For example, a process that uses a lot of CPU time may be moved to a lower-priority queue to make room for other processes.
Preemptive: Yes.
Comparison between Various CPU Scheduling Algorithms
Here is a comparison between various CPU scheduling algorithms:
Comparison between Various CPU Scheduling Algorithms
Here is a comparison between various CPU scheduling algorithms:
| Algorithm | Preemptive? | Selection Criterion | Starvation Risk | Convoy Effect | Typical Use |
|---|---|---|---|---|---|
| FCFS | No | Arrival order | No | Yes | Batch systems |
| SJF | No | Shortest burst | Yes | No | Batch, burst times known |
| SRTF | Yes | Shortest remaining burst | Yes | No | Short-job-favouring systems |
| Priority (non-preemptive) | No | Highest priority | Yes | No | Systems with fixed job classes |
| Priority (preemptive) | Yes | Highest priority | Yes | No | Real-time systems |
| Round Robin | Yes | Fixed time quantum | No | No | Time-sharing, interactive |
| Multilevel Queue | Depends on queue | Queue membership | Yes | No | Mixed foreground/background |
| Multilevel Feedback Queue | Yes | Queue + observed behaviour | Reduced (with ageing) | No | General-purpose OS |
Starvation occurs when a process keeps waiting because other processes are repeatedly selected for execution before it. This is different from deadlock, where processes remain blocked while waiting for resources held by one another. The difference between starvation and deadlock explains how the two conditions differ.
Convoy effect occurs when several shorter processes have to wait because a long process is occupying the CPU ahead of them.
Please note: Average waiting time is not included in the comparison because it depends on the set of processes being scheduled, not just on the algorithm.
CPU scheduling is one of the three OS topics that appear in almost every campus and product-company interview, alongside deadlocks and memory management. Being able to draw the Gantt chart and compute average waiting time under time pressure is what is actually tested. Scaler's free operating systems course works through these algorithms end to end.
How Scaler Transformed Careers in Different Fields
Scaler learners achieved 2.5x salary growth with average post-Scaler CTC reaching ₹23L.
 Google
 Amazon
 Microsoft
 Flipkart
 Adobe1200+ more
Worked Example of CPU Scheduling
Let's use the same set of processes to see how different CPU scheduling algorithms affect waiting time and turnaround time.
| Process | Arrival Time (AT) | Burst Time (BT) |
|---|---|---|
| P1 | 0 | 5 |
| P2 | 1 | 3 |
| P3 | 2 | 1 |
| P4 | 3 | 2 |
We will apply FCFS, non-preemptive SJF, and Round Robin to these processes. For Round Robin, the time quantum is 2 units.
FCFS Scheduling
In First Come, First Served (FCFS), processes are executed in the order in which they arrive.
P1 arrives at time 0, so it starts first and runs for 5 units. By the time P1 finishes, P2, P3, and P4 have arrived. They are then executed in their arrival order.
Gantt Chart:
| P1 | P2 | P3 | P4 |
|---|
0 5 8 9 11
The completion time (CT) for P1 is 5, P2 is 8, P3 is 9, and P4 is 11.
| Process | AT | BT | CT | TAT = CT − AT | WT = TAT − BT |
|---|---|---|---|---|---|
| P1 | 0 | 5 | 5 | 5 | 0 |
| P2 | 1 | 3 | 8 | 7 | 4 |
| P3 | 2 | 1 | 9 | 7 | 6 |
| P4 | 3 | 2 | 11 | 8 | 6 |
| Average | 6.75 | 4.00 |
Therefore, the average waiting time is 4.00 units, and the average turnaround time is 6.75 units.
SJF Scheduling
In non-preemptive Shortest Job First (SJF), the process with the shortest burst time among the available processes is selected next.
At time 0, only P1 is available, so it runs first. When P1 finishes at time 5, P2, P3, and P4 are available. P3 has the shortest burst time, followed by P4 and P2.
Gantt Chart:
| P1 | P3 | P4 | P2 |
|---|
0 5 6 8 11
The completion time (CT) for P1 is 5, P3 is 6, P4 is 8, and P2 is 11.
| Process | AT | BT | CT | TAT = CT − AT | WT = TAT − BT |
|---|---|---|---|---|---|
| P1 | 0 | 5 | 5 | 5 | 0 |
| P2 | 1 | 3 | 11 | 10 | 7 |
| P3 | 2 | 1 | 6 | 4 | 3 |
| P4 | 3 | 2 | 8 | 5 | 3 |
| Average | 6.00 | 3.25 |
Therefore, the average waiting time is 3.25 units, and the average turnaround time is 6.00 units.
Round Robin Scheduling
In Round Robin scheduling, each process gets the CPU for a fixed period called the time quantum. If a process does not finish within that period, it goes to the back of the ready queue.
Here, the time quantum is 2 units.
P1 runs from time 0 to 2, followed by P2 from 2 to 4. P3 then runs from 4 to 5 and completes because its burst time is only 1 unit. P4 runs from 5 to 7 and also completes. P1 then gets another turn, followed by P2 and P1, until all processes finish.
Gantt Chart:
| P1 | P2 | P3 | P4 | P1 | P2 | P1 |
|---|
0 2 4 5 7 9 10 11
The completion time (CT) for P3 is 5, P4 is 7, P2 is 10, and P1 is 11.
| Process | AT | BT | CT | TAT = CT − AT | WT = TAT − BT |
|---|---|---|---|---|---|
| P1 | 0 | 5 | 11 | 11 | 6 |
| P2 | 1 | 3 | 10 | 9 | 6 |
| P3 | 2 | 1 | 5 | 3 | 2 |
| P4 | 3 | 2 | 7 | 4 | 2 |
| Average | 6.75 | 4.00 |
Therefore, the average waiting time is 4.00 units, and the average turnaround time is 6.75 units.
Comparing the Results
The same four processes produce different results under each scheduling algorithm:
| Algorithm | Average Waiting Time | Average Turnaround Time |
|---|---|---|
| FCFS | 4.00 | 6.75 |
| SJF | 3.25 | 6.00 |
| Round Robin (q = 2) | 4.00 | 6.75 |
The results show how the scheduling rule changes the order in which processes receive CPU time. Since the process set remains the same, the effect of each algorithm can be compared directly using waiting time and turnaround time.
*Want to master the Operating System? Enroll in our Operating System free course now and get certified!
Turn Learning into Career Growth
Conclusion
- CPU scheduling is the task performed by the CPU that decides the way the process would be executed.
- There are two types of CPU scheduling
- Preemptive
- CPU resources are allocated to a process for only a limited period of time and then those resources are taken back. A running process could be interrupted to execute a higher priority process.
- Non-preemptive
- New processes are executed only after the current executing process has completed its execution.
- Preemptive
- Some important terminologies relevant to CPU scheduling are:
- Arrival Time
- Burst Time
- Completion Time
- Turn Around Time
- Waiting Time
- Response Time
- CPU scheduling has certain criteria that it uses to schedule processes in the most efficient manner:
- CPU utilization (maximize)
- Throughput (maximize)
- Turn Around Time (minimize)
- Waiting Time (minimize)
- Response Time (minimize)
FAQs
1. What is CPU scheduling in an operating system?
CPU scheduling is the process by which an operating system decides which ready process gets the CPU next and for how long. Since multiple processes can be ready to execute at the same time, the operating system uses a scheduling algorithm to make this decision based on factors such as arrival time, burst time, priority, or time quantum.
2. What is the difference between preemptive and non-preemptive scheduling?
In preemptive scheduling, the operating system can interrupt a running process and assign the CPU to another process. In non-preemptive scheduling, a process continues using the CPU until it completes or blocks. Preemptive scheduling generally involves more context switching, while non-preemptive scheduling gives the running process uninterrupted CPU time.
3. Which CPU scheduling algorithm is best?
There is no single CPU scheduling algorithm that is best for every system. SJF can minimise average waiting time when burst times are known, while Round Robin is designed for time-sharing systems where processes need regular CPU access. Multilevel Feedback Queue can adapt scheduling decisions based on process behaviour and is used in general-purpose operating systems.
4. How do you calculate average waiting time in CPU scheduling?
Calculate the waiting time for each process using WT = TAT − BT, where TAT is turnaround time, and BT is burst time. Add the waiting times of all processes and divide the total by the number of processes. In the FCFS example above, the waiting times are 0, 4, 6, and 6, giving an average waiting time of 4.00 units.
5. What is the convoy effect in CPU scheduling?
The convoy effect occurs when a long process gets the CPU before several shorter processes, forcing those shorter processes to wait. It can occur in FCFS because processes are executed in arrival order. When a long process is at the front of the queue, processes arriving behind it cannot execute until that process finishes.
6. Which CPU scheduling algorithms can cause starvation?
Starvation can occur in SJF, SRTF, and priority scheduling when a process continues to wait because other processes are repeatedly selected before it. Ageing prevents a process from being overlooked indefinitely by gradually increasing its priority while it waits. Once its priority becomes high enough, the process gets an opportunity to execute.
7. What is time quantum in Round Robin scheduling?
The time quantum is the fixed amount of CPU time allocated to a process during one turn in Round Robin scheduling. If the process does not finish within that time, it returns to the ready queue. A very small quantum increases context-switching overhead, while a very large quantum makes Round Robin approach FCFS behaviour.




